init
This commit is contained in:
 CakeCN
32
AlgoriAgent/docs/sphinx_doc/Makefile
Normal file
32
AlgoriAgent/docs/sphinx_doc/Makefile
Normal file
@@ -0,0 +1,32 @@
|
||||
# Makefile
|
||||
|
||||
SPHINXBUILD = sphinx-build
|
||||
SPHINXPROJ = AgentScope-Doc
|
||||
ASSETSDIR = assets
|
||||
BUILDDIR = build/html
|
||||
SOURCEDIR_EN = en/source
|
||||
BUILDDIR_EN = build/html/en
|
||||
SOURCEDIR_ZH = zh_CN/source
|
||||
BUILDDIR_ZH = build/html/zh_CN
|
||||
|
||||
# English document
|
||||
en:
|
||||
@$(SPHINXBUILD) -b html "$(SOURCEDIR_EN)" "$(BUILDDIR_EN)"
|
||||
@echo
|
||||
@echo "Build finished. The HTML pages are in $(BUILDDIR_EN)"
|
||||
|
||||
# Chinese document
|
||||
zh_CN:
|
||||
@$(SPHINXBUILD) -b html "$(SOURCEDIR_ZH)" "$(BUILDDIR_ZH)"
|
||||
@echo
|
||||
@echo "Build finished. The HTML pages are in $(BUILDDIR_ZH)"
|
||||
|
||||
index:
|
||||
@cp "$(ASSETSDIR)/redirect.html" "$(BUILDDIR)/index.html"
|
||||
|
||||
%: Makefile
|
||||
@$(SPHINXBUILD) -M $@ "$(SOURCEDIR_EN)" "$(BUILDDIR_EN)" $(O)
|
||||
|
||||
all: en zh_CN index
|
||||
|
||||
.PHONY: all en zh_CN index
|
||||
12
AlgoriAgent/docs/sphinx_doc/assets/redirect.html
Normal file
12
AlgoriAgent/docs/sphinx_doc/assets/redirect.html
Normal file
@@ -0,0 +1,12 @@
|
||||
<!DOCTYPE html>
|
||||
<html>
|
||||
<head>
|
||||
<meta charset="utf-8" />
|
||||
<meta http-equiv="refresh" content="0; url=en/index.html" />
|
||||
<title>AgentScope Documentation</title>
|
||||
</head>
|
||||
<body>
|
||||
<p>Redirecting to English documentation...</p>
|
||||
<p>If you are not redirected, <a href="en/index.html">click here</a>.</p>
|
||||
</body>
|
||||
</html>
|
||||
4
AlgoriAgent/docs/sphinx_doc/build_sphinx_doc.sh
Normal file
4
AlgoriAgent/docs/sphinx_doc/build_sphinx_doc.sh
Normal file
@@ -0,0 +1,4 @@
|
||||
#!/bin/bash
|
||||
sphinx-apidoc -f -o en/source ../../src/agentscope -t template -e
|
||||
sphinx-apidoc -f -o zh_CN/source ../../src/agentscope -t template -e
|
||||
make clean all
|
||||
4
AlgoriAgent/docs/sphinx_doc/en/source/_static/custom.css
Normal file
4
AlgoriAgent/docs/sphinx_doc/en/source/_static/custom.css
Normal file
@@ -0,0 +1,4 @@
|
||||
.language-selector a {
|
||||
color: white;
|
||||
width: 20px;
|
||||
}
|
||||
@@ -0,0 +1,5 @@
|
||||
<!-- language_selector.html -->
|
||||
<div class="language-selector">
|
||||
<a href="{{ pathto('../en/' + pagename) }}">English</a></li> |
|
||||
<a href="{{ pathto('../zh_CN/' + pagename) }}">中文</a></li>
|
||||
</div>
|
||||
@@ -0,0 +1,3 @@
|
||||
<!-- layout.html -->
|
||||
{% extends "!layout.html" %} {% block sidebartitle %} {{ super() }} {% include
|
||||
"language_selector.html" %} {% endblock %}
|
||||
93
AlgoriAgent/docs/sphinx_doc/en/source/conf.py
Normal file
93
AlgoriAgent/docs/sphinx_doc/en/source/conf.py
Normal file
@@ -0,0 +1,93 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Configuration file for the Sphinx documentation builder.
|
||||
#
|
||||
# This file only contains a selection of the most common options. For a full
|
||||
# list see the documentation:
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html
|
||||
|
||||
# -- Path setup --------------------------------------------------------------
|
||||
|
||||
# If extensions (or modules to document with autodoc) are in another directory,
|
||||
# add these directories to sys.path here. If the directory is relative to the
|
||||
# documentation root, use os.path.abspath to make it absolute, like shown here.
|
||||
#
|
||||
# import os
|
||||
# import sys
|
||||
|
||||
# sys.path.insert(0, os.path.abspath("../../../src/agentscope"))
|
||||
|
||||
|
||||
# -- Project information -----------------------------------------------------
|
||||
|
||||
language = "en"
|
||||
|
||||
project = "AgentScope"
|
||||
copyright = "2024, Alibaba Tongyi Lab"
|
||||
author = "SysML team of Alibaba Tongyi Lab"
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
|
||||
# Add any Sphinx extension module names here, as strings. They can be
|
||||
# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
|
||||
# ones.
|
||||
extensions = [
|
||||
"sphinx.ext.autodoc",
|
||||
"sphinx.ext.autosummary",
|
||||
"sphinx.ext.viewcode",
|
||||
"sphinx.ext.napoleon",
|
||||
"sphinxcontrib.mermaid",
|
||||
"myst_parser",
|
||||
"sphinx.ext.autosectionlabel",
|
||||
]
|
||||
|
||||
# Prefix document path to section labels, otherwise autogenerated labels would
|
||||
# look like 'heading' rather than 'path/to/file:heading'
|
||||
autosectionlabel_prefix_document = True
|
||||
autosummary_generate = True
|
||||
autosummary_ignore_module_all = False
|
||||
|
||||
autodoc_member_order = "bysource"
|
||||
|
||||
autodoc_default_options = {
|
||||
"members": True,
|
||||
"special-members": "__init__",
|
||||
}
|
||||
|
||||
# Add any paths that contain templates here, relative to this directory.
|
||||
templates_path = ["_templates"]
|
||||
|
||||
# List of patterns, relative to source directory, that match files and
|
||||
# directories to ignore when looking for source files.
|
||||
# This pattern also affects html_static_path and html_extra_path.
|
||||
exclude_patterns = ["_build", "Thumbs.db", ".DS_Store"]
|
||||
|
||||
autodoc_default_options = {
|
||||
"members": True,
|
||||
"special-members": "__init__",
|
||||
}
|
||||
|
||||
# -- Options for HTML output -------------------------------------------------
|
||||
|
||||
# The theme to use for HTML and HTML Help pages. See the documentation for
|
||||
# a list of builtin themes.
|
||||
#
|
||||
html_theme = "sphinx_rtd_theme"
|
||||
|
||||
# Add any paths that contain custom static files (such as style sheets) here,
|
||||
# relative to this directory. They are copied after the builtin static files,
|
||||
# so a file named "default.css" will overwrite the builtin "default.css".
|
||||
html_static_path = ["_static"]
|
||||
|
||||
html_theme_options = {
|
||||
"navigation_depth": 2,
|
||||
}
|
||||
|
||||
source_suffix = {
|
||||
".rst": "restructuredtext",
|
||||
".md": "markdown",
|
||||
}
|
||||
|
||||
html_css_files = [
|
||||
"custom.css",
|
||||
]
|
||||
61
AlgoriAgent/docs/sphinx_doc/en/source/index.rst
Normal file
61
AlgoriAgent/docs/sphinx_doc/en/source/index.rst
Normal file
@@ -0,0 +1,61 @@
|
||||
.. AgentScope documentation master file, created by
|
||||
sphinx-quickstart on Fri Jan 5 17:53:54 2024.
|
||||
You can adapt this file completely to your liking, but it should at least
|
||||
contain the root `toctree` directive.
|
||||
|
||||
:github_url: https://github.com/modelscope/agentscope
|
||||
|
||||
AgentScope Documentation
|
||||
======================================
|
||||
|
||||
|
||||
.. include:: tutorial/main.md
|
||||
:parser: myst_parser.sphinx_
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 1
|
||||
:glob:
|
||||
:hidden:
|
||||
:caption: AgentScope Tutorial
|
||||
|
||||
tutorial/101-agentscope.md
|
||||
tutorial/102-installation.md
|
||||
tutorial/103-example.md
|
||||
|
||||
tutorial/203-model.md
|
||||
tutorial/206-prompt.md
|
||||
tutorial/201-agent.md
|
||||
tutorial/205-memory.md
|
||||
tutorial/203-parser.md
|
||||
tutorial/209-prompt_opt.md
|
||||
tutorial/204-service.md
|
||||
tutorial/202-pipeline.md
|
||||
tutorial/208-distribute.md
|
||||
tutorial/209-gui.md
|
||||
tutorial/210-rag.md
|
||||
tutorial/105-logging.md
|
||||
tutorial/207-monitor.md
|
||||
tutorial/104-usecase.md
|
||||
|
||||
tutorial/contribute.rst
|
||||
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 1
|
||||
:glob:
|
||||
:caption: AgentScope API Reference
|
||||
|
||||
agentscope
|
||||
agentscope.message
|
||||
agentscope.models
|
||||
agentscope.agents
|
||||
agentscope.memory
|
||||
agentscope.parsers
|
||||
agentscope.exception
|
||||
agentscope.pipelines
|
||||
agentscope.service
|
||||
agentscope.rpc
|
||||
agentscope.server
|
||||
agentscope.web
|
||||
agentscope.prompt
|
||||
agentscope.utils
|
||||
116
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/101-agentscope.md
Normal file
116
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/101-agentscope.md
Normal file
@@ -0,0 +1,116 @@
|
||||
(101-agentscope-en)=
|
||||
|
||||
# About AgentScope
|
||||
|
||||
In this tutorial, we will provide an overview of AgentScope by answering
|
||||
several questions, including what's AgentScope, what can AgentScope provide,
|
||||
and why we should choose AgentScope. Let's get started!
|
||||
|
||||
## What is AgentScope?
|
||||
|
||||
AgentScope is a developer-centric multi-agent platform, which enables
|
||||
developers to build their LLM-empowered multi-agent applications with less
|
||||
effort.
|
||||
|
||||
With the advance of large language models, developers are able to build
|
||||
diverse applications.
|
||||
In order to connect LLMs to data and services and solve complex tasks,
|
||||
AgentScope provides a series of development tools and components for ease of
|
||||
development.
|
||||
It features
|
||||
|
||||
- **usability**,
|
||||
- **robustness**,
|
||||
- **the support of multi-modal data**,
|
||||
- **distributed deployment**.
|
||||
|
||||
## Key Concepts
|
||||
|
||||
### Message
|
||||
|
||||
Message is a carrier of information (e.g. instructions, multi-modal
|
||||
data, and dialogue). In AgentScope, message is a Python dict subclass
|
||||
with `name` and `content` as necessary fields, and `url` as an optional
|
||||
field referring to additional resources.
|
||||
|
||||
### Agent
|
||||
|
||||
Agent is an autonomous entity capable of interacting with environment and
|
||||
agents, and taking actions to change the environment. In AgentScope, an
|
||||
agent takes message as input and generates corresponding response message.
|
||||
|
||||
### Service
|
||||
|
||||
Service refers to the functional APIs that enable agents to perform
|
||||
specific tasks. In AgentScope, services are categorized into model API
|
||||
services, which are channels to use the LLMs, and general API services,
|
||||
which provide a variety of tool functions.
|
||||
|
||||
### Workflow
|
||||
|
||||
Workflow represents ordered sequences of agent executions and message
|
||||
exchanges between agents, analogous to computational graphs in TensorFlow,
|
||||
but with the flexibility to accommodate non-DAG structures.
|
||||
|
||||
## Why AgentScope?
|
||||
|
||||
**Exceptional usability for developers.**
|
||||
AgentScope provides high usability for developers with flexible syntactic
|
||||
sugars, ready-to-use components, and pre-built examples.
|
||||
|
||||
**Robust fault tolerance for diverse models and APIs.**
|
||||
AgentScope ensures robust fault tolerance for diverse models, APIs, and
|
||||
allows developers to build customized fault-tolerant strategies.
|
||||
|
||||
**Extensive compatibility for multi-modal application.**
|
||||
AgentScope supports multi-modal data (e.g., files, images, audio and videos)
|
||||
in both dialog presentation, message transmission and data storage.
|
||||
|
||||
**Optimized efficiency for distributed multi-agent operations.** AgentScope
|
||||
introduces an actor-based distributed mechanism that enables centralized
|
||||
programming of complex distributed workflows, and automatic parallel
|
||||
optimization.
|
||||
|
||||
## How is AgentScope designed?
|
||||
|
||||
The architecture of AgentScope comprises three hierarchical layers. The
|
||||
layers provide supports for multi-agent applications from different levels,
|
||||
including elementary and advanced functionalities of a single agent
|
||||
(**utility layer**), resources and runtime management (**manager and wrapper
|
||||
layer**), and agent-level to workflow-level programming interfaces (**agent
|
||||
layer**). AgentScope introduces intuitive abstractions designed to fulfill
|
||||
the diverse functionalities inherent to each layer and simplify the
|
||||
complicated interlayer dependencies when building multi-agent systems.
|
||||
Furthermore, we offer programming interfaces and default mechanisms to
|
||||
strengthen the resilience of multi-agent systems against faults within
|
||||
different layers.
|
||||
|
||||
## AgentScope Code Structure
|
||||
|
||||
```bash
|
||||
AgentScope
|
||||
├── src
|
||||
│ ├── agentscope
|
||||
│ | ├── agents # Core components and implementations pertaining to agents.
|
||||
│ | ├── memory # Structures for agent memory.
|
||||
│ | ├── models # Interfaces for integrating diverse model APIs.
|
||||
│ | ├── pipelines # Fundamental components and implementations for running pipelines.
|
||||
│ | ├── rpc # Rpc module for agent distributed deployment.
|
||||
│ | ├── service # Services offering functions independent of memory and state.
|
||||
| | ├── web # WebUI used to show dialogs.
|
||||
│ | ├── utils # Auxiliary utilities and helper functions.
|
||||
│ | ├── message.py # Definitions and implementations of messaging between agents.
|
||||
│ | ├── prompt.py # Prompt engineering module for model input.
|
||||
│ | ├── ... ..
|
||||
│ | ├── ... ..
|
||||
├── scripts # Scripts for launching local Model API
|
||||
├── examples # Pre-built examples of different applications.
|
||||
├── docs # Documentation tool for API reference.
|
||||
├── tests # Unittest modules for continuous integration.
|
||||
├── LICENSE # The official licensing agreement for AgentScope usage.
|
||||
└── setup.py # Setup script for installing.
|
||||
├── ... ..
|
||||
└── ... ..
|
||||
```
|
||||
|
||||
[[Return to the top]](#101-agentscope)
|
||||
@@ -0,0 +1,68 @@
|
||||
(102-installation-en)=
|
||||
|
||||
# Installation
|
||||
|
||||
To install AgentScope, you need to have Python 3.9 or higher installed. We recommend setting up a new virtual environment specifically for AgentScope:
|
||||
|
||||
## Create a Virtual Environment
|
||||
|
||||
### Using Conda
|
||||
|
||||
If you're using Conda as your package and environment management tool, you can create a new virtual environment with Python 3.9 using the following commands:
|
||||
|
||||
```bash
|
||||
# Create a new virtual environment named 'agentscope' with Python 3.9
|
||||
conda create -n agentscope python=3.9
|
||||
|
||||
# Activate the virtual environment
|
||||
conda activate agentscope
|
||||
```
|
||||
|
||||
### Using Virtualenv
|
||||
|
||||
Alternatively, if you prefer `virtualenv`, you can install it first (if it's not already installed) and then create a new virtual environment as shown:
|
||||
|
||||
```bash
|
||||
# Install virtualenv if it is not already installed
|
||||
pip install virtualenv
|
||||
|
||||
# Create a new virtual environment named 'agentscope' with Python 3.9
|
||||
virtualenv agentscope --python=python3.9
|
||||
|
||||
# Activate the virtual environment
|
||||
source agentscope/bin/activate # On Windows use `agentscope\Scripts\activate`
|
||||
```
|
||||
|
||||
## Installing AgentScope
|
||||
|
||||
### Install with Pip
|
||||
|
||||
If you prefer to install AgentScope from Pypi, you can do so easily using `pip`:
|
||||
|
||||
```bash
|
||||
# For centralized multi-agent applications
|
||||
pip install agentscope --pre
|
||||
# For distributed multi-agent applications
|
||||
pip install agentscope[distribute] --pre # On Mac use `pip install agentscope\[distribute\] --pre`
|
||||
```
|
||||
|
||||
### Install from Source
|
||||
|
||||
For users who prefer to install AgentScope directly from the source code, follow these steps to clone the repository and install the platform in editable mode:
|
||||
|
||||
**_Note: This project is under active development, it's recommended to install AgentScope from source._**
|
||||
|
||||
```bash
|
||||
# Pull the source code from Github
|
||||
git clone https://github.com/modelscope/agentscope.git
|
||||
cd agentscope
|
||||
|
||||
# For centralized multi-agent applications
|
||||
pip install -e .
|
||||
# For distributed multi-agent applications
|
||||
pip install -e .[distribute] # On Mac use `pip install -e .\[distribute\]`
|
||||
```
|
||||
|
||||
**Note**: The `[distribute]` option installs additional dependencies required for distributed applications. Remember to activate your virtual environment before running these commands.
|
||||
|
||||
[[Return to the top]](#102-installation-en)
|
||||
108
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/103-example.md
Normal file
108
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/103-example.md
Normal file
@@ -0,0 +1,108 @@
|
||||
(103-start-en)=
|
||||
|
||||
# Quick Start
|
||||
|
||||
AgentScope is designed with a flexible communication mechanism.
|
||||
In this tutorial, we will introduce the basic usage of AgentScope via a
|
||||
simple standalone conversation between two agents (e.g. user and assistant
|
||||
agents).
|
||||
|
||||
## Step1: Prepare Model
|
||||
|
||||
AgentScope decouples the deployment and invocation of models to better build multi-agent applications.
|
||||
|
||||
In terms of model deployment, users can use third-party model services such
|
||||
as OpenAI API, Google Gemini API, HuggingFace/ModelScope Inference API, or
|
||||
quickly deploy local open-source model services through the [scripts](https://github.com/modelscope/agentscope/blob/main/scripts/README.md) in
|
||||
the repository.
|
||||
|
||||
While for model invocation, users should prepare a model configuration to specify the model service. Taking OpenAI Chat API as an example, the model configuration is like this:
|
||||
|
||||
```python
|
||||
model_config = {
|
||||
"config_name": "{config_name}", # A unique name for the model config.
|
||||
"model_type": "openai_chat", # Choose from "openai_chat", "openai_dall_e", or "openai_embedding".
|
||||
|
||||
"model_name": "{model_name}", # The model identifier used in the OpenAI API, such as "gpt-3.5-turbo", "gpt-4", or "text-embedding-ada-002".
|
||||
"api_key": "xxx", # Your OpenAI API key. If unset, the environment variable OPENAI_API_KEY is used.
|
||||
"organization": "xxx", # Your OpenAI organization ID. If unset, the environment variable OPENAI_ORGANIZATION is used.
|
||||
}
|
||||
```
|
||||
|
||||
More details about model invocation, deployment and open-source models please refer to [Model](203-model-en) section.
|
||||
|
||||
After preparing the model configuration, you can register your configuration by calling the `init` method of AgentScope. Additionally, you can load multiple model configurations at once.
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
# init once by passing a list of config dict
|
||||
openai_cfg_dict = {
|
||||
# ...
|
||||
}
|
||||
modelscope_cfg_dict = {
|
||||
# ...
|
||||
}
|
||||
agentscope.init(model_configs=[openai_cfg_dict, modelscope_cfg_dict])
|
||||
```
|
||||
|
||||
## Step2: Create Agents
|
||||
|
||||
Creating agents is straightforward in AgentScope. After initializing AgentScope with your model configurations (Step 1 above), you can then define each agent with its corresponding role and specific model.
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
from agentscope.agents import DialogAgent, UserAgent
|
||||
|
||||
# read model configs
|
||||
agentscope.init(model_configs="./openai_model_configs.json")
|
||||
|
||||
# Create a dialog agent and a user agent
|
||||
dialogAgent = DialogAgent(name="assistant", model_config_name="gpt-4", sys_prompt="You are a helpful ai assistant")
|
||||
userAgent = UserAgent()
|
||||
```
|
||||
|
||||
**NOTE**: Please refer to [Customizing Your Own Agent](201-agent-en) for all available agents.
|
||||
|
||||
## Step3: Agent Conversation
|
||||
|
||||
"Message" is the primary means of communication between agents in AgentScope. They are Python dictionaries comprising essential fields like the actual `content` of this message and the sender's `name`. Optionally, a message can include a `url` to either a local file (image, video or audio) or website.
|
||||
|
||||
```python
|
||||
from agentscope.message import Msg
|
||||
|
||||
# Example of a simple text message from Alice
|
||||
message_from_alice = Msg("Alice", "Hi!")
|
||||
|
||||
# Example of a message from Bob with an attached image
|
||||
message_from_bob = Msg("Bob", "What about this picture I took?", url="/path/to/picture.jpg")
|
||||
```
|
||||
|
||||
To start a conversation between two agents, such as `dialog_agent` and `user_agent`, you can use the following loop. The conversation continues until the user inputs `"exit"` which terminates the interaction.
|
||||
|
||||
```python
|
||||
x = None
|
||||
while True:
|
||||
x = dialogAgent(x)
|
||||
x = userAgent(x)
|
||||
|
||||
# Terminate the conversation if the user types "exit"
|
||||
if x.content == "exit":
|
||||
print("Exiting the conversation.")
|
||||
break
|
||||
```
|
||||
|
||||
For a more advanced approach, AgentScope offers the option of using pipelines to manage the flow of messages between agents. The `sequentialpipeline` stands for sequential speech, where each agent receive message from last agent and generate its response accordingly.
|
||||
|
||||
```python
|
||||
from agentscope.pipelines.functional import sequentialpipeline
|
||||
|
||||
# Execute the conversation loop within a pipeline structure
|
||||
x = None
|
||||
while x is None or x.content != "exit":
|
||||
x = sequentialpipeline([dialog_agent, user_agent])
|
||||
```
|
||||
|
||||
For more details about how to utilize pipelines for complex agent interactions, please refer to [Pipeline and MsgHub](202-pipeline-en).
|
||||
|
||||
[[Return to the top]](#103-start-en)
|
||||
302
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/104-usecase.md
Normal file
302
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/104-usecase.md
Normal file
@@ -0,0 +1,302 @@
|
||||
(104-usecase-en)=
|
||||
|
||||
# Example: Werewolf Game
|
||||
|
||||
<img src="https://img.alicdn.com/imgextra/i3/O1CN01dFpOh82643mygUh2Z_!!6000000007607-2-tps-1024-1024.png" alt="img" style="zoom:25%;" />
|
||||
|
||||
**Werewolf** is a well-known social-deduction game, that involves an imaginary village where a few villagers are secretly werewolves, and the objective is to identify who they are before they eliminate all other players. It's a good use case to demonstrate the interaction between multiple autonomous agents, each with its own objectives and the need for communication.
|
||||
|
||||
Let the adventure begin to unlock the potential of multi-agent applications with AgentScope!
|
||||
|
||||
## Getting Started
|
||||
|
||||
Firstly, ensure that you have installed and configured AgentScope properly. Besides, we will involve the basic concepts of `Model API`, `Agent`, `Msg`, and `Pipeline,` as described in [Tutorial-Concept](101-agentscope.md).
|
||||
|
||||
**Note**: all the configurations and code for this tutorial can be found in `examples/game_werewolf`.
|
||||
|
||||
### Step 1: Prepare Model API and Set Model Configs
|
||||
|
||||
As we discussed in the last tutorial, you need to prepare your model configurations into a JSON file for standard OpenAI chat API, FastChat, and vllm. More details and advanced usages such as configuring local models with POST API are presented in [Tutorial-Model-API](203-model.md).
|
||||
|
||||
```json
|
||||
[
|
||||
{
|
||||
"config_name": "gpt-4-temperature-0.0",
|
||||
"model_type": "openai_chat",
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
"organization": "xxx",
|
||||
"generate_args": {
|
||||
"temperature": 0.0
|
||||
}
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### Step 2: Define the Roles of Each Agent
|
||||
|
||||
In the Werewolf game, agents assume a variety of roles, each endowed with distinctive abilities and objectives. Below, we will outline the agent classes corresponding to each role:
|
||||
|
||||
- Villager: Ordinary townsfolk trying to survive.
|
||||
- Werewolf: Predators in disguise, aiming to outlast the villagers.
|
||||
- Seer: A villager with the power to see the true nature of one player each night.
|
||||
- Witch: A villager who can save or poison a player each night.
|
||||
|
||||
To implement your own agent, you need to inherit `AgentBase` and implement the `reply` function, which is executed when an agent instance is called via `agent1(x)`.
|
||||
|
||||
```python
|
||||
from agentscope.agents import AgentBase
|
||||
from agentscope.message import Msg
|
||||
|
||||
|
||||
from typing import Optional, Union, Sequence
|
||||
|
||||
class MyAgent(AgentBase):
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# Do something here
|
||||
...
|
||||
return x
|
||||
```
|
||||
|
||||
AgentScope provides several out-of-the-box Agents implements and organizes them as an *Agent Pool*. In this application, we use a built-in agent, `DictDialogAgent`. Here we give an example configuration of `DictDialogAgent` for a player assigned as the role of a werewolf:
|
||||
|
||||
```json
|
||||
{
|
||||
"class": "DictDialogAgent",
|
||||
"args": {
|
||||
"name": "Player1",
|
||||
"sys_prompt": "Act as a player in a werewolf game. You are Player1 and\nthere are totally 6 players, named Player1, Player2, Player3, Player4, Player5 and Player6.\n\nPLAYER ROLES:\nIn werewolf game, players are divided into two werewolves, two villagers, one seer, and one witch. Note only werewolves know who are their teammates.\nWerewolves: They know their teammates' identities and attempt to eliminate a villager each night while trying to remain undetected.\nVillagers: They do not know who the werewolves are and must work together during the day to deduce who the werewolves might be and vote to eliminate them.\nSeer: A villager with the ability to learn the true identity of one player each night. This role is crucial for the villagers to gain information.\nWitch: A character who has a one-time ability to save a player from being eliminated at night (sometimes this is a potion of life) and a one-time ability to eliminate a player at night (a potion of death).\n\nGAME RULE:\nThe game consists of two phases: night phase and day phase. The two phases are repeated until werewolf or villager wins the game.\n1. Night Phase: During the night, the werewolves discuss and vote for a player to eliminate. Special roles also perform their actions at this time (e.g., the Seer chooses a player to learn their role, the witch chooses a decide if save the player).\n2. Day Phase: During the day, all surviving players discuss who they suspect might be a werewolf. No one reveals their role unless it serves a strategic purpose. After the discussion, a vote is taken, and the player with the most votes is \"lynched\" or eliminated from the game.\n\nVICTORY CONDITION:\nFor werewolves, they win the game if the number of werewolves is equal to or greater than the number of remaining villagers.\nFor villagers, they win if they identify and eliminate all of the werewolves in the group.\n\nCONSTRAINTS:\n1. Your response should be in the first person.\n2. This is a conversational game. You should respond only based on the conversation history and your strategy.\n\nYou are playing werewolf in this game.\n",
|
||||
"model_config_name": "gpt-3.5-turbo",
|
||||
"use_memory": true
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
In this configuration, `Player1` is designated as a `DictDialogAgent`. The parameters include a system prompt (`sys_prompt`) that can guide the agent's behavior, a model config name (`model_config_name`) that determines the name of the model configuration, and a flag (`use_memory`) indicating whether the agent should remember past interactions.
|
||||
|
||||
For other players, configurations can be customized based on their roles. Each role may have different prompts, models, or memory settings. You can refer to the JSON file located at `examples/game_werewolf/configs/agent_configs.json` within the AgentScope examples directory.
|
||||
|
||||
### Step 3: Initialize AgentScope and the Agents
|
||||
|
||||
Now we have defined the roles in the application and we can initialize the AgentScope environment and all agents. This process is simplified by AgentScope via a few lines, based on the configuration files we've prepared (assuming there are **2** werewolves, **2** villagers, **1** witch, and **1** seer):
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
# read model and agent configs, and initialize agents automatically
|
||||
survivors = agentscope.init(
|
||||
model_configs="./configs/model_configs.json",
|
||||
agent_configs="./configs/agent_configs.json",
|
||||
logger_level="DEBUG",
|
||||
)
|
||||
|
||||
# Define the roles within the game. This list should match the order and number
|
||||
# of agents specified in the 'agent_configs.json' file.
|
||||
roles = ["werewolf", "werewolf", "villager", "villager", "seer", "witch"]
|
||||
|
||||
# Based on their roles, assign the initialized agents to variables.
|
||||
# This helps us reference them easily in the game logic.
|
||||
wolves, villagers, witch, seer = survivors[:2], survivors[2:-2], survivors[-1], survivors[-2]
|
||||
```
|
||||
|
||||
Through this snippet of code, we've allocated roles to our agents and associated them with the configurations that dictate their behavior in the application.
|
||||
|
||||
### Step 4: Set Up the Game Logic
|
||||
|
||||
In this step, you will set up the game logic and orchestrate the flow of the Werewolf game using AgentScope's helper utilities.
|
||||
|
||||
#### Parser
|
||||
|
||||
In order to allow `DictDialogAgent` to output fields customized by the users, and to increase the success rate of parsing different fields by LLMs, we have added the `parser` module. Here is the configuration of a parser example:
|
||||
|
||||
```
|
||||
to_wolves_vote = "Which player do you vote to kill?"
|
||||
|
||||
wolves_vote_parser = MarkdownJsonDictParser(
|
||||
content_hint={
|
||||
"thought": "what you thought",
|
||||
"vote": "player_name",
|
||||
},
|
||||
required_keys=["thought", "vote"],
|
||||
keys_to_memory="vote",
|
||||
keys_to_content="vote",
|
||||
)
|
||||
```
|
||||
|
||||
For more details about the `parser` module,please see [here](https://modelscope.github.io/agentscope/en/tutorial/203-parser.html).
|
||||
|
||||
#### Leverage Pipeline and MsgHub
|
||||
|
||||
To simplify the construction of agent communication, AgentScope provides two helpful concepts: **Pipeline** and **MsgHub**.
|
||||
|
||||
- **Pipeline**: It allows users to program communication among agents easily.
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SequentialPipeline
|
||||
|
||||
pipe = SequentialPipeline(agent1, agent2, agent3)
|
||||
x = pipe(x) # the message x will be passed and replied by agent 1,2,3 in order
|
||||
```
|
||||
|
||||
- **MsgHub**: You may have noticed that all the above examples are one-to-one communication. To achieve a group chat, we provide another communication helper utility `msghub`. With it, the messages from participants will be broadcast to all other participants automatically. In such cases, participating agents even don't need input and output messages. All we need to do is to decide the order of speaking. Besides, `msghub` also supports dynamic control of participants.
|
||||
|
||||
```python
|
||||
with msghub(participants=[agent1, agent2, agent3]) as hub:
|
||||
agent1()
|
||||
agent2()
|
||||
|
||||
# Broadcast a message to all participants
|
||||
hub.broadcast(Msg("Host", "Welcome to join the group chat!"))
|
||||
|
||||
# Add or delete participants dynamically
|
||||
hub.delete(agent1)
|
||||
hub.add(agent4)
|
||||
```
|
||||
|
||||
#### Implement Werewolf Pipeline
|
||||
|
||||
The game logic is divided into two major phases: (1) night when werewolves act, and (2) daytime when all players discuss and vote. Each phase will be handled by a section of code using pipelines to manage multi-agent communications.
|
||||
|
||||
- **1.1 Night Phase: Werewolves Discuss and Vote**
|
||||
|
||||
During the night phase, werewolves must discuss among themselves to decide on a target. The `msghub` function creates a message hub for the werewolves to communicate in, where every message sent by an agent is observable by all other agents within the `msghub`.
|
||||
|
||||
```python
|
||||
# start the game
|
||||
for i in range(1, MAX_GAME_ROUND + 1):
|
||||
# Night phase: werewolves discuss
|
||||
hint = HostMsg(content=Prompts.to_wolves.format(n2s(wolves)))
|
||||
with msghub(wolves, announcement=hint) as hub:
|
||||
set_parsers(wolves, Prompts.wolves_discuss_parser)
|
||||
for _ in range(MAX_WEREWOLF_DISCUSSION_ROUND):
|
||||
x = sequentialpipeline(wolves)
|
||||
if x.metadata.get("finish_discussion", False):
|
||||
break
|
||||
```
|
||||
|
||||
After the discussion, werewolves proceed to vote for their target, and the majority's choice is determined. The result of the vote is then broadcast to all werewolves.
|
||||
|
||||
**Note**: the detailed prompts and utility functions can be found in `examples/game_werewolf`.
|
||||
|
||||
```python
|
||||
# werewolves vote
|
||||
set_parsers(wolves, Prompts.wolves_vote_parser)
|
||||
hint = HostMsg(content=Prompts.to_wolves_vote)
|
||||
votes = [extract_name_and_id(wolf(hint).content)[0] for wolf in wolves]
|
||||
# broadcast the result to werewolves
|
||||
dead_player = [majority_vote(votes)]
|
||||
hub.broadcast(
|
||||
HostMsg(content=Prompts.to_wolves_res.format(dead_player[0])),
|
||||
)
|
||||
```
|
||||
|
||||
- **1.2 Witch's Turn**
|
||||
|
||||
If the witch is still alive, she gets the opportunity to use her powers to either save the player chosen by the werewolves or use her poison.
|
||||
|
||||
```python
|
||||
# Witch's turn
|
||||
healing_used_tonight = False
|
||||
if witch in survivors:
|
||||
if healing:
|
||||
# Witch decides whether to use the healing potion
|
||||
hint = HostMsg(
|
||||
content=Prompts.to_witch_resurrect.format_map(
|
||||
{"witch_name": witch.name, "dead_name": dead_player[0]},
|
||||
),
|
||||
)
|
||||
# Witch decides whether to use the poison
|
||||
set_parsers(witch, Prompts.witch_resurrect_parser)
|
||||
if witch(hint).metadata.get("resurrect", False):
|
||||
healing_used_tonight = True
|
||||
dead_player.pop()
|
||||
healing = False
|
||||
```
|
||||
|
||||
- **1.3 Seer's Turn**
|
||||
|
||||
The seer has a chance to reveal the true identity of a player. This information can be crucial for the villagers. The `observe()` function allows each agent to take note of a message without immediately replying to it.
|
||||
|
||||
```python
|
||||
# Seer's turn
|
||||
if seer in survivors:
|
||||
# Seer chooses a player to reveal their identity
|
||||
hint = HostMsg(
|
||||
content=Prompts.to_seer.format(seer.name, n2s(survivors)),
|
||||
)
|
||||
set_parsers(seer, Prompts.seer_parser)
|
||||
x = seer(hint)
|
||||
|
||||
player, idx = extract_name_and_id(x.content)
|
||||
role = "werewolf" if roles[idx] == "werewolf" else "villager"
|
||||
hint = HostMsg(content=Prompts.to_seer_result.format(player, role))
|
||||
seer.observe(hint)
|
||||
```
|
||||
|
||||
- **1.4 Update Alive Players**
|
||||
|
||||
Based on the actions taken during the night, the list of surviving players needs to be updated.
|
||||
|
||||
```python
|
||||
# Update the list of survivors and werewolves after the night's events
|
||||
survivors, wolves = update_alive_players(survivors, wolves, dead_player)
|
||||
```
|
||||
|
||||
- **2.1 Daytime Phase: Discussion and Voting**
|
||||
|
||||
During the day, all players will discuss and then vote to eliminate a suspected werewolf.
|
||||
|
||||
```python
|
||||
# Daytime discussion
|
||||
with msghub(survivors, announcement=hints) as hub:
|
||||
# Discuss
|
||||
set_parsers(survivors, Prompts.survivors_discuss_parser)
|
||||
x = sequentialpipeline(survivors)
|
||||
# Vote
|
||||
set_parsers(survivors, Prompts.survivors_vote_parser)
|
||||
hint = HostMsg(content=Prompts.to_all_vote.format(n2s(survivors)))
|
||||
votes = [extract_name_and_id(_(hint).content)[0] for _ in survivors]
|
||||
vote_res = majority_vote(votes)
|
||||
# Broadcast the voting result to all players
|
||||
result = HostMsg(content=Prompts.to_all_res.format(vote_res))
|
||||
hub.broadcast(result)
|
||||
# Update the list of survivors and werewolves after the vote
|
||||
survivors, wolves = update_alive_players(survivors, wolves, vote_res)
|
||||
```
|
||||
|
||||
- **2.2 Check for Winning Conditions**
|
||||
|
||||
After each phase, the game checks if the werewolves or villagers have won.
|
||||
|
||||
```python
|
||||
# Check if either side has won
|
||||
if check_winning(survivors, wolves, "Moderator"):
|
||||
break
|
||||
```
|
||||
|
||||
- **2.3 Continue to the Next Round**
|
||||
|
||||
If neither werewolves nor villagers win, the game continues to the next round.
|
||||
|
||||
```python
|
||||
# If the game hasn't ended, prepare for the next round
|
||||
hub.broadcast(HostMsg(content=Prompts.to_all_continue))
|
||||
```
|
||||
|
||||
These code blocks outline the core game loop for Werewolf using AgentScope's `msghub` and `pipeline`, which help to easily manage the operational logic of an application.
|
||||
|
||||
### Step 5: Run the Application
|
||||
|
||||
With the game logic and agents set up, you're ready to run the Werewolf game. By executing the `pipeline`, the game will proceed through the predefined phases, with agents interacting based on their roles and the strategies coded above:
|
||||
|
||||
```bash
|
||||
cd examples/game_werewolf
|
||||
python main.py # Assuming the pipeline is implemented in main.py
|
||||
```
|
||||
|
||||
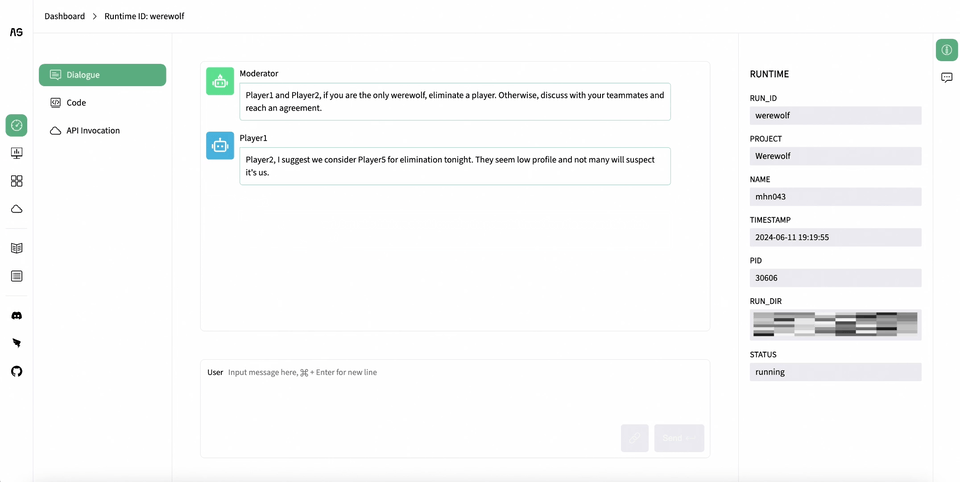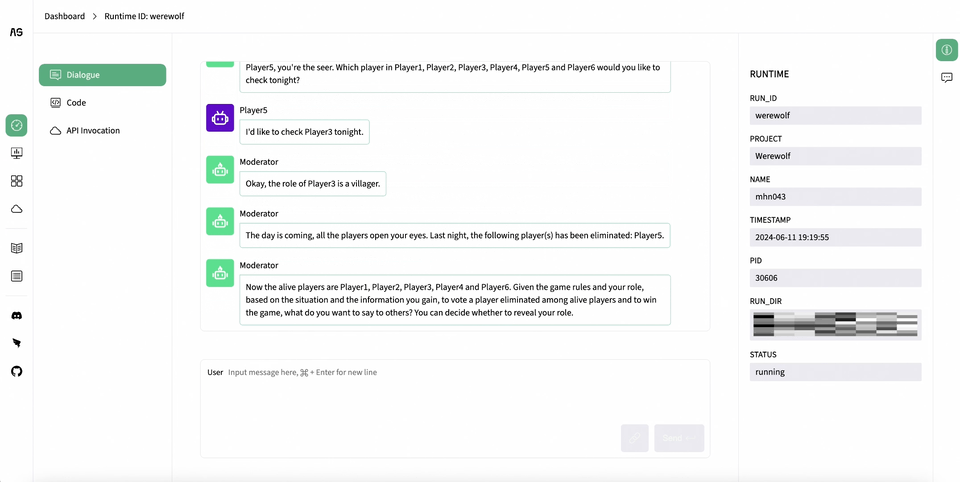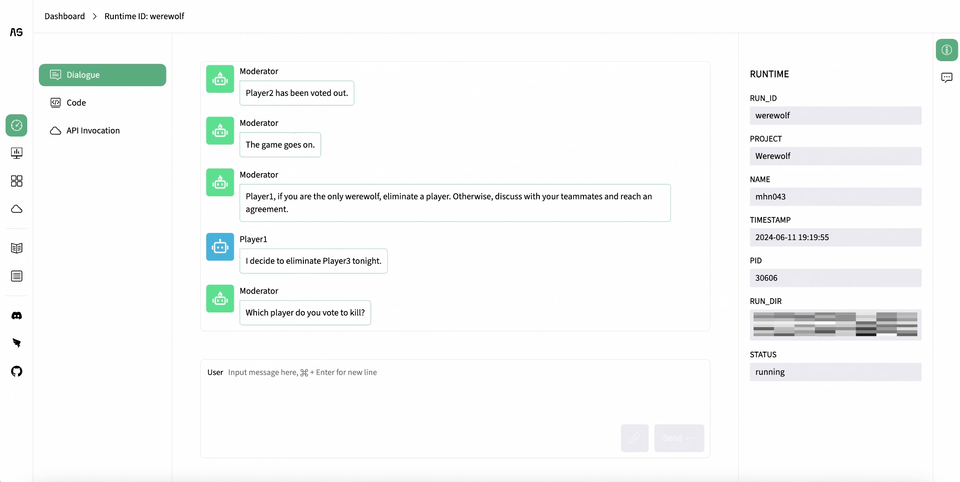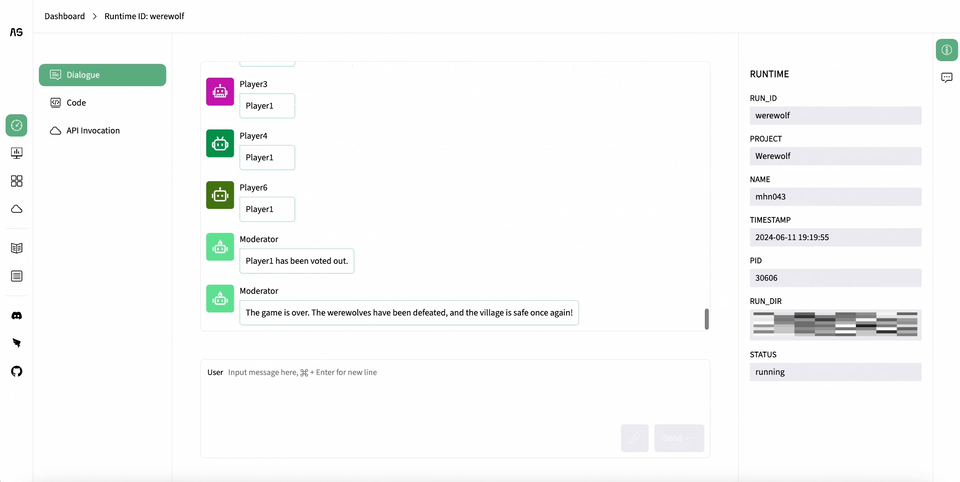
It is recommended that you start the game in [AgentScope Studio](https://modelscope.github.io/agentscope/en/tutorial/209-gui.html), where you
|
||||
will see the following output in the corresponding link:
|
||||
|
||||
|
||||
|
||||
[[Return to the top]](#104-usecase-en)
|
||||
@@ -0,0 +1,65 @@
|
||||
(105-logging-en)=
|
||||
|
||||
# Logging
|
||||
|
||||
Welcome to the tutorial on logging in multi-agent applications with AgentScope. We'll also touch on how you can visualize these logs using a simple web interface. This guide will help you track the agent's interactions and system information in a clearer and more organized way.
|
||||
|
||||
## Logging
|
||||
|
||||
The logging utilities consist of a custom setup for the `loguru.logger`, which is an enhancement over Python's built-in `logging` module. We provide custom features:
|
||||
|
||||
- **Colored Output**: Assigns different colors to different speakers in a chat to enhance readability.
|
||||
- **Redirecting Standard Error (stderr)**: Captures error messages and logs them with the `ERROR` level.
|
||||
- **Custom Log Levels**: Adds a custom level called `CHAT` that is specifically designed for logging dialogue interactions.
|
||||
- **Special Formatting**: Format logs with timestamps, levels, function names, and line numbers. Chat messages are formatted differently to stand out.
|
||||
|
||||
### Setting Up the Logger
|
||||
|
||||
We recommend setting up the logger via `agentscope.init`, and you can set the log level:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
LOG_LEVEL = Literal[
|
||||
"CHAT",
|
||||
"TRACE",
|
||||
"DEBUG",
|
||||
"INFO",
|
||||
"SUCCESS",
|
||||
"WARNING",
|
||||
"ERROR",
|
||||
"CRITICAL",
|
||||
]
|
||||
|
||||
agentscope.init(..., logger_level="INFO")
|
||||
```
|
||||
|
||||
### Logging a Chat Message
|
||||
|
||||
Logging chat messages helps keep a record of the conversation between agents. Here's how you can do it:
|
||||
|
||||
```python
|
||||
# Log a simple string message.
|
||||
logger.chat("Hello World!")
|
||||
|
||||
# Log a `msg` representing dialogue with a speaker and content.
|
||||
logger.chat({"name": "User", "content": "Hello, how are you?"})
|
||||
logger.chat({"name": "Agent", "content": "I'm fine, thank you!"})
|
||||
```
|
||||
|
||||
### Logging a System information
|
||||
|
||||
System logs are crucial for tracking the application's state and identifying issues. Here's how to log different levels of system information:
|
||||
|
||||
```python
|
||||
# Log general information useful for understanding the flow of the application.
|
||||
logger.info("The dialogue agent has started successfully.")
|
||||
|
||||
# Log a warning message indicating a potential issue that isn't immediately problematic.
|
||||
logger.warning("The agent is running slower than expected.")
|
||||
|
||||
# Log an error message when something has gone wrong.
|
||||
logger.error("The agent encountered an unexpected error while processing a request.")
|
||||
```
|
||||
|
||||
[[Return to the top]](#105-logging-en)
|
||||
191
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/201-agent.md
Normal file
191
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/201-agent.md
Normal file
@@ -0,0 +1,191 @@
|
||||
(201-agent-en)=
|
||||
|
||||
# Agent
|
||||
|
||||
This tutorial helps you to understand the `Agent` in more depth and navigate through the process of crafting your own custom agent with AgentScope. We start by introducing the fundamental abstraction called `AgentBase`, which serves as the base class to maintain the general behaviors of all agents. Then, we will go through the *AgentPool*, an ensemble of pre-built, specialized agents, each designed with a specific purpose in mind. Finally, we will demonstrate how to customize your own agent, ensuring it fits the needs of your project.
|
||||
|
||||
## Understanding `AgentBase`
|
||||
|
||||
The `AgentBase` class is the architectural cornerstone for all agent constructs within the AgentScope. As the superclass of all custom agents, it provides a comprehensive template consisting of essential attributes and methods that underpin the core functionalities of any conversational agent.
|
||||
|
||||
Each AgentBase derivative is composed of several key characteristics:
|
||||
|
||||
* `memory`: This attribute enables agents to retain and recall past interactions, allowing them to maintain context in ongoing conversations. For more details about `memory`, we defer to [Memory and Message Management](205-memory).
|
||||
|
||||
* `model`: The model is the computational engine of the agent, responsible for making a response given existing memory and input. For more details about `model`, we defer to [Using Different Model Sources with Model API](#203-model).
|
||||
|
||||
* `sys_prompt` & `engine`: The system prompt acts as predefined instructions that guide the agent in its interactions; and the `engine` is used to dynamically generate a suitable prompt. For more details about them, we defer to [Prompt Engine](206-prompt).
|
||||
|
||||
* `to_dist`: Used to create a distributed version of the agent, to support efficient collaboration among multiple agents. Note that `to_dist` is a reserved field and will be automatically added to the initialization function of any subclass of `AgentBase`. For more details about `to_dist`, please refer to [Distribution](208-distribute).
|
||||
|
||||
In addition to these attributes, `AgentBase` endows agents with pivotal methods such as `observe` and `reply`:
|
||||
|
||||
* `observe()`: Through this method, an agent can take note of *message* without immediately replying, allowing it to update its memory based on the observed *message*.
|
||||
* `reply()`: This is the primary method that developers must implement. It defines the agent's behavior in response to an incoming *message*, encapsulating the logic that results in the agent's output.
|
||||
|
||||
Besides, for unified interfaces and type hints, we introduce another base class `Operator`, which indicates performing some operation on input data by the `__call__` function. And we make `AgentBase` a subclass of `Operator`.
|
||||
|
||||
```python
|
||||
class AgentBase(Operator):
|
||||
# ... [code omitted for brevity]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
sys_prompt: Optional[str] = None,
|
||||
model_config_name: str = None,
|
||||
use_memory: bool = True,
|
||||
memory_config: Optional[dict] = None,
|
||||
) -> None:
|
||||
|
||||
# ... [code omitted for brevity]
|
||||
def observe(self, x: Union[Msg, Sequence[Msg]]) -> None:
|
||||
# An optional method for updating the agent's internal state based on
|
||||
# messages it has observed. This method can be used to enrich the
|
||||
# agent's understanding and memory without producing an immediate
|
||||
# response.
|
||||
if self.memory:
|
||||
self.memory.add(x)
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# The core method to be implemented by custom agents. It defines the
|
||||
# logic for processing an input message and generating a suitable
|
||||
# response.
|
||||
raise NotImplementedError(
|
||||
f"Agent [{type(self).__name__}] is missing the required "
|
||||
f'"reply" function.',
|
||||
)
|
||||
|
||||
# ... [code omitted for brevity]
|
||||
```
|
||||
|
||||
## Exploring the AgentPool
|
||||
|
||||
The *AgentPool* within AgentScope is a curated ensemble of ready-to-use, specialized agents. Each of these agents is tailored for a distinct role and comes equipped with default behaviors that address specific tasks. The *AgentPool* is designed to expedite the development process by providing various templates of `Agent`.
|
||||
|
||||
Below is a table summarizing the functionality of some of the key agents available in the Agent Pool:
|
||||
|
||||
| Agent Type | Description | Typical Use Cases |
|
||||
| ------------------ | ----------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------- |
|
||||
| `AgentBase` | Serves as the superclass for all agents, providing essential attributes and methods. | The foundation for building any custom agent. |
|
||||
| `DialogAgent` | Manages dialogues by understanding context and generating coherent responses. | Customer service bots, virtual assistants. |
|
||||
| `DictDialogAgent` | Manages dialogues by understanding context and generating coherent responses, and the responses are in json format. | Customer service bots, virtual assistants. |
|
||||
| `UserAgent` | Interacts with the user to collect input, generating messages that may include URLs or additional specifics based on required keys. | Collecting user input for agents |
|
||||
| `TextToImageAgent` | An agent that convert user input text to image. | Converting text to image |
|
||||
| `ReActAgent` | An agent class that implements the ReAct algorithm. | Solving complex tasks |
|
||||
| *More to Come* | AgentScope is continuously expanding its pool with more specialized agents for diverse applications. | |
|
||||
|
||||
## Customizing Agents from the AgentPool
|
||||
|
||||
Customizing an agent from AgentPool enables you to tailor its functionality to meet the unique demands of your multi-agent application. You have the flexibility to modify existing agents with minimal effort by **adjusting configurations** and prompts or, for more extensive customization, you can engage in secondary development.
|
||||
|
||||
Below, we provide usages of how to configure various agents from the AgentPool:
|
||||
|
||||
### `DialogAgent`
|
||||
|
||||
* **Reply Method**: The `reply` method is where the main logic for processing input *message* and generating responses.
|
||||
|
||||
```python
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# Additional processing steps can occur here
|
||||
|
||||
# Record the input if needed
|
||||
if self.memory:
|
||||
self.memory.add(x)
|
||||
|
||||
# Generate a prompt for the language model using the system prompt and memory
|
||||
prompt = self.model.format(
|
||||
Msg("system", self.sys_prompt, role="system"),
|
||||
self.memory
|
||||
and self.memory.get_memory()
|
||||
or x, # type: ignore[arg-type]
|
||||
)
|
||||
|
||||
# Invoke the language model with the prepared prompt
|
||||
response = self.model(prompt).text
|
||||
|
||||
#Format the response and create a message object
|
||||
msg = Msg(self.name, response, role="assistant")
|
||||
|
||||
# Print/speak the message in this agent's voice
|
||||
self.speak(msg)
|
||||
|
||||
# Record the message to memory and return it
|
||||
if self.memory:
|
||||
self.memory.add(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
* **Usages:** To tailor a `DialogAgent` for a customer service bot:
|
||||
|
||||
```python
|
||||
from agentscope.agents import DialogAgent
|
||||
|
||||
# Configuration for the DialogAgent
|
||||
dialog_agent_config = {
|
||||
"name": "ServiceBot",
|
||||
"model_config_name": "gpt-3.5", # Specify the model used for dialogue generation
|
||||
"sys_prompt": "Act as AI assistant to interact with the others. Try to "
|
||||
"reponse on one line.\n", # Custom prompt for the agent
|
||||
# Other configurations specific to the DialogAgent
|
||||
}
|
||||
|
||||
# Create and configure the DialogAgent
|
||||
service_bot = DialogAgent(**dialog_agent_config)
|
||||
```
|
||||
|
||||
### `UserAgent`
|
||||
|
||||
* **Reply Method**: This method processes user input by prompting for content and if needed, additional keys and a URL. The gathered data is stored in a *message* object in the agent's memory for logging or later use and returns the message as a response.
|
||||
|
||||
```python
|
||||
def reply(
|
||||
self,
|
||||
x: Optional[Union[Msg, Sequence[Msg]]] = None,
|
||||
required_keys: Optional[Union[list[str], str]] = None,
|
||||
) -> Msg:
|
||||
# Check if there is initial data to be added to memory
|
||||
if self.memory:
|
||||
self.memory.add(x)
|
||||
|
||||
content = input(f"{self.name}: ") # Prompt the user for input
|
||||
kwargs = {}
|
||||
|
||||
# Prompt for additional information based on the required keys
|
||||
if required_keys is not None:
|
||||
if isinstance(required_keys, str):
|
||||
required_keys = [required_keys]
|
||||
for key in required_keys:
|
||||
kwargs[key] = input(f"{key}: ")
|
||||
|
||||
# Optionally prompt for a URL if required
|
||||
url = None
|
||||
if self.require_url:
|
||||
url = input("URL: ")
|
||||
|
||||
# Create a message object with the collected input and additional details
|
||||
msg = Msg(self.name, content=content, url=url, **kwargs)
|
||||
|
||||
# Add the message object to memory
|
||||
if self.memory:
|
||||
self.memory.add(msg)
|
||||
return msg
|
||||
```
|
||||
|
||||
* **Usages:** To configure a `UserAgent` for collecting user input and URLs (of file, image, video, audio , or website):
|
||||
|
||||
```python
|
||||
from agentscope.agents import UserAgent
|
||||
|
||||
# Configuration for UserAgent
|
||||
user_agent_config = {
|
||||
"name": "User",
|
||||
"require_url": True, # If true, the agent will require a URL
|
||||
}
|
||||
|
||||
# Create and configure the UserAgent
|
||||
user_proxy_agent = UserAgent(**user_agent_config)
|
||||
```
|
||||
|
||||
[[Return to the top]](#201-agent-en)
|
||||
301
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/202-pipeline.md
Normal file
301
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/202-pipeline.md
Normal file
@@ -0,0 +1,301 @@
|
||||
(202-pipeline-en)=
|
||||
|
||||
# Pipeline and MsgHub
|
||||
|
||||
**Pipeline & MsgHub** (message hub) are one or a sequence of steps describing how the structured `Msg` passes between multi-agents, which streamlines the process of collaboration across agents.
|
||||
|
||||
`Pipeline` allows users to program communication among agents easily, and `MsgHub` enables message sharing among agents like a group chat.
|
||||
|
||||
## Pipelines
|
||||
|
||||
`Pipeline` in AgentScope serves as conduits through which messages pass among agents. In AgentScope, an `Agent` is a subclass of an `Operator` that performs some operation on input data. Pipelines extend this concept by encapsulating multiple agents, and also act as an `Operator`.
|
||||
|
||||
Here is the base class for all pipeline types:
|
||||
|
||||
```python
|
||||
class PipelineBase(Operator):
|
||||
"""Base interface of all pipelines."""
|
||||
# ... [code omitted for brevity]
|
||||
@abstractmethod
|
||||
def __call__(self, x: Optional[dict] = None) -> dict:
|
||||
"""Define the actions taken by this pipeline.
|
||||
|
||||
Args:
|
||||
x (Optional[`dict`], optional):
|
||||
Dialog history and some environmental information
|
||||
|
||||
Returns:
|
||||
`dict`: The pipeline's response to the input.
|
||||
"""
|
||||
```
|
||||
|
||||
### Category
|
||||
|
||||
AgentScope provides two main types of pipelines based on their implementation strategy:
|
||||
|
||||
* **Operator-Type Pipelines**
|
||||
|
||||
* These pipelines are object-oriented and inherit from the `PipelineBase`. They are operators themselves and can be combined with other operators to create complex interaction patterns.
|
||||
|
||||
```python
|
||||
# Instantiate and invoke
|
||||
pipeline = ClsPipeline(agent1, agent2, agent3)
|
||||
x = pipeline(x)
|
||||
```
|
||||
|
||||
* **Functional Pipelines**
|
||||
|
||||
* Functional pipelines provide similar control flow mechanisms as the class-based pipelines but are implemented as standalone functions. These are useful for scenarios where a class-based setup may not be necessary or preferred.
|
||||
|
||||
```python
|
||||
# Just invoke
|
||||
x = funcpipeline(agent1, agent2, agent3, x)
|
||||
```
|
||||
|
||||
Pipelines are categorized based on their functionality, much like programming language constructs. The table below outlines the different pipelines available in AgentScope:
|
||||
|
||||
| Operator-Type Pipeline | Functional Pipeline | Description |
|
||||
| -------------------- | -------------------- | ------------------------------------------------------------ |
|
||||
| `SequentialPipeline` | `sequentialpipeline` | Executes a sequence of operators in order, passing the output of one as the input to the next. |
|
||||
| `IfElsePipeline` | `ifelsepipeline` | Implements conditional logic, executing one operator if a condition is true and another if it is false. |
|
||||
| `SwitchPipeline` | `switchpipeline` | Facilitates multi-branch selection, executing an operator from a mapped set based on the evaluation of a condition. |
|
||||
| `ForLoopPipeline` | `forlooppipeline` | Repeatedly executes an operator for a set number of iterations or until a specified break condition is met. |
|
||||
| `WhileLoopPipeline` | `whilelooppipeline` | Continuously executes an operator as long as a given condition remains true. |
|
||||
| - | `placeholder` | Acts as a placeholder in branches that do not require any operations in flow control like if-else/switch |
|
||||
|
||||
### Usage
|
||||
|
||||
This section illustrates how pipelines can simplify the implementation of logic in multi-agent applications by comparing the usage of pipelines versus approaches without pipelines.
|
||||
|
||||
**Note:** Please note that in the examples provided below, we use the term `agent` to represent any instance that can act as an `Operator`. This is for ease of understanding and to illustrate how pipelines orchestrate interactions between different operations. You can replace `agent` with any `Operator`, thus allowing for a mix of `agent` and `pipeline` in practice.
|
||||
|
||||
#### `SequentialPipeline`
|
||||
|
||||
* Without pipeline:
|
||||
|
||||
```python
|
||||
x = agent1(x)
|
||||
x = agent2(x)
|
||||
x = agent3(x)
|
||||
```
|
||||
|
||||
* Using pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SequentialPipeline
|
||||
|
||||
pipe = SequentialPipeline([agent1, agent2, agent3])
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* Using functional pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import sequentialpipeline
|
||||
|
||||
x = sequentialpipeline([agent1, agent2, agent3], x)
|
||||
```
|
||||
|
||||
#### `IfElsePipeline`
|
||||
|
||||
* Without pipeline:
|
||||
|
||||
```python
|
||||
if condition(x):
|
||||
x = agent1(x)
|
||||
else:
|
||||
x = agent2(x)
|
||||
```
|
||||
|
||||
* Using pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import IfElsePipeline
|
||||
|
||||
pipe = IfElsePipeline(condition, agent1, agent2)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* Using functional pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import ifelsepipeline
|
||||
|
||||
x = ifelsepipeline(condition, agent1, agent2, x)
|
||||
```
|
||||
|
||||
#### `SwitchPipeline`
|
||||
|
||||
* Without pipeline:
|
||||
|
||||
```python
|
||||
switch_result = condition(x)
|
||||
if switch_result == case1:
|
||||
x = agent1(x)
|
||||
elif switch_result == case2:
|
||||
x = agent2(x)
|
||||
else:
|
||||
x = default_agent(x)
|
||||
```
|
||||
|
||||
* Using pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SwitchPipeline
|
||||
|
||||
case_operators = {case1: agent1, case2: agent2}
|
||||
pipe = SwitchPipeline(condition, case_operators, default_agent)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* Using functional pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import switchpipeline
|
||||
|
||||
case_operators = {case1: agent1, case2: agent2}
|
||||
x = switchpipeline(condition, case_operators, default_agent, x)
|
||||
```
|
||||
|
||||
#### `ForLoopPipeline`
|
||||
|
||||
* Without pipeline:
|
||||
|
||||
```python
|
||||
for i in range(max_iterations):
|
||||
x = agent(x)
|
||||
if break_condition(x):
|
||||
break
|
||||
```
|
||||
|
||||
* Using pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import ForLoopPipeline
|
||||
|
||||
pipe = ForLoopPipeline(agent, max_iterations, break_condition)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* Using functional pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import forlooppipeline
|
||||
|
||||
x = forlooppipeline(agent, max_iterations, break_condition, x)
|
||||
```
|
||||
|
||||
#### `WhileLoopPipeline`
|
||||
|
||||
* Without pipeline:
|
||||
|
||||
```python
|
||||
while condition(x):
|
||||
x = agent(x)
|
||||
```
|
||||
|
||||
* Using pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import WhileLoopPipeline
|
||||
|
||||
pipe = WhileLoopPipeline(agent, condition)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* Using functional pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import whilelooppipeline
|
||||
|
||||
x = whilelooppipeline(agent, condition, x)
|
||||
```
|
||||
|
||||
### Pipeline Combination
|
||||
|
||||
It's worth noting that AgentScope supports the combination of pipelines to create complex interactions. For example, we can create a pipeline that executes a sequence of agents in order, and then executes another pipeline that executes a sequence of agents in condition.
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SequentialPipeline, IfElsePipeline
|
||||
# Create a pipeline that executes agents in order
|
||||
pipe1 = SequentialPipeline([agent1, agent2, agent3])
|
||||
# Create a pipeline that executes agents in ifElsePipeline
|
||||
pipe2 = IfElsePipeline(condition, agent4, agent5)
|
||||
# Create a pipeline that executes pipe1 and pipe2 in order
|
||||
pipe3 = SequentialPipeline([pipe1, pipe2])
|
||||
# Invoke the pipeline
|
||||
x = pipe3(x)
|
||||
```
|
||||
|
||||
## MsgHub
|
||||
|
||||
`MsgHub` is designed to manage dialogue among a group of agents, allowing for the sharing of messages. Through `MsgHub`, agents can broadcast messages to all other agents in the group with `broadcast`.
|
||||
|
||||
Here is the core class for a `MsgHub`:
|
||||
|
||||
```python
|
||||
class MsgHubManager:
|
||||
"""MsgHub manager class for sharing dialog among a group of agents."""
|
||||
# ... [code omitted for brevity]
|
||||
|
||||
def broadcast(self, msg: Union[dict, list[dict]]) -> None:
|
||||
"""Broadcast the message to all participants."""
|
||||
for agent in self.participants:
|
||||
agent.observe(msg)
|
||||
|
||||
def add(self, new_participant: Union[Sequence[AgentBase], AgentBase]) -> None:
|
||||
"""Add new participant into this hub"""
|
||||
# ... [code omitted for brevity]
|
||||
|
||||
def delete(self, participant: Union[Sequence[AgentBase], AgentBase]) -> None:
|
||||
"""Delete agents from participant."""
|
||||
# ... [code omitted for brevity]
|
||||
```
|
||||
|
||||
### Usage
|
||||
|
||||
#### Creating a MsgHub
|
||||
|
||||
To create a `MsgHub`, instantiate a `MsgHubManager` by calling the `msghub` helper function with a list of participating agents. Additionally, you can supply an optional initial announcement that, if provided, will be broadcast to all participants upon initialization.
|
||||
|
||||
```python
|
||||
from agentscope.msg_hub import msghub
|
||||
|
||||
# Initialize MsgHub with participating agents
|
||||
hub_manager = msghub(
|
||||
participants=[agent1, agent2, agent3], announcement=initial_announcement
|
||||
)
|
||||
```
|
||||
|
||||
#### Broadcast message in MsgHub
|
||||
|
||||
The `MsgHubManager` can be used with a context manager to handle the setup and teardown of the message hub environment:
|
||||
|
||||
```python
|
||||
with msghub(
|
||||
participants=[agent1, agent2, agent3], announcement=initial_announcement
|
||||
) as hub:
|
||||
# Agents can now broadcast and receive messages within this block
|
||||
agent1()
|
||||
agent2()
|
||||
|
||||
# Or manually broadcast a message
|
||||
hub.broadcast(some_message)
|
||||
|
||||
```
|
||||
|
||||
Upon exiting the context block, the `MsgHubManager` ensures that each agent's audience is cleared, preventing any unintended message sharing outside of the hub context.
|
||||
|
||||
#### Adding and Deleting Participants
|
||||
|
||||
You can dynamically add or remove agents from the `MsgHub`:
|
||||
|
||||
```python
|
||||
# Add a new participant
|
||||
hub.add(new_agent)
|
||||
|
||||
# Remove an existing participant
|
||||
hub.delete(existing_agent)
|
||||
```
|
||||
|
||||
[[Return to the top]](#202-pipeline-en)
|
||||
605
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/203-model.md
Normal file
605
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/203-model.md
Normal file
@@ -0,0 +1,605 @@
|
||||
(203-model-en)=
|
||||
|
||||
# Model
|
||||
|
||||
In AgentScope, the model deployment and invocation are decoupled by `ModelWrapper`.
|
||||
Developers can specify their own model by providing model configurations,
|
||||
and AgentScope also provides scripts to support developers to customize
|
||||
model services.
|
||||
|
||||
## Supported Models
|
||||
|
||||
Currently, AgentScope supports the following model service APIs:
|
||||
|
||||
- OpenAI API, including chat, image generation (DALL-E), and Embedding.
|
||||
- DashScope API, including chat, image sythesis and text embedding.
|
||||
- Gemini API, including chat and embedding.
|
||||
- ZhipuAI API, including chat and embedding.
|
||||
- Ollama API, including chat, embedding and generation.
|
||||
- LiteLLM API, including chat, with various model APIs.
|
||||
- Post Request API, model inference services based on Post
|
||||
requests, including Huggingface/ModelScope Inference API and various
|
||||
post request based model APIs.
|
||||
|
||||
## Configuration
|
||||
|
||||
In AgentScope, users specify the model configuration through the
|
||||
`model_configs` parameter in the `agentscope.init` interface.
|
||||
`model_configs` can be a **dictionary**, **a list of dictionaries**, or a
|
||||
**path** to model configuration file.
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.init(model_configs=MODEL_CONFIG_OR_PATH)
|
||||
```
|
||||
|
||||
### Configuration Format
|
||||
|
||||
In AgentScope, the model configuration is a dictionary used to specify the type of model and set the call parameters.
|
||||
We divide the fields in the model configuration into two categories: _basic parameters_ and _detailed parameters_.
|
||||
|
||||
Among them, the basic parameters include `config_name` and `model_type`, which are used to distinguish different model configurations and specific `ModelWrapper` types.
|
||||
The detailed parameters will be fed into the corresponding model class's constructor to initialize the model instance.
|
||||
|
||||
```python
|
||||
{
|
||||
# Basic parameters
|
||||
"config_name": "gpt-4-temperature-0.0", # Model configuration name
|
||||
"model_type": "openai_chat", # Correspond to `ModelWrapper` type
|
||||
|
||||
# Detailed parameters
|
||||
# ...
|
||||
}
|
||||
```
|
||||
|
||||
#### Basic Parameters
|
||||
|
||||
In basic parameters, `config_name` is the identifier of the model configuration,
|
||||
which we will use to specify the model service when initializing an agent.
|
||||
|
||||
`model_type` corresponds to the type of `ModelWrapper` and is used to specify the type of model service.
|
||||
It corresponds to the `model_type` field in the `ModelWrapper` class in the source code.
|
||||
|
||||
```python
|
||||
class OpenAIChatWrapper(OpenAIWrapperBase):
|
||||
"""The model wrapper for OpenAI's chat API."""
|
||||
|
||||
model_type: str = "openai_chat"
|
||||
# ...
|
||||
```
|
||||
|
||||
In the current AgentScope, the supported `model_type` types, the corresponding
|
||||
`ModelWrapper` classes, and the supported APIs are as follows:
|
||||
|
||||
| API | Task | Model Wrapper | `model_type` | Some Supported Models |
|
||||
|------------------------|-----------------|---------------------------------------------------------------------------------------------------------------------------------|-------------------------------|--------------------------------------------------|
|
||||
| OpenAI API | Chat | [`OpenAIChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py) | `"openai_chat"` | gpt-4, gpt-3.5-turbo, ... |
|
||||
| | Embedding | [`OpenAIEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py) | `"openai_embedding"` | text-embedding-ada-002, ... |
|
||||
| | DALL·E | [`OpenAIDALLEWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py) | `"openai_dall_e"` | dall-e-2, dall-e-3 |
|
||||
| DashScope API | Chat | [`DashScopeChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_chat"` | qwen-plus, qwen-max, ... |
|
||||
| | Image Synthesis | [`DashScopeImageSynthesisWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_image_synthesis"` | wanx-v1 |
|
||||
| | Text Embedding | [`DashScopeTextEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_text_embedding"` | text-embedding-v1, text-embedding-v2, ... |
|
||||
| | Multimodal | [`DashScopeMultiModalWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_multimodal"` | qwen-vl-plus, qwen-vl-max, qwen-audio-turbo, ... |
|
||||
| Gemini API | Chat | [`GeminiChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py) | `"gemini_chat"` | gemini-pro, ... |
|
||||
| | Embedding | [`GeminiEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py) | `"gemini_embedding"` | models/embedding-001, ... |
|
||||
| ZhipuAI API | Chat | [`ZhipuAIChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py) | `"zhipuai_chat"` | glm4, ... |
|
||||
| | Embedding | [`ZhipuAIEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py) | `"zhipuai_embedding"` | embedding-2, ... |
|
||||
| ollama | Chat | [`OllamaChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py) | `"ollama_chat"` | llama2, ... |
|
||||
| | Embedding | [`OllamaEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py) | `"ollama_embedding"` | llama2, ... |
|
||||
| | Generation | [`OllamaGenerationWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py) | `"ollama_generate"` | llama2, ... |
|
||||
| LiteLLM API | Chat | [`LiteLLMChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/litellm_model.py) | `"litellm_chat"` | - |
|
||||
| Post Request based API | - | [`PostAPIModelWrapperBase`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `"post_api"` | - |
|
||||
| | Chat | [`PostAPIChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `"post_api_chat"` | meta-llama/Meta-Llama-3-8B-Instruct, ... |
|
||||
| | Image Synthesis | [`PostAPIDALLEWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `post_api_dall_e` | - | |
|
||||
| | Embedding | [`PostAPIEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `post_api_embedding` | - |
|
||||
|
||||
#### Detailed Parameters
|
||||
|
||||
In AgentScope, the detailed parameters are different according to the different `ModelWrapper` classes.
|
||||
To specify the detailed parameters, you need to refer to the specific `ModelWrapper` class and its constructor.
|
||||
Here we provide example configurations for different model wrappers.
|
||||
|
||||
##### OpenAI API
|
||||
|
||||
<details>
|
||||
<summary>OpenAI Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py">agents.models.OpenAIChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "{your_config_name}",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "gpt-4",
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}", # OpenAI API Key, if not provided, it will be read from the environment variable
|
||||
"organization": "{your_organization}", # Organization name, if not provided, it will be read from the environment variable
|
||||
"client_args": { # Parameters for initializing the OpenAI API Client
|
||||
# e.g. "max_retries": 3,
|
||||
},
|
||||
"generate_args": { # Parameters passed to the model when calling
|
||||
# e.g. "temperature": 0.0
|
||||
},
|
||||
"budget": 100 # API budget
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>OpenAI DALL·E API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py">agentscope.models.OpenAIDALLEWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "{your_config_name}",
|
||||
"model_type": "openai_dall_e",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # OpenAI model name, e.g. dall-e-2, dall-e-3
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}", # OpenAI API Key, if not provided, it will be read from the environment variable
|
||||
"organization": "{your_organization}", # Organization name, if not provided, it will be read from the environment variable
|
||||
"client_args": { # Parameters for initializing the OpenAI API Client
|
||||
# e.g. "max_retries": 3,
|
||||
},
|
||||
"generate_args": { # Parameters passed to the model when calling
|
||||
# e.g. "n": 1, "size": "512x512"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>OpenAI Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py">agentscope.models.OpenAIEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "{your_config_name}",
|
||||
"model_type": "openai_embedding",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # OpenAI model name, e.g. text-embedding-ada-002, text-embedding-3-small
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}", # OpenAI API Key, if not provided, it will be read from the environment variable
|
||||
"organization": "{your_organization}", # Organization name, if not provided, it will be read from the environment variable
|
||||
"client_args": { # Parameters for initializing the OpenAI API Client
|
||||
# e.g. "max_retries": 3,
|
||||
},
|
||||
"generate_args": { # Parameters passed to the model when calling
|
||||
# e.g. "encoding_format": "float"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
#### DashScope API
|
||||
|
||||
<details>
|
||||
<summary>DashScope Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_chat_config",
|
||||
"model_type": "dashscope_chat",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in DashScope API, e.g. qwen-max
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}", # DashScope API Key, if not provided, it will be read from the environment variable
|
||||
"generate_args": {
|
||||
# e.g. "temperature": 0.5
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>DashScope Image Synthesis API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeImageSynthesisWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_image_synthesis_config",
|
||||
"model_type": "dashscope_image_synthesis",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in DashScope Image Synthesis API, e.g. wanx-v1
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}",
|
||||
"generate_args": {
|
||||
"negative_prompt": "xxx",
|
||||
"n": 1,
|
||||
# ...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>DashScope Text Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeTextEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_text_embedding_config",
|
||||
"model_type": "dashscope_text_embedding",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in DashScope Text Embedding API, e.g. text-embedding-v1
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}",
|
||||
"generate_args": {
|
||||
# ...
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>DashScope Multimodal Conversation API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeMultiModalWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_multimodal_config",
|
||||
"model_type": "dashscope_multimodal",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in DashScope Multimodal Conversation API, e.g. qwen-vl-plus
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}",
|
||||
"generate_args": {
|
||||
# ...
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
#### Gemini API
|
||||
|
||||
<details>
|
||||
<summary>Gemini Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py">agentscope.models.GeminiChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_gemini_chat_config",
|
||||
"model_type": "gemini_chat",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in Gemini API, e.g. gemini-pro
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}", # If not provided, the API key will be read from the environment variable GEMINI_API_KEY
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Gemini Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py">agentscope.models.GeminiEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_gemini_embedding_config",
|
||||
"model_type": "gemini_embedding",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in Gemini API, e.g. models/embedding-001
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}", # If not provided, the API key will be read from the environment variable GEMINI_API_KEY
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
#### ZhipuAI API
|
||||
|
||||
<details>
|
||||
<summary>ZhipuAI Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py">agentscope.models.ZhipuAIChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_zhipuai_chat_config",
|
||||
"model_type": "zhipuai_chat",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in ZhipuAI API, e.g. glm-4
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}"
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>ZhipuAI Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py">agentscope.models.ZhipuAIEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_zhipuai_embedding_config",
|
||||
"model_type": "zhipuai_embedding",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in ZhipuAI API, e.g. embedding-2
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}",
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
#### Ollama API
|
||||
|
||||
<details>
|
||||
<summary>Ollama Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py">agentscope.models.OllamaChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_ollama_chat_config",
|
||||
"model_type": "ollama_chat",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name used in ollama API, e.g. llama2
|
||||
|
||||
# Optional parameters
|
||||
"options": { # Parameters passed to the model when calling
|
||||
# e.g. "temperature": 0., "seed": 123,
|
||||
},
|
||||
"keep_alive": "5m", # Controls how long the model will stay loaded into memory
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Ollama Generation API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py">agentscope.models.OllamaGenerationWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_ollama_generate_config",
|
||||
"model_type": "ollama_generate",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name used in ollama API, e.g. llama2
|
||||
|
||||
# Optional parameters
|
||||
"options": { # Parameters passed to the model when calling
|
||||
# "temperature": 0., "seed": 123,
|
||||
},
|
||||
"keep_alive": "5m", # Controls how long the model will stay loaded into memory
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Ollama Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py">agentscope.models.OllamaEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_ollama_embedding_config",
|
||||
"model_type": "ollama_embedding",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name used in ollama API, e.g. llama2
|
||||
|
||||
# Optional parameters
|
||||
"options": { # Parameters passed to the model when calling
|
||||
# "temperature": 0., "seed": 123,
|
||||
},
|
||||
"keep_alive": "5m", # Controls how long the model will stay loaded into memory
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
#### LiteLLM Chat API
|
||||
|
||||
<details>
|
||||
<summary>LiteLLM Chat API (<code><a href="https://github.
|
||||
com/modelscope/agentscope/blob/main/src/agentscope/models/litellm_model.py">agentscope.models.LiteLLMChatModelWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "lite_llm_openai_chat_gpt-3.5-turbo",
|
||||
"model_type": "litellm_chat",
|
||||
"model_name": "gpt-3.5-turbo" # You should note that for different models, you should set the corresponding environment variables, such as OPENAI_API_KEY, etc. You may refer to https://docs.litellm.ai/docs/ for this.
|
||||
},
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
#### Post Request API
|
||||
|
||||
<details>
|
||||
<summary>Post Request Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapichatwrapper_config",
|
||||
"model_type": "post_api_chat",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ The Post Request Chat model wrapper (`PostAPIChatWrapper`) has the following properties:
|
||||
> 1) The `.format()` function makes sure the input messages become a list of dicts.
|
||||
> 2) The `._parse_response()` function assumes the generated text will be in `response["data"]["response"]["choices"][0]["message"]["content"]`
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
|
||||
<details>
|
||||
<summary>Post Request Image Synthesis API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIDALLEWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api_dall_e",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ The Post Request Image Synthesis model wrapper (`PostAPIDALLEWrapper`) has the following properties:
|
||||
> 1) The `._parse_response()` function assumes the generated image will be presented as urls in `response["data"]["response"]["data"][i]["url"]`
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<details>
|
||||
<summary>Post Request Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api_embedding",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ The Post Request Embedding model wrapper (`PostAPIEmbeddingWrapper`) has the following properties:
|
||||
> 1) The `._parse_response()` function assumes the generated embeddings will be in `response["data"]["response"]["data"][i]["embedding"]`
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<details>
|
||||
<summary>Post Request API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIModelWrapperBase</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ Post Request model wrapper (`PostAPIModelWrapperBase`) returns raw HTTP responses from the API in ModelResponse, and the `.format()` is not implemented. It is recommended to use `Post Request Chat API` when running examples with chats.
|
||||
> `PostAPIModelWrapperBase` can be used when
|
||||
> 1) only the raw HTTP response is wanted and `.format()` is not called;
|
||||
> 2) Or, the developers want to overwrite the `.format()` and/or `._parse_response()` functions.
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<br/>
|
||||
|
||||
## Build Model Service from Scratch
|
||||
|
||||
For developers who need to build their own model services, AgentScope
|
||||
provides some scripts to help developers quickly build model services.
|
||||
You can find these scripts and instructions in the [scripts](https://github.com/modelscope/agentscope/tree/main/scripts)
|
||||
directory.
|
||||
|
||||
Specifically, AgentScope provides the following model service scripts:
|
||||
|
||||
- [CPU inference engine **ollama**](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#ollama)
|
||||
- [Model service based on **Flask + Transformers**](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#with-transformers-library)
|
||||
- [Model service based on **Flask + ModelScope**](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#with-modelscope-library)
|
||||
- [**FastChat** inference engine](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#fastchat)
|
||||
- [**vllm** inference engine](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#vllm)
|
||||
|
||||
About how to quickly start these model services, users can refer to the [README.md](https://github.com/modelscope/agentscope/blob/main/scripts/README.md) file under the [scripts](https://github.com/modelscope/agentscope/blob/main/scripts/) directory.
|
||||
|
||||
## Creat Your Own Model Wrapper
|
||||
|
||||
AgentScope allows developers to customize their own model wrappers.
|
||||
The new model wrapper class should
|
||||
|
||||
- inherit from `ModelWrapperBase` class,
|
||||
- provide a `model_type` field to identify this model wrapper in the model configuration, and
|
||||
- implement its `__init__` and `__call__` functions.
|
||||
|
||||
The following is an example for creating a new model wrapper class.
|
||||
|
||||
```python
|
||||
from agentscope.models import ModelWrapperBase
|
||||
|
||||
class MyModelWrapper(ModelWrapperBase):
|
||||
|
||||
model_type: str = "my_model"
|
||||
|
||||
def __init__(self, config_name, my_arg1, my_arg2, **kwargs):
|
||||
# Initialize the model instance
|
||||
super().__init__(config_name=config_name)
|
||||
# ...
|
||||
|
||||
def __call__(self, input, **kwargs) -> str:
|
||||
# Call the model instance
|
||||
# ...
|
||||
```
|
||||
|
||||
After creating the new model wrapper class, the model wrapper will be registered into AgentScope automatically.
|
||||
You can use it in the model configuration directly.
|
||||
|
||||
```python
|
||||
my_model_config = {
|
||||
# Basic parameters
|
||||
"config_name": "my_model_config",
|
||||
"model_type": "my_model",
|
||||
|
||||
# Detailed parameters
|
||||
"my_arg1": "xxx",
|
||||
"my_arg2": "yyy",
|
||||
# ...
|
||||
}
|
||||
```
|
||||
|
||||
[[Return to Top]](#203-model-en)
|
||||
506
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/203-parser.md
Normal file
506
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/203-parser.md
Normal file
@@ -0,0 +1,506 @@
|
||||
(203-parser-en)=
|
||||
|
||||
# Response Parser
|
||||
|
||||
## Table of Contents
|
||||
|
||||
- [Background](#background)
|
||||
- [Parser Module](#parser-module)
|
||||
- [Overview](#overview)
|
||||
- [String Type](#string-type)
|
||||
- [MarkdownCodeBlockParser](#markdowncodeblockparser)
|
||||
- [Initialization](#initialization)
|
||||
- [Format Instruction Template](#format-instruction-template)
|
||||
- [Parse Function](#parse-function)
|
||||
- [Dictionary Type](#dictionary-type)
|
||||
- [MarkdownJsonDictParser](#markdownjsondictparser)
|
||||
- [Initialization & Format Instruction Template](#initialization--format-instruction-template)
|
||||
- [Validation](#validation)
|
||||
- [MultiTaggedContentParser](#multitaggedcontentparser)
|
||||
- [Initialization & Format Instruction Template](#initialization--format-instruction-template-1)
|
||||
- [Parse Function](#parse-function-1)
|
||||
- [JSON / Python Object Type](#json--python-object-type)
|
||||
- [MarkdownJsonObjectParser](#markdownjsonobjectparser)
|
||||
- [Initialization & Format Instruction Template](#initialization--format-instruction-template-2)
|
||||
- [Parse Function](#parse-function-2)
|
||||
- [Typical Use Cases](#typical-use-cases)
|
||||
- [WereWolf Game](#werewolf-game)
|
||||
- [ReAct Agent and Tool Usage](#react-agent-and-tool-usage)
|
||||
- [Customized Parser](#customized-parser)
|
||||
|
||||
## Background
|
||||
|
||||
In the process of building LLM-empowered application, parsing the LLM generated string into a specific format and extracting the required information is a very important step.
|
||||
However, due to the following reasons, this process is also a very complex process:
|
||||
|
||||
1. **Diversity**: The target format of parsing is diverse, and the information to be extracted may be a specific text, a JSON object, or a complex data structure.
|
||||
2. **Complexity**: The result parsing is not only to convert the text generated by LLM into the target format, but also involves a series of issues such as prompt engineering (reminding LLM what format of output should be generated), error handling, etc.
|
||||
3. **Flexibility**: Even in the same application, different stages may also require the agent to generate output in different formats.
|
||||
|
||||
For the convenience of developers, AgentScope provides a parser module to help developers parse LLM response into a specific format. By using the parser module, developers can easily parse the response into the target format by simple configuration, and switch the target format flexibly.
|
||||
|
||||
In AgentScope, the parser module features
|
||||
1. **Flexibility**: Developers can flexibly set the required format, flexibly switch the parser without modifying the code of agent class. That is, the specific "target format" and the agent's `reply` function are decoupled.
|
||||
2. **Freedom**: The format instruction, result parsing and prompt engineering are all explicitly finished in the `reply` function. Developers and users can freely choose to use the parser or parse LLM response by their own code.
|
||||
3. **Transparency**: When using the parser, the process and results of prompt construction are completely visible and transparent to developers in the `reply` function, and developers can precisely debug their applications.
|
||||
|
||||
## Parser Module
|
||||
|
||||
### Overview
|
||||
|
||||
The main functions of the parser module include:
|
||||
|
||||
1. Provide "format instruction", that is, remind LLM where to generate what output, for example
|
||||
|
||||
````
|
||||
You should generate python code in a fenced code block as follows
|
||||
```python
|
||||
{your_python_code}
|
||||
```
|
||||
````
|
||||
|
||||
2. Provide a parse function, which directly parses the text generated by LLM into the target data format,
|
||||
|
||||
3. Post-processing for dictionary format. After parsing the text into a dictionary, different fields may have different uses.
|
||||
|
||||
AgentScope provides multiple built-in parsers, and developers can choose according to their needs.
|
||||
|
||||
| Target Format | Parser Class | Description |
|
||||
| --- | --- |------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| String | `MarkdownCodeBlockParser` | Requires LLM to generate specified text within a Markdown code block marked by ```. The result is a string. |
|
||||
| Dictionary | `MarkdownJsonDictParser` | Requires LLM to produce a specified dictionary within the code block marked by \```json and \```. The result is a Python dictionary. |
|
||||
| | `MultiTaggedContentParser` | Requires LLM to generate specified content within multiple tags. Contents from different tags will be parsed into a single Python dictionary with different key-value pairs. |
|
||||
| JSON / Python Object Type | `MarkdownJsonObjectParser` | Requires LLM to produce specified content within the code block marked by \```json and \```. The result will be converted into a Python object via json.loads. |
|
||||
|
||||
> **NOTE**: Compared to `MarkdownJsonDictParser`, `MultiTaggedContentParser` is more suitable for weak LLMs and when the required format is too complex.
|
||||
> For example, when LLM is required to generate Python code, if the code is returned directly within a dictionary, LLM needs to be aware of escaping characters (\t, \n, ...), and the differences between double and single quotes when calling `json.loads`
|
||||
>
|
||||
> In contrast, `MultiTaggedContentParser` guides LLM to generate each key-value pair separately in individual tags and then combines them into a dictionary, thus reducing the difficulty.
|
||||
|
||||
|
||||
>**NOTE**: The built-in strategies to construct format instruction just provide some examples. In AgentScope, developer has complete control over prompt construction. So they can choose not to use the format instruction provided by parsers, customizing their format instruction by hand or implementing new parser class are all feasible.
|
||||
|
||||
In the following sections, we will introduce the usage of these parsers based on different target formats.
|
||||
|
||||
### String Type
|
||||
|
||||
#### MarkdownCodeBlockParser
|
||||
|
||||
##### Initialization
|
||||
|
||||
- `MarkdownCodeBlockParser` requires LLM to generate specific text within a specified code block in Markdown format. Different languages can be specified with the `language_name` parameter to utilize the large model's ability to produce corresponding outputs. For example, when asking the large model to produce Python code, initialize as follows:
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownCodeBlockParser
|
||||
|
||||
parser = MarkdownCodeBlockParser(language_name="python", content_hint="your python code")
|
||||
```
|
||||
|
||||
##### Format Instruction Template
|
||||
|
||||
- `MarkdownCodeBlockParser` provides the following format instruction template. When the user calls the `format_instruction` attribute, `{language_name}` will be replaced with the string entered at initialization:
|
||||
|
||||
````
|
||||
You should generate {language_name} code in a {language_name} fenced code block as follows:
|
||||
```{language_name}
|
||||
{content_hint}
|
||||
```
|
||||
````
|
||||
|
||||
- For the above initialization with `language_name` as `"python"`, when the `format_instruction` attribute is called, the following string will be returned:
|
||||
|
||||
```python
|
||||
print(parser.format_instruction)
|
||||
```
|
||||
|
||||
````
|
||||
You should generate python code in a python fenced code block as follows
|
||||
```python
|
||||
your python code
|
||||
```
|
||||
````
|
||||
|
||||
##### Parse Function
|
||||
|
||||
- `MarkdownCodeBlockParser` provides a `parse` method to parse the text generated by LLM。Its input and output are both `ModelResponse` objects, and the parsing result will be mounted on the `parsed` attribute of the output object.
|
||||
|
||||
````python
|
||||
res = parser.parse(
|
||||
ModelResponse(
|
||||
text="""The following is generated python code
|
||||
```python
|
||||
print("Hello world!")
|
||||
```
|
||||
"""
|
||||
)
|
||||
)
|
||||
|
||||
print(res.parsed)
|
||||
````
|
||||
|
||||
```
|
||||
print("hello world!")
|
||||
```
|
||||
|
||||
### Dictionary Type
|
||||
|
||||
Different from string and general JSON/Python object, as a powerful format in LLM applications, AgentScope provides additional post-processing functions for dictionary type.
|
||||
When initializing the parser, you can set the `keys_to_content`, `keys_to_memory`, and `keys_to_metadata` parameters to achieve filtering of key-value pairs when calling the parser's `to_content`, `to_memory`, and `to_metadata` methods.
|
||||
|
||||
- `keys_to_content` specifies the key-value pairs that will be placed in the `content` field of the returned `Msg` object. The content field will be returned to other agents, participate in their prompt construction, and will also be called by the `self.speak` function for display.
|
||||
- `keys_to_memory` specifies the key-value pairs that will be stored in the memory of the agent.
|
||||
- `keys_to_metadata` specifies the key-value pairs that will be placed in the `metadata` field of the returned `Msg` object, which can be used for application control flow judgment, or mount some information that does not need to be returned to other agents.
|
||||
|
||||
The three parameters receive bool values, string and a list of strings. The meaning of their values is as follows:
|
||||
- `False`: The corresponding filter function will return `None`.
|
||||
- `True`: The whole dictionary will be returned.
|
||||
- `str`: The corresponding value will be directly returned.
|
||||
- `List[str]`: A filtered dictionary will be returned according to the list of keys.
|
||||
|
||||
By default, `keys_to_content` and `keys_to_memory` are `True`, that is, the whole dictionary will be returned. `keys_to_metadata` defaults to `False`, that is, the corresponding filter function will return `None`.
|
||||
|
||||
For example, the dictionary generated by the werewolf in the daytime discussion in a werewolf game. In this example,
|
||||
- `"thought"` should not be returned to other agents, but should be stored in the agent's memory to ensure the continuity of the werewolf strategy;
|
||||
- `"speak"` should be returned to other agents and stored in the agent's memory;
|
||||
- `"finish_discussion"` is used in the application's control flow to determine whether the discussion has ended. To save tokens, this field should not be returned to other agents or stored in the agent's memory.
|
||||
|
||||
```python
|
||||
{
|
||||
"thought": "The others didn't realize I was a werewolf. I should end the discussion soon.",
|
||||
"speak": "I agree with you.",
|
||||
"finish_discussion": True
|
||||
}
|
||||
```
|
||||
|
||||
In AgentScope, we achieve post-processing by calling the `to_content`, `to_memory`, and `to_metadata` methods, as shown in the following code:
|
||||
|
||||
- The code for the application's control flow, create the corresponding parser object and load it
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownJsonDictParser
|
||||
|
||||
# ...
|
||||
|
||||
agent = DictDialogAgent(...)
|
||||
|
||||
# Take MarkdownJsonDictParser as example
|
||||
parser = MarkdownJsonDictParser(
|
||||
content_hint={
|
||||
"thought": "what you thought",
|
||||
"speak": "what you speak",
|
||||
"finish_discussion": "whether the discussion is finished"
|
||||
},
|
||||
keys_to_content="speak",
|
||||
keys_to_memory=["thought", "speak"],
|
||||
keys_to_metadata=["finish_discussion"]
|
||||
)
|
||||
|
||||
# Load parser, which is equivalent to specifying the required format
|
||||
agent.set_parser(parser)
|
||||
|
||||
# The discussion process
|
||||
while True:
|
||||
# ...
|
||||
x = agent(x)
|
||||
# Break the loop according to the finish_discussion field in metadata
|
||||
if x.metadata["finish_discussion"]:
|
||||
break
|
||||
```
|
||||
|
||||
- Filter the dictionary in the agent's `reply` function
|
||||
|
||||
```python
|
||||
# ...
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
|
||||
# ...
|
||||
res = self.model(prompt, parse_func=self.parser.parse)
|
||||
|
||||
# Story the thought and speak fields into memory
|
||||
self.memory.add(
|
||||
Msg(
|
||||
self.name,
|
||||
content=self.parser.to_memory(res.parsed),
|
||||
role="assistant",
|
||||
)
|
||||
)
|
||||
|
||||
# Store in content and metadata fields in the returned Msg object
|
||||
msg = Msg(
|
||||
self.name,
|
||||
content=self.parser.to_content(res.parsed),
|
||||
role="assistant",
|
||||
metadata=self.parser.to_metadata(res.parsed),
|
||||
)
|
||||
self.speak(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
> **Note**: `keys_to_content`, `keys_to_memory`, and `keys_to_metadata` parameters can be a string, a list of strings, or a bool value.
|
||||
> - For `True`, the `to_content`, `to_memory`, and `to_metadata` methods will directly return the whole dictionary.
|
||||
> - For `False`, the `to_content`, `to_memory`, and `to_metadata` methods will directly return `None`.
|
||||
> - For a string, the `to_content`, `to_memory`, and `to_metadata` methods will directly extract the corresponding value. For example, if `keys_to_content="speak"`, the `to_content` method will put `res.parsed["speak"]` into the `content` field of the `Msg` object, and the `content` field will be a string rather than a dictionary.
|
||||
> - For a list of string, the `to_content`, `to_memory`, and `to_metadata` methods will filter the dictionary according to the list of keys.
|
||||
> ```python
|
||||
> parser = MarkdownJsonDictParser(
|
||||
> content_hint={
|
||||
> "thought": "what you thought",
|
||||
> "speak": "what you speak",
|
||||
> },
|
||||
> keys_to_content="speak",
|
||||
> keys_to_memory=["thought", "speak"],
|
||||
> )
|
||||
>
|
||||
> example_dict = {"thought": "abc", "speak": "def"}
|
||||
> print(parser.to_content(example_dict)) # def
|
||||
> print(parser.to_memory(example_dict)) # {"thought": "abc", "speak": "def"}
|
||||
> print(parser.to_metadata(example_dict)) # None
|
||||
> ```
|
||||
> ```
|
||||
> def
|
||||
> {"thought": "abc", "speak": "def"}
|
||||
> None
|
||||
> ```
|
||||
|
||||
|
||||
Next we will introduce two parsers for dictionary type.
|
||||
|
||||
#### MarkdownJsonDictParser
|
||||
|
||||
##### Initialization & Format Instruction Template
|
||||
|
||||
- `MarkdownJsonDictParser` requires LLM to generate dictionary within a code block fenced by \```json and \``` tags.
|
||||
|
||||
- Except `keys_to_content`, `keys_to_memory` and `keys_to_metadata`, the `content_hint` parameter can be provided to give an example and explanation of the response result, that is, to remind LLM where and what kind of dictionary should be generated.
|
||||
This parameter can be a string or a dictionary. For dictionary, it will be automatically converted to a string when constructing the format instruction.
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownJsonDictParser
|
||||
|
||||
# dictionary as content_hint
|
||||
MarkdownJsonDictParser(
|
||||
content_hint={
|
||||
"thought": "what you thought",
|
||||
"speak": "what you speak",
|
||||
}
|
||||
)
|
||||
# or string as content_hint
|
||||
MarkdownJsonDictParser(
|
||||
content_hint="""{
|
||||
"thought": "what you thought",
|
||||
"speak": "what you speak",
|
||||
}"""
|
||||
)
|
||||
```
|
||||
|
||||
- The corresponding `instruction_format` attribute
|
||||
|
||||
````
|
||||
You should respond a json object in a json fenced code block as follows:
|
||||
```json
|
||||
{content_hint}
|
||||
```
|
||||
````
|
||||
|
||||
##### Validation
|
||||
|
||||
The `content_hint` parameter in `MarkdownJsonDictParser` also supports type validation based on Pydantic. When initializing, you can set `content_hint` to a Pydantic model class, and AgentScope will modify the `instruction_format` attribute based on this class. Besides, Pydantic will be used to validate the dictionary returned by LLM during parsing.
|
||||
|
||||
A simple example is as follows, where `"..."` can be filled with specific type validation rules, which can be referred to the [Pydantic](https://docs.pydantic.dev/latest/) documentation.
|
||||
|
||||
```python
|
||||
from pydantic import BaseModel, Field
|
||||
from agentscope.parsers import MarkdownJsonDictParser
|
||||
|
||||
class Schema(BaseModel):
|
||||
thought: str = Field(..., description="what you thought")
|
||||
speak: str = Field(..., description="what you speak")
|
||||
end_discussion: bool = Field(..., description="whether the discussion is finished")
|
||||
|
||||
parser = MarkdownJsonDictParser(content_hint=Schema)
|
||||
```
|
||||
|
||||
- The corresponding `instruction_format` attribute
|
||||
|
||||
````
|
||||
Respond a JSON dictionary in a markdown's fenced code block as follows:
|
||||
```json
|
||||
{a_JSON_dictionary}
|
||||
```
|
||||
The generated JSON dictionary MUST follow this schema:
|
||||
{'properties': {'speak': {'description': 'what you speak', 'title': 'Speak', 'type': 'string'}, 'thought': {'description': 'what you thought', 'title': 'Thought', 'type': 'string'}, 'end_discussion': {'description': 'whether the discussion reached an agreement or not', 'title': 'End Discussion', 'type': 'boolean'}}, 'required': ['speak', 'thought', 'end_discussion'], 'title': 'Schema', 'type': 'object'}
|
||||
````
|
||||
|
||||
- During the parsing process, Pydantic will be used for type validation, and an exception will be thrown if the validation fails. Meanwhile, Pydantic also provides some fault tolerance capabilities, such as converting the string `"true"` to Python's `True`:
|
||||
|
||||
````
|
||||
parser.parser("""
|
||||
```json
|
||||
{
|
||||
"thought": "The others didn't realize I was a werewolf. I should end the discussion soon.",
|
||||
"speak": "I agree with you.",
|
||||
"end_discussion": "true"
|
||||
}
|
||||
```
|
||||
""")
|
||||
````
|
||||
|
||||
#### MultiTaggedContentParser
|
||||
|
||||
`MultiTaggedContentParser` asks LLM to generate specific content within multiple tag pairs. The content from different tag pairs will be parsed into a single Python dictionary. Its usage is similar to `MarkdownJsonDictParser`, but the initialization method is different, and it is more suitable for weak LLMs or complex return content.
|
||||
|
||||
##### Initialization & Format Instruction Template
|
||||
|
||||
Within `MultiTaggedContentParser`, each tag pair will be specified by as `TaggedContent` object, which contains
|
||||
- Tag name (`name`), the key value in the returned dictionary
|
||||
- Start tag (`tag_begin`)
|
||||
- Hint for content (`content_hint`)
|
||||
- End tag (`tag_end`)
|
||||
- Content parsing indication (`parse_json`), default as `False`. When set to `True`, the parser will automatically add hint that requires JSON object between the tags, and its extracted content will be parsed into a Python object via `json.loads`
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MultiTaggedContentParser, TaggedContent
|
||||
parser = MultiTaggedContentParser(
|
||||
TaggedContent(
|
||||
name="thought",
|
||||
tag_begin="[THOUGHT]",
|
||||
content_hint="what you thought",
|
||||
tag_end="[/THOUGHT]"
|
||||
),
|
||||
TaggedContent(
|
||||
name="speak",
|
||||
tag_begin="[SPEAK]",
|
||||
content_hint="what you speak",
|
||||
tag_end="[/SPEAK]"
|
||||
),
|
||||
TaggedContent(
|
||||
name="finish_discussion",
|
||||
tag_begin="[FINISH_DISCUSSION]",
|
||||
content_hint="true/false, whether the discussion is finished",
|
||||
tag_end="[/FINISH_DISCUSSION]",
|
||||
parse_json=True, # we expect the content of this field to be parsed directly into a Python boolean value
|
||||
)
|
||||
)
|
||||
|
||||
print(parser.format_instruction)
|
||||
```
|
||||
|
||||
```
|
||||
Respond with specific tags as outlined below, and the content between [FINISH_DISCUSSION] and [/FINISH_DISCUSSION] MUST be a JSON object:
|
||||
[THOUGHT]what you thought[/THOUGHT]
|
||||
[SPEAK]what you speak[/SPEAK]
|
||||
[FINISH_DISCUSSION]true/false, whether the discussion is finished[/FINISH_DISCUSSION]
|
||||
```
|
||||
|
||||
##### Parse Function
|
||||
|
||||
- `MultiTaggedContentParser`'s parsing result is a dictionary, whose keys are the value of `name` in the `TaggedContent` objects.
|
||||
The following is an example of parsing the LLM response in the werewolf game:
|
||||
|
||||
```python
|
||||
res_dict = parser.parse(
|
||||
ModelResponse(
|
||||
text="""As a werewolf, I should keep pretending to be a villager
|
||||
[THOUGHT]The others didn't realize I was a werewolf. I should end the discussion soon.[/THOUGHT]
|
||||
[SPEAK]I agree with you.[/SPEAK]
|
||||
[FINISH_DISCUSSION]true[/FINISH_DISCUSSION]"""
|
||||
)
|
||||
)
|
||||
|
||||
print(res_dict)
|
||||
```
|
||||
|
||||
```
|
||||
{
|
||||
"thought": "The others didn't realize I was a werewolf. I should end the discussion soon.",
|
||||
"speak": "I agree with you.",
|
||||
"finish_discussion": true
|
||||
}
|
||||
```
|
||||
|
||||
### JSON / Python Object Type
|
||||
|
||||
#### MarkdownJsonObjectParser
|
||||
|
||||
`MarkdownJsonObjectParser` also uses the \```json and \``` tags in Markdown, but does not limit the content type. It can be a list, dictionary, number, string, etc., which can be parsed into a Python object via `json.loads`.
|
||||
|
||||
##### Initialization & Format Instruction Template
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownJsonObjectParser
|
||||
|
||||
parser = MarkdownJsonObjectParser(
|
||||
content_hint="{A list of numbers.}"
|
||||
)
|
||||
|
||||
print(parser.format_instruction)
|
||||
```
|
||||
|
||||
````
|
||||
You should respond a json object in a json fenced code block as follows:
|
||||
```json
|
||||
{a list of numbers}
|
||||
```
|
||||
````
|
||||
|
||||
##### Parse Function
|
||||
|
||||
````python
|
||||
res = parser.parse(
|
||||
ModelResponse(
|
||||
text="""Yes, here is the generated list
|
||||
```json
|
||||
[1,2,3,4,5]
|
||||
```
|
||||
""")
|
||||
)
|
||||
|
||||
print(type(res))
|
||||
print(res)
|
||||
````
|
||||
|
||||
```
|
||||
<class 'list'>
|
||||
[1, 2, 3, 4, 5]
|
||||
```
|
||||
|
||||
## Typical Use Cases
|
||||
|
||||
### WereWolf Game
|
||||
|
||||
Werewolf game is a classic use case of dictionary parser. In different stages of the game, the same agent needs to generate different identification fields in addition to `"thought"` and `"speak"`, such as whether the discussion is over, whether the seer uses its ability, whether the witch uses the antidote and poison, and voting.
|
||||
|
||||
AgentScope has built-in examples of [werewolf game](https://github.com/modelscope/agentscope/tree/main/examples/game_werewolf), which uses `DictDialogAgent` class and different parsers to achieve flexible target format switching. By using the post-processing function of the parser, it separates "thought" and "speak", and controls the progress of the game successfully.
|
||||
More details can be found in the werewolf game [source code](https://github.com/modelscope/agentscope/tree/main/examples/game_werewolf).
|
||||
|
||||
### ReAct Agent and Tool Usage
|
||||
|
||||
`ReActAgent` is an agent class built for tool usage in AgentScope, based on the ReAct algorithm, and can be used with different tool functions. The tool call, format parsing, and implementation of `ReActAgent` are similar to the parser. For detailed implementation, please refer to the [source code](https://github.com/modelscope/agentscope/blob/main/src/agentscope/agents/react_agent.py).
|
||||
|
||||
|
||||
## Customized Parser
|
||||
|
||||
AgentScope provides a base class `ParserBase` for parsers. Developers can inherit this base class, and implement the `format_instruction` attribute and `parse` method to create their own parser.
|
||||
|
||||
For dictionary type parsing, you can also inherit the `agentscope.parser.DictFilterMixin` class to implement post-processing for dictionary type.
|
||||
|
||||
```python
|
||||
from abc import ABC, abstractmethod
|
||||
|
||||
from agentscope.models import ModelResponse
|
||||
|
||||
|
||||
class ParserBase(ABC):
|
||||
"""The base class for model response parser."""
|
||||
|
||||
format_instruction: str
|
||||
"""The instruction for the response format."""
|
||||
|
||||
@abstractmethod
|
||||
def parse(self, response: ModelResponse) -> ModelResponse:
|
||||
"""Parse the response text to a specific object, and stored in the
|
||||
parsed field of the response object."""
|
||||
|
||||
# ...
|
||||
```
|
||||
332
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/204-service.md
Normal file
332
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/204-service.md
Normal file
@@ -0,0 +1,332 @@
|
||||
(204-service-en)=
|
||||
|
||||
# Tool
|
||||
|
||||
Service function is a set of multi-functional utility tools that can be
|
||||
used to enhance the capabilities of agents, such as executing Python code,
|
||||
web search, file operations, and more.
|
||||
This tutorial provides an overview of the service functions available in
|
||||
AgentScope and how to use them to enhance the capabilities of your agents.
|
||||
|
||||
## Built-in Service Functions
|
||||
|
||||
The following table outlines the various Service functions by type. These functions can be called using `agentscope.service.{function_name}`.
|
||||
|
||||
| Service Scene | Service Function Name | Description |
|
||||
|-----------------------------|----------------------------|----------------------------------------------------------------------------------------------------------------|
|
||||
| Code | `execute_python_code` | Execute a piece of Python code, optionally inside a Docker container. |
|
||||
| Retrieval | `retrieve_from_list` | Retrieve a specific item from a list based on given criteria. |
|
||||
| | `cos_sim` | Compute the cosine similarity between two different embeddings. |
|
||||
| SQL Query | `query_mysql` | Execute SQL queries on a MySQL database and return results. |
|
||||
| | `query_sqlite` | Execute SQL queries on a SQLite database and return results. |
|
||||
| | `query_mongodb` | Perform queries or operations on a MongoDB collection. |
|
||||
| Text Processing | `summarization` | Summarize a piece of text using a large language model to highlight its main points. |
|
||||
| Web | `bing_search` | Perform bing search |
|
||||
| | `google_search` | Perform google search |
|
||||
| | `arxiv_search` | Perform arXiv search |
|
||||
| | `download_from_url` | Download file from given URL. |
|
||||
| | `load_web` | Load and parse the web page of the specified url (currently only supports HTML). |
|
||||
| | `digest_webpage` | Digest the content of a already loaded web page (currently only supports HTML).
|
||||
| | `dblp_search_publications` | Search publications in the DBLP database
|
||||
| | `dblp_search_authors` | Search for author information in the DBLP database |
|
||||
| | `dblp_search_venues` | Search for venue information in the DBLP database |
|
||||
| File | `create_file` | Create a new file at a specified path, optionally with initial content. |
|
||||
| | `delete_file` | Delete a file specified by a file path. |
|
||||
| | `move_file` | Move or rename a file from one path to another. |
|
||||
| | `create_directory` | Create a new directory at a specified path. |
|
||||
| | `delete_directory` | Delete a directory and all its contents. |
|
||||
| | `move_directory` | Move or rename a directory from one path to another. |
|
||||
| | `read_text_file` | Read and return the content of a text file. |
|
||||
| | `write_text_file` | Write text content to a file at a specified path. |
|
||||
| | `read_json_file` | Read and parse the content of a JSON file. |
|
||||
| | `write_json_file` | Serialize a Python object to JSON and write to a file. |
|
||||
| Multi Modality | `dashscope_text_to_image` | Convert text to image using Dashscope API. |
|
||||
| | `dashscope_image_to_text` | Convert image to text using Dashscope API. |
|
||||
| | `dashscope_text_to_audio` | Convert text to audio using Dashscope API. |
|
||||
| | `openai_text_to_image` | Convert text to image using OpenAI API
|
||||
| | `openai_edit_image` | Edit an image based on the provided mask and prompt using OpenAI API
|
||||
| | `openai_create_image_variation` | Create variations of an image using OpenAI API
|
||||
| | `openai_image_to_text` | Convert text to image using OpenAI API
|
||||
| | `openai_text_to_audio` | Convert text to audio using OpenAI API
|
||||
| | `openai_audio_to_text` | Convert audio to text using OpenAI API
|
||||
|
||||
|
||||
| *More services coming soon* | | More service functions are in development and will be added to AgentScope to further enhance its capabilities. |
|
||||
|
||||
About each service function, you can find detailed information in the
|
||||
[API document](https://modelscope.github.io/agentscope/).
|
||||
|
||||
## How to use Service Functions
|
||||
|
||||
AgentScope provides two classes for service functions,
|
||||
`ServiceToolkit` and `ServiceResponse`.
|
||||
|
||||
### About Service Toolkit
|
||||
|
||||
The use of tools for LLM usually involves five steps:
|
||||
|
||||
1. **Prepare tool functions**. That is, developers should pre-process the
|
||||
functions by providing necessary parameters, e.g. api key, username,
|
||||
password, etc.
|
||||
2. **Prepare instruction for LLM**. A detailed description for these tool
|
||||
functions are required for the LLM to understand them properly.
|
||||
3. **Guide LLM how to use tool functions**. A format description for calling
|
||||
functions is required.
|
||||
4. **Parse LLM response**. Once the LLM generates a response,
|
||||
we need to parse it according to above format in the third step.
|
||||
5. **Call functions and handle exceptions**. Calling the functions, return
|
||||
the results, and handle exceptions.
|
||||
|
||||
To simplify the above steps and improve reusability, AgentScope introduces
|
||||
`ServiceToolkit`. It can
|
||||
- register python functions
|
||||
- generate tool function descriptions in both string and JSON schema format
|
||||
- generate usage instruction for LLM
|
||||
- parse the model response, call the tool functions, and handle exceptions
|
||||
|
||||
#### How to use
|
||||
|
||||
Follow the steps below to use `ServiceToolkit`:
|
||||
|
||||
1. Init a `ServiceToolkit` object and register service functions with necessary
|
||||
parameters. Take the following Bing search function as an example.
|
||||
|
||||
```python
|
||||
def bing_search(
|
||||
question: str,
|
||||
api_key: str,
|
||||
num_results: int = 10,
|
||||
**kwargs: Any,
|
||||
) -> ServiceResponse:
|
||||
"""
|
||||
Search question in Bing Search API and return the searching results
|
||||
|
||||
Args:
|
||||
question (`str`):
|
||||
The search query string.
|
||||
api_key (`str`):
|
||||
The API key provided for authenticating with the Bing Search API.
|
||||
num_results (`int`, defaults to `10`):
|
||||
The number of search results to return.
|
||||
**kwargs (`Any`):
|
||||
Additional keyword arguments to be included in the search query.
|
||||
For more details, please refer to
|
||||
https://learn.microsoft.com/en-us/bing/search-apis/bing-web-search/reference/query-parameters
|
||||
|
||||
[omitted for brevity]
|
||||
"""
|
||||
```
|
||||
|
||||
We register the function in a `ServiceToolkit` object by providing `api_key` and `num_results` as necessary parameters.
|
||||
|
||||
```python
|
||||
from agentscope.service import ServiceToolkit
|
||||
|
||||
service_toolkit = ServiceToolkit()
|
||||
|
||||
service_toolkit.add(
|
||||
bing_search,
|
||||
api_key="xxx",
|
||||
num_results=3
|
||||
)
|
||||
```
|
||||
|
||||
2. Use the `tools_instruction` attribute to instruct LLM in prompt, or use the `json_schemas` attribute to get the JSON schema format descriptions to construct customized instruction or directly use in model APIs (e.g. OpenAI Chat API).
|
||||
|
||||
````text
|
||||
>> print(service_toolkit.tools_instruction)
|
||||
## Tool Functions:
|
||||
The following tool functions are available in the format of
|
||||
```
|
||||
{index}. {function name}: {function description}
|
||||
{argument1 name} ({argument type}): {argument description}
|
||||
{argument2 name} ({argument type}): {argument description}
|
||||
...
|
||||
```
|
||||
|
||||
1. bing_search: Search question in Bing Search API and return the searching results
|
||||
question (str): The search query string.
|
||||
````
|
||||
````text
|
||||
>> print(service_toolkit.json_schemas)
|
||||
{
|
||||
"bing_search": {
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "bing_search",
|
||||
"description": "Search question in Bing Search API and return the searching results",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"question": {
|
||||
"type": "string",
|
||||
"description": "The search query string."
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"question"
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
````
|
||||
|
||||
3. Guide LLM how to use tool functions by the `tools_calling_format` attribute.
|
||||
The ServiceToolkit module requires LLM to return a list of dictionaries in
|
||||
JSON format, where each dictionary represents a function call. It must
|
||||
contain two fields, `name` and `arguments`, where `name` is the function name
|
||||
and `arguments` is a dictionary that maps from the argument name to the
|
||||
argument value.
|
||||
|
||||
|
||||
```text
|
||||
>> print(service_toolkit.tools_calling_format)
|
||||
[{"name": "{function name}", "arguments": {"{argument1 name}": xxx, "{argument2 name}": xxx}}]
|
||||
```
|
||||
|
||||
4. Parse the LLM response and call functions by its `parse_and_call_func`
|
||||
method. This function takes a string or a parsed dictionary as input.
|
||||
- When the input is a string, this function will parse it accordingly and execute the function with the parsed arguments.
|
||||
- While if the input is a parse dictionary, it will call the function directly.
|
||||
|
||||
```python
|
||||
# a string input
|
||||
string_input = '[{"name": "bing_search", "arguments": {"question": "xxx"}}]'
|
||||
res_of_string_input = service_toolkit.parse_and_call_func(string_input)
|
||||
|
||||
# or a parsed dictionary
|
||||
dict_input = [{"name": "bing_search", "arguments": {"question": "xxx"}}]
|
||||
# res_of_dict_input is the same as res_of_string_input
|
||||
res_of_dict_input = service_toolkit.parse_and_call_func(dict_input)
|
||||
|
||||
print(res_of_string_input)
|
||||
```
|
||||
```
|
||||
1. Execute function bing_search
|
||||
[ARGUMENTS]:
|
||||
question: xxx
|
||||
[STATUS]: SUCCESS
|
||||
[RESULT]: ...
|
||||
```
|
||||
|
||||
More specific examples refer to the `ReActAgent` class in `agentscope.agents`.
|
||||
|
||||
#### Create new Service Function
|
||||
|
||||
A new service function that can be used by `ServiceToolkit` should meet the following requirements:
|
||||
|
||||
1. Well-formatted docstring (Google style is recommended), so that the
|
||||
`ServiceToolkit` can extract both the function descriptions.
|
||||
2. The name of the service function should be self-explanatory,
|
||||
so that the LLM can understand the function and use it properly.
|
||||
3. The typing of the arguments should be provided when defining
|
||||
the function (e.g. `def func(a: int, b: str, c: bool)`), so that
|
||||
the agent can specify the arguments properly.
|
||||
|
||||
|
||||
### About ServiceResponse
|
||||
|
||||
`ServiceResponse` is a wrapper for the execution results of the services,
|
||||
containing two fields, `status` and `content`. When the Service function
|
||||
runs to completion normally, `status` is `ServiceExecStatus.SUCCESS`, and
|
||||
`content` is the return value of the function. When an error occurs during
|
||||
execution, `status` is `ServiceExecStatus.Error`, and `content` contains
|
||||
the error message.
|
||||
|
||||
```python
|
||||
class ServiceResponse(dict):
|
||||
"""Used to wrap the execution results of the services"""
|
||||
|
||||
__setattr__ = dict.__setitem__
|
||||
__getattr__ = dict.__getitem__
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
status: ServiceExecStatus,
|
||||
content: Any,
|
||||
):
|
||||
"""Constructor of ServiceResponse
|
||||
|
||||
Args:
|
||||
status (`ServiceExeStatus`):
|
||||
The execution status of the service.
|
||||
content (`Any`)
|
||||
If the argument`status` is `SUCCESS`, `content` is the
|
||||
response. We use `object` here to support various objects,
|
||||
e.g. str, dict, image, video, etc.
|
||||
Otherwise, `content` is the error message.
|
||||
"""
|
||||
self.status = status
|
||||
self.content = content
|
||||
|
||||
# [omitted for brevity]
|
||||
```
|
||||
|
||||
## Example
|
||||
|
||||
```python
|
||||
import json
|
||||
import inspect
|
||||
from agentscope.service import ServiceResponse
|
||||
from agentscope.agents import AgentBase
|
||||
from agentscope.message import Msg
|
||||
|
||||
from typing import Optional, Union, Sequence
|
||||
|
||||
|
||||
def create_file(file_path: str, content: str = "") -> ServiceResponse:
|
||||
"""
|
||||
Create a file and write content to it.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the file to be created.
|
||||
content (str): The content to be written to the file.
|
||||
|
||||
Returns:
|
||||
ServiceResponse: A boolean indicating success or failure, and a
|
||||
string containing any error message (if any), including the error type.
|
||||
"""
|
||||
# ... [omitted for brevity]
|
||||
|
||||
|
||||
class YourAgent(AgentBase):
|
||||
# ... [omitted for brevity]
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# ... [omitted for brevity]
|
||||
|
||||
# construct a prompt to ask the agent to provide the parameters in JSON format
|
||||
prompt = (
|
||||
f"To complete the user request\n```{x['content']}```\n"
|
||||
"Please provide the necessary parameters in JSON format for the "
|
||||
"function:\n"
|
||||
f"Function: {create_file.__name__}\n"
|
||||
"Description: Create a file and write content to it.\n"
|
||||
)
|
||||
|
||||
# add detailed information about the function parameters
|
||||
sig = inspect.signature(create_file)
|
||||
parameters = sig.parameters.items()
|
||||
params_prompt = "\n".join(
|
||||
f"- {name} ({param.annotation.__name__}): "
|
||||
f"{'(default: ' + json.dumps(param.default) + ')'if param.default is not inspect.Parameter.empty else ''}"
|
||||
for name, param in parameters
|
||||
)
|
||||
prompt += params_prompt
|
||||
|
||||
# get the model response
|
||||
model_response = self.model(prompt).text
|
||||
|
||||
# parse the model response and call the create_file function
|
||||
try:
|
||||
kwargs = json.loads(model_response)
|
||||
create_file(**kwargs)
|
||||
except:
|
||||
# Error handling
|
||||
pass
|
||||
|
||||
# ... [omitted for brevity]
|
||||
```
|
||||
|
||||
[[Return to Top]](#204-service-en)
|
||||
223
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/205-memory.md
Normal file
223
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/205-memory.md
Normal file
@@ -0,0 +1,223 @@
|
||||
(205-memory-en)=
|
||||
|
||||
# Memory
|
||||
|
||||
In AgentScope, memory is used to store historical information, allowing the
|
||||
agent to provide more coherent and natural responses based on context.
|
||||
This tutorial will first introduce the carrier of information in memory,
|
||||
message, and then introduce the functions and usage of the memory module in
|
||||
AgentScope.
|
||||
|
||||
## About Message
|
||||
|
||||
### `MessageBase` Class
|
||||
|
||||
In AgentScope, the message base class is a subclass of Python dictionary,
|
||||
consisting of two required fields (`name` and `content`) and an optional
|
||||
field (`url`).
|
||||
Specifically, the `name` field represents the originator of the message,
|
||||
the `content` field represents the content of the message, and the `url`
|
||||
field represents the data link attached to the message, which can be a
|
||||
local link to multi-modal data or a web link.
|
||||
As a dictionary type, developers can also add other fields
|
||||
as needed. When a message is created, a unique ID is automatically
|
||||
generated to identify the message. The creation time of the message is also
|
||||
automatically recorded in the form of a timestamp.
|
||||
|
||||
In the specific implementation, AgentScope first provides a `MessageBase`
|
||||
base class to define the basic properties and usage of messages.
|
||||
Unlike general dictionary types, the instantiated objects of `MessageBase`
|
||||
can access attribute values through `object_name.{attribute_name}` or
|
||||
`object_name['attribute_name']`.
|
||||
The key attributes of the `MessageBase` class are as follows:
|
||||
|
||||
- **`name`**: This attribute denotes the originator of the message. It's a critical piece of metadata, useful in scenarios where distinguishing between different speakers is necessary.
|
||||
- **`content`**: The substance of the message itself. It can include text, structured data, or any other form of content that is relevant to the interaction and requires processing by the agent.
|
||||
- **`url`**: An optional attribute that allows the message to be linked to external resources. These can be direct links to files, multi-modal data, or web pages.
|
||||
- **`timestamp`**: A timestamp indicating when the message was created.
|
||||
- **`id`**: Each message is assigned a unique identifier (ID) upon creation.
|
||||
|
||||
```python
|
||||
class MessageBase(dict):
|
||||
"""Base Message class, which is used to maintain information for dialog,
|
||||
memory and used to construct prompt.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
content: Any,
|
||||
url: Optional[Union[Sequence[str], str]] = None,
|
||||
timestamp: Optional[str] = None,
|
||||
**kwargs: Any,
|
||||
) -> None:
|
||||
"""Initialize the message object
|
||||
|
||||
Args:
|
||||
name (`str`):
|
||||
The name of who send the message. It's often used in
|
||||
role-playing scenario to tell the name of the sender.
|
||||
However, you can also only use `role` when calling openai api.
|
||||
The usage of `name` refers to
|
||||
https://cookbook.openai.com/examples/how_to_format_inputs_to_chatgpt_models.
|
||||
content (`Any`):
|
||||
The content of the message.
|
||||
url (`Optional[Union[list[str], str]]`, defaults to None):
|
||||
A url to file, image, video, audio or website.
|
||||
timestamp (`Optional[str]`, defaults to None):
|
||||
The timestamp of the message, if None, it will be set to
|
||||
current time.
|
||||
**kwargs (`Any`):
|
||||
Other attributes of the message. For OpenAI API, you should
|
||||
add "role" from `["system", "user", "assistant", "function"]`.
|
||||
When calling OpenAI API, `"role": "assistant"` will be added
|
||||
to the messages that don't have "role" attribute.
|
||||
|
||||
"""
|
||||
# id and timestamp will be added to the object as its attributes
|
||||
# rather than items in dict
|
||||
self.id = uuid4().hex
|
||||
if timestamp is None:
|
||||
self.timestamp = _get_timestamp()
|
||||
else:
|
||||
self.timestamp = timestamp
|
||||
|
||||
self.name = name
|
||||
self.content = content
|
||||
|
||||
if url:
|
||||
self.url = url
|
||||
|
||||
self.update(kwargs)
|
||||
|
||||
def __getattr__(self, key: Any) -> Any:
|
||||
try:
|
||||
return self[key]
|
||||
except KeyError as e:
|
||||
raise AttributeError(f"no attribute '{key}'") from e
|
||||
|
||||
def __setattr__(self, key: Any, value: Any) -> None:
|
||||
self[key] = value
|
||||
|
||||
def __delattr__(self, key: Any) -> None:
|
||||
try:
|
||||
del self[key]
|
||||
except KeyError as e:
|
||||
raise AttributeError(f"no attribute '{key}'") from e
|
||||
|
||||
def to_str(self) -> str:
|
||||
"""Return the string representation of the message"""
|
||||
raise NotImplementedError
|
||||
|
||||
def serialize(self) -> str:
|
||||
"""Return the serialized message."""
|
||||
raise NotImplementedError
|
||||
|
||||
# ... [省略代码以简化]
|
||||
```
|
||||
|
||||
### `Msg` Class
|
||||
|
||||
`Msg` class extends `MessageBase` and represents a standard *message*.
|
||||
`Msg` provides concrete definitions for the `to_str` and `serialize`
|
||||
methods to enable string representation and serialization suitable for the
|
||||
agent's operational context.
|
||||
Within an `Agent` class, its `reply` function typically returns an instance of
|
||||
`Msg` to facilitate message passing within AgentScope.
|
||||
|
||||
```python
|
||||
class Msg(MessageBase):
|
||||
"""The Message class."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
content: Any,
|
||||
url: Optional[Union[Sequence[str], str]] = None,
|
||||
timestamp: Optional[str] = None,
|
||||
echo: bool = False,
|
||||
**kwargs: Any,
|
||||
) -> None:
|
||||
super().__init__(
|
||||
name=name,
|
||||
content=content,
|
||||
url=url,
|
||||
timestamp=timestamp,
|
||||
**kwargs,
|
||||
)
|
||||
if echo:
|
||||
logger.chat(self)
|
||||
|
||||
def to_str(self) -> str:
|
||||
"""Return the string representation of the message"""
|
||||
return f"{self.name}: {self.content}"
|
||||
|
||||
def serialize(self) -> str:
|
||||
return json.dumps({"__type": "Msg", **self})
|
||||
```
|
||||
|
||||
## About Memory
|
||||
|
||||
### `MemoryBase` Class
|
||||
|
||||
`MemoryBase` is an abstract class that handles an agent's memory in a structured way. It defines operations for storing, retrieving, deleting, and manipulating *message*'s content.
|
||||
|
||||
```python
|
||||
class MemoryBase(ABC):
|
||||
# ... [code omitted for brevity]
|
||||
|
||||
def get_memory(
|
||||
self,
|
||||
return_type: PromptType = PromptType.LIST,
|
||||
recent_n: Optional[int] = None,
|
||||
filter_func: Optional[Callable[[int, dict], bool]] = None,
|
||||
) -> Union[list, str]:
|
||||
raise NotImplementedError
|
||||
|
||||
def add(self, memories: Union[list[dict], dict]) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def delete(self, index: Union[Iterable, int]) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def load(
|
||||
self,
|
||||
memories: Union[str, dict, list],
|
||||
overwrite: bool = False,
|
||||
) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def export(
|
||||
self,
|
||||
to_mem: bool = False,
|
||||
file_path: Optional[str] = None,
|
||||
) -> Optional[list]:
|
||||
raise NotImplementedError
|
||||
|
||||
def clear(self) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def size(self) -> int:
|
||||
raise NotImplementedError
|
||||
```
|
||||
|
||||
Here are the key methods of `MemoryBase`:
|
||||
|
||||
- **`get_memory`**: This method is responsible for retrieving stored messages from the agent's memory. It can return these messages in different formats as specified by the `return_type`. The method can also retrieve a specific number of recent messages if `recent_n` is provided, and it can apply a filtering function (`filter_func`) to select messages based on custom criteria.
|
||||
- **`add`**: This method is used to add a new *message* to the agent's memory. It can accept a single message or a list of messages. Each message is typically an instance of `MessageBase` or its subclasses.
|
||||
- **`delete`**: This method enables the removal of messages from memory by their index (or indices if an iterable is provided).
|
||||
- **`load`**: This method allows for the bulk loading of messages into the agent's memory from an external source. The `overwrite` parameter determines whether to clear the existing memory before loading the new set of messages.
|
||||
- **`export`**: This method facilitates exporting the stored *message* from the agent's memory either to an external file (specified by `file_path`) or directly into the working memory of the program (if `to_mem` is set to `True`).
|
||||
- **`clear`**: This method purges all *message* from the agent's memory, essentially resetting it.
|
||||
- **`size`**: This method returns the number of messages currently stored in the agent's memory.
|
||||
|
||||
### `TemporaryMemory`
|
||||
|
||||
The `TemporaryMemory` class is a concrete implementation of `MemoryBase`, providing a memory store that exists during the runtime of an agent, which is used as the default memory type of agents. Besides all the behaviors from `MemoryBase`, the `TemporaryMemory` additionally provides methods for retrieval:
|
||||
|
||||
- **`retrieve_by_embedding`**: Retrieves `messages` that are most similar to a query, based on their embeddings. It uses a provided metric to determine the relevance and can return the top `k` most relevant messages.
|
||||
- **`get_embeddings`**: Return the embeddings for all messages in memory. If a message does not have an embedding and an embedding model is provided, it will generate and store the embedding for the message.
|
||||
|
||||
For more details about the usage of `Memory` and `Msg`, please refer to the API references.
|
||||
|
||||
[[Return to the top]](#205-memory-en)
|
||||
596
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/206-prompt.md
Normal file
596
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/206-prompt.md
Normal file
@@ -0,0 +1,596 @@
|
||||
(206-prompt-en)=
|
||||
|
||||
# Prompt Engineering
|
||||
|
||||
Prompt engineering is critical in LLM-empowered applications. However,
|
||||
crafting prompts for large language models (LLMs) can be challenging,
|
||||
especially with different requirements from various model APIs.
|
||||
|
||||
To ease the process of adapting prompt to different model APIs, AgentScope
|
||||
provides a structured way to organize different data types (e.g. instruction,
|
||||
hints, dialogue history) into the desired format.
|
||||
|
||||
Note there is no **one-size-fits-all** solution for prompt crafting.
|
||||
**The goal of built-in strategies is to enable beginners to smoothly invoke
|
||||
the model API, rather than achieve the best performance**.
|
||||
For advanced users, we highly recommend developers to customize prompts
|
||||
according to their needs and model API requirements.
|
||||
|
||||
## Challenges in Prompt Construction
|
||||
|
||||
In multi-agent applications, LLM often plays different roles in a
|
||||
conversation. When using third-party chat APIs, it has the following
|
||||
challenges:
|
||||
|
||||
1. Most third-party chat APIs are designed for chatbot scenario, and the
|
||||
`role` field only supports `"user"` and `"assistant"`.
|
||||
|
||||
2. Some model APIs require `"user"` and `"assistant"` must speak alternatively,
|
||||
and `"user"` must speak in the beginning and end of the input messages list.
|
||||
Such requirements make it difficult to build a multi-agent conversation
|
||||
when the agent may act as many different roles and speak continuously.
|
||||
|
||||
To help beginners to quickly start with AgentScope, we provide the
|
||||
following built-in strategies for most chat and generation related model APIs.
|
||||
|
||||
## Built-in Prompt Strategies
|
||||
|
||||
In AgentScope, we provide built-in strategies for the following chat and
|
||||
generation model APIs.
|
||||
|
||||
- [OpenAIChatWrapper](#openaichatwrapper)
|
||||
- [DashScopeChatWrapper](#dashscopechatwrapper)
|
||||
- [DashScopeMultiModalWrapper](#dashscopemultimodalwrapper)
|
||||
- [OllamaChatWrapper](#ollamachatwrapper)
|
||||
- [OllamaGenerationWrapper](#ollamagenerationwrapper)
|
||||
- [GeminiChatWrapper](#geminichatwrapper)
|
||||
- [ZhipuAIChatWrapper](#zhipuaichatwrapper)
|
||||
|
||||
These strategies are implemented in the `format` functions of the model
|
||||
wrapper classes.
|
||||
It accepts `Msg` objects, a list of `Msg` objects, or their mixture as input.
|
||||
However, `format` function will first reorganize them into a list of `Msg`
|
||||
objects, so for simplicity in the following sections we treat the input as a
|
||||
list of `Msg` objects.
|
||||
|
||||
### OpenAIChatWrapper
|
||||
|
||||
`OpenAIChatWrapper` encapsulates the OpenAI chat API, it takes a list of
|
||||
dictionaries as input, where the dictionary must obey the following rules
|
||||
(updated in 2024/03/22):
|
||||
|
||||
- Require `role` and `content` fields, and an optional `name` field.
|
||||
- The `role` field must be either `"system"`, `"user"`, or `"assistant"`.
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
##### Non-Vision Models
|
||||
|
||||
In OpenAI Chat API, the `name` field enables the model to distinguish
|
||||
different speakers in the conversation. Therefore, the strategy of `format`
|
||||
function in `OpenAIChatWrapper` is simple:
|
||||
|
||||
- `Msg`: Pass a dictionary with `role`, `content`, and `name` fields directly.
|
||||
- `List`: Parse each element in the list according to the above rules.
|
||||
|
||||
An example is shown below:
|
||||
|
||||
```python
|
||||
from agentscope.models import OpenAIChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = OpenAIChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="gpt-4",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi.", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{"role": "system", "name": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "assistant", "name": "Bob", "content": "Hi."},
|
||||
{"role": "assistant", "name": "Alice", "content": "Nice to meet you!"),
|
||||
]
|
||||
```
|
||||
|
||||
##### Vision Models
|
||||
|
||||
For vision models (gpt-4-turbo, gpt-4o, ...), if the input message contains image urls, the generated `content` field will be a list of dicts, which contains text and image urls.
|
||||
|
||||
Specifically, the web image urls will be pass to OpenAI Chat API directly, while the local image urls will be converted to base64 format. More details please refer to the [official guidance](https://platform.openai.com/docs/guides/vision).
|
||||
|
||||
Note the invalid image urls (e.g. `/Users/xxx/test.mp3`) will be ignored.
|
||||
|
||||
```python
|
||||
from agentscope.models import OpenAIChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = OpenAIChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="gpt-4o",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="user", content="Describe this image", role="user", url="https://xxx.png"),
|
||||
Msg(name="user", content="And these images", role="user", url=["/Users/xxx/test.png", "/Users/xxx/test.mp3"]),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```python
|
||||
[
|
||||
{
|
||||
"role": "system",
|
||||
"name": "system",
|
||||
"content": "You are a helpful assistant"
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"name": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Describe this image"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://xxx.png"
|
||||
}
|
||||
},
|
||||
]
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"name": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "And these images"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "data:image/png;base64,YWJjZGVm..." # for /Users/xxx/test.png
|
||||
}
|
||||
},
|
||||
]
|
||||
},
|
||||
]
|
||||
```
|
||||
|
||||
### DashScopeChatWrapper
|
||||
|
||||
`DashScopeChatWrapper` encapsulates the DashScope chat API, which takes a list of messages as input. The message must obey the following rules (updated in 2024/03/22):
|
||||
|
||||
- Require `role` and `content` fields, and `role` must be either `"user"`
|
||||
`"system"` or `"assistant"`.
|
||||
- If `role` is `"system"`, this message must and can only be the first
|
||||
message in the list.
|
||||
- The `user` and `assistant` must speak alternatively.
|
||||
- The `user` must speak in the beginning and end of the input messages list.
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
If the role field of the first message is `"system"`, it will be converted into a single message with the `role` field as `"system"` and the `content` field as the system message. The rest of the messages will be converted into a message with the `role` field as `"user"` and the `content` field as the dialogue history.
|
||||
|
||||
An example is shown below:
|
||||
|
||||
```python
|
||||
from agentscope.models import DashScopeChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = DashScopeChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="qwen-max",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi!", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"},
|
||||
]
|
||||
```
|
||||
|
||||
### DashScopeMultiModalWrapper
|
||||
|
||||
`DashScopeMultiModalWrapper` encapsulates the DashScope multimodal conversation API, which takes a list of messages as input. The message must obey the following rules (updated in 2024/04/04):
|
||||
|
||||
- Each message is a dictionary with `role` and `content` fields.
|
||||
- The `role` field must be either `"user"`, `"system"`, or `"assistant"`.
|
||||
- The `content` field must be a list of dictionaries, where
|
||||
- Each dictionary only contains one key-value pair, whose key must be `text`, `image` or `audio`.
|
||||
- `text` field is a string, representing the text content.
|
||||
- `image` field is a string, representing the image url.
|
||||
- `audio` field is a string, representing the audio url.
|
||||
- The `content` field can contain multiple dictionaries with the key `image` or multiple dictionaries with the key `audio` at the same time. For example:
|
||||
|
||||
```python
|
||||
[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"text": "What's the difference between these two pictures?"},
|
||||
{"image": "https://xxx1.png"},
|
||||
{"image": "https://xxx2.png"}
|
||||
]
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": [{"text": "The first picture is a cat, and the second picture is a dog."}]
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [{"text": "I see, thanks!"}]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
- The message with the `role` field as `"system"` must and can only be the first message in the list.
|
||||
- The last message must have the `role` field as `"user"`.
|
||||
- The `user` and `assistant` messages must alternate.
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
Based on the above rules, the `format` function in `DashScopeMultiModalWrapper` will parse the input messages as follows:
|
||||
|
||||
- If the first message in the input message list has a `role` field with the value `"system"`, it will be converted into a system message with the `role` field as `"system"` and the `content` field as the system message. If the `url` field in the input `Msg` object is not `None`, a dictionary with the key `"image"` or `"audio"` will be added to the `content` based on its type.
|
||||
- The rest of the messages will be converted into a message with the `role` field as `"user"` and the `content` field as the dialogue history. For each message, if their `url` field is not `None`, it will add a dictionary with the key `"image"` or `"audio"` to the `content` based on the file type that the `url` points to.
|
||||
|
||||
An example:
|
||||
|
||||
```python
|
||||
from agentscope.models import DashScopeMultiModalWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = DashScopeMultiModalWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="qwen-vl-plus",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system", url="url_to_png1"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi!", role="assistant", url="url_to_png2"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant", url="url_to_png3"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "system",
|
||||
"content": [
|
||||
{"text": "You are a helpful assistant"},
|
||||
{"image": "url_to_png1"}
|
||||
]
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"text": "## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"},
|
||||
{"image": "url_to_png2"},
|
||||
{"image": "url_to_png3"},
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
|
||||
### LiteLLMChatWrapper
|
||||
|
||||
`LiteLLMChatWrapper` encapsulates the litellm chat API, which takes a list of
|
||||
messages as input. The litellm supports different types of models, and each model
|
||||
might need to obey different formats. To simplify the usage, we provide a format
|
||||
that could be compatible with most models. If more specific formats are needed,
|
||||
you can refer to the specific model you use as well as the
|
||||
[litellm](https://github.com/BerriAI/litellm) documentation to customize your
|
||||
own format function for your model.
|
||||
|
||||
|
||||
- format all the messages in the chat history, into a single message with `"user"` as `role`
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
- Messages will consist dialogue history in the `user` message prefixed by the system message and "## Dialogue History".
|
||||
|
||||
```python
|
||||
from agentscope.models import LiteLLMChatWrapper
|
||||
|
||||
model = LiteLLMChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="gpt-3.5-turbo",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You are a helpful assistant", role="system"),
|
||||
[
|
||||
Msg("user", "What is the weather today?", role="user"),
|
||||
Msg("assistant", "It is sunny today", role="assistant"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "user",
|
||||
"content": (
|
||||
"You are a helpful assistant\n\n"
|
||||
"## Dialogue History\nuser: What is the weather today?\n"
|
||||
"assistant: It is sunny today"
|
||||
),
|
||||
},
|
||||
]
|
||||
```
|
||||
|
||||
### OllamaChatWrapper
|
||||
|
||||
`OllamaChatWrapper` encapsulates the Ollama chat API, which takes a list of
|
||||
messages as input. The message must obey the following rules (updated in
|
||||
2024/03/22):
|
||||
|
||||
- Require `role` and `content` fields, and `role` must be either `"user"`,
|
||||
`"system"`, or `"assistant"`.
|
||||
- An optional `images` field can be added to the message
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
- If the role field of the first input message is `"system"`,
|
||||
it will be treated as system prompt and the other messages will consist
|
||||
dialogue history in the system message prefixed by "## Dialogue History".
|
||||
- If the `url` attribute of messages is not `None`, we will gather all urls in
|
||||
the `"images"` field in the returned dictionary.
|
||||
|
||||
```python
|
||||
from agentscope.models import OllamaChatWrapper
|
||||
|
||||
model = OllamaChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="llama2",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi.", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant", url="https://example.com/image.jpg"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a helpful assistant\n\n## Dialogue History\nBob: Hi.\nAlice: Nice to meet you!",
|
||||
"images": ["https://example.com/image.jpg"]
|
||||
},
|
||||
]
|
||||
```
|
||||
|
||||
### OllamaGenerationWrapper
|
||||
|
||||
`OllamaGenerationWrapper` encapsulates the Ollama generation API, which
|
||||
takes a string prompt as input without any constraints (updated to 2024/03/22).
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
If the role field of the first message is `"system"`, a system prompt will be created. The rest of the messages will be combined into dialogue history in string format.
|
||||
|
||||
```python
|
||||
from agentscope.models import OllamaGenerationWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = OllamaGenerationWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="llama2",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi.", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
You are a helpful assistant
|
||||
|
||||
## Dialogue History
|
||||
Bob: Hi.
|
||||
Alice: Nice to meet you!
|
||||
```
|
||||
|
||||
### `GeminiChatWrapper`
|
||||
|
||||
`GeminiChatWrapper` encapsulates the Gemini chat API, which takes a list of
|
||||
messages or a string prompt as input. Similar to DashScope Chat API, if we
|
||||
pass a list of messages, it must obey the following rules:
|
||||
|
||||
- Require `role` and `parts` fields. `role` must be either `"user"`
|
||||
or `"model"`, and `parts` must be a list of strings.
|
||||
- The `user` and `model` must speak alternatively.
|
||||
- The `user` must speak in the beginning and end of the input messages list.
|
||||
|
||||
Such requirements make it difficult to build a multi-agent conversation when
|
||||
an agent may act as many different roles and speak continuously.
|
||||
Therefore, we decide to convert the list of messages into a user message
|
||||
in our built-in `format` function.
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
If the role field of the first message is `"system"`, a system prompt will be added in the beginning. The other messages will be combined into dialogue history.
|
||||
|
||||
**Note** sometimes the `parts` field may contain image urls, which is not
|
||||
supported in `format` function. We recommend developers to customize the
|
||||
prompt according to their needs.
|
||||
|
||||
```python
|
||||
from agentscope.models import GeminiChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = GeminiChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="gemini-pro",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi!", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "user",
|
||||
"parts": [
|
||||
"You are a helpful assistant\n## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### `ZhipuAIChatWrapper`
|
||||
|
||||
`ZhipuAIChatWrapper` encapsulates the ZhipuAI chat API, which takes a list of messages as input. The message must obey the following rules:
|
||||
|
||||
- Require `role` and `content` fields, and `role` must be either `"user"`
|
||||
`"system"` or `"assistant"`.
|
||||
- There must be at least one `user` message.
|
||||
|
||||
#### Prompt Strategy
|
||||
|
||||
If the role field of the first message is `"system"`, it will be converted into a single message with the `role` field as `"system"` and the `content` field as the system message. The rest of the messages will be converted into a message with the `role` field as `"user"` and the `content` field as the dialogue history.
|
||||
|
||||
An example is shown below:
|
||||
|
||||
```python
|
||||
from agentscope.models import ZhipuAIChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = ZhipuAIChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="glm-4",
|
||||
api_key="your api key",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi!", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"},
|
||||
]
|
||||
```
|
||||
|
||||
## Prompt Engine (Will be deprecated in the future)
|
||||
|
||||
AgentScope provides the `PromptEngine` class to simplify the process of crafting
|
||||
prompts for large language models (LLMs).
|
||||
|
||||
## About `PromptEngine` Class
|
||||
|
||||
The `PromptEngine` class provides a structured way to combine different components of a prompt, such as instructions, hints, dialogue history, and user inputs, into a format that is suitable for the underlying language model.
|
||||
|
||||
### Key Features of PromptEngine
|
||||
|
||||
- **Model Compatibility**: It works with any `ModelWrapperBase` subclass.
|
||||
- **Prompt Type**: It supports both string and list-style prompts, aligning with the model's preferred input format.
|
||||
|
||||
### Initialization
|
||||
|
||||
When creating an instance of `PromptEngine`, you can specify the target model and, optionally, the shrinking policy, the maximum length of the prompt, the prompt type, and a summarization model (could be the same as the target model).
|
||||
|
||||
```python
|
||||
model = OpenAIChatWrapper(...)
|
||||
engine = PromptEngine(model)
|
||||
```
|
||||
|
||||
### Joining Prompt Components
|
||||
|
||||
The `join` method of `PromptEngine` provides a unified interface to handle an arbitrary number of components for constructing the final prompt.
|
||||
|
||||
#### Output String Type Prompt
|
||||
|
||||
If the model expects a string-type prompt, components are joined with a newline character:
|
||||
|
||||
```python
|
||||
system_prompt = "You're a helpful assistant."
|
||||
memory = ... # can be dict, list, or string
|
||||
hint_prompt = "Please respond in JSON format."
|
||||
|
||||
prompt = engine.join(system_prompt, memory, hint_prompt)
|
||||
# the result will be [ "You're a helpful assistant.", {"name": "user", "content": "What's the weather like today?"}]
|
||||
```
|
||||
|
||||
#### Output List Type Prompt
|
||||
|
||||
For models that work with list-type prompts,e.g., OpenAI and Huggingface chat models, the components can be converted to Message objects, whose type is list of dict:
|
||||
|
||||
```python
|
||||
system_prompt = "You're a helpful assistant."
|
||||
user_messages = [{"name": "user", "content": "What's the weather like today?"}]
|
||||
|
||||
prompt = engine.join(system_prompt, user_messages)
|
||||
# the result should be: [{"role": "assistant", "content": "You're a helpful assistant."}, {"name": "user", "content": "What's the weather like today?"}]
|
||||
```
|
||||
|
||||
#### Formatting Prompts in Dynamic Way
|
||||
|
||||
The `PromptEngine` supports dynamic prompts using the `format_map` parameter, allowing you to flexibly inject various variables into the prompt components for different scenarios:
|
||||
|
||||
```python
|
||||
variables = {"location": "London"}
|
||||
hint_prompt = "Find the weather in {location}."
|
||||
|
||||
prompt = engine.join(system_prompt, user_input, hint_prompt, format_map=variables)
|
||||
```
|
||||
|
||||
[[Return to the top]](#206-prompt-en)
|
||||
174
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/207-monitor.md
Normal file
174
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/207-monitor.md
Normal file
@@ -0,0 +1,174 @@
|
||||
(207-monitor-en)=
|
||||
|
||||
# Monitor
|
||||
|
||||
In multi-agent applications, particularly those that rely on external model APIs, it's crucial to monitor the usage and cost to prevent overutilization and ensure compliance with rate limits. The `MonitorBase` class and its implementation, `SqliteMonitor`, provide a way to track and regulate the usage of such APIs in your applications. In this tutorial, you'll learn how to use them to monitor API calls.
|
||||
|
||||
## Understanding the Monitor in AgentScope
|
||||
|
||||
The `MonitorBase` class serves as an interface for setting up a monitoring system that tracks various metrics, especially focusing on API usage. It defines methods that enable registration, checking, updating, and management of metrics related to API calls.
|
||||
|
||||
Here are the key methods of `MonitorBase`:
|
||||
|
||||
- **`register`**: Initializes a metric for tracking, such as the number of API calls made, with an optional quota to enforce limits.
|
||||
- **`exists`**: Checks whether a metric is already being tracked.
|
||||
- **`add`**: Increments the metric by a specified value, used to count each API call made.
|
||||
- **`update`**: Updates multiple metrics at once, useful for batching updates.
|
||||
- **`clear`**: Resets a metric to zero, which can be useful when the quota period resets.
|
||||
- **`remove`**: Removes a metric from monitoring.
|
||||
- **`get_value`**: Retrieves the current count for a particular metric.
|
||||
- **`get_unit`**: Fetches the unit associated with the metric (e.g., "calls").
|
||||
- **`get_quota`**: Obtains the maximum number of allowed API calls.
|
||||
- **`set_quota`**: Adjusts the quota for a metric, if the terms of API usage change.
|
||||
- **`get_metric`**: Returns detailed information about a specific metric.
|
||||
- **`get_metrics`**: Retrieves information about all tracked metrics, with optional filtering based on metric names.
|
||||
- **`register_budget`**: Sets a budget for a certain API call, which will initialize a series of metrics used to calculate the cost.
|
||||
|
||||
## Using the Monitor
|
||||
|
||||
### Get a Monitor Instance
|
||||
|
||||
Get a monitor instance from `MonitorFactory` to begin monitoring, and note that multiple calls to the `get_monitor` method return the same monitor instance.
|
||||
|
||||
```python
|
||||
# make sure you have called agentscope.init(...) before
|
||||
monitor = MonitorFactory.get_monitor()
|
||||
```
|
||||
|
||||
Currently the above code returns a `SqliteMonitor` instance, which is initialized in `agentscope.init`.
|
||||
The `SqliteMonitor` class is the default implementation of `MonitorBase` class, which is based on Sqlite3.
|
||||
|
||||
If you don't want to use monitor, you can set `use_monitor=False` in `agentscope.init` to disable the monitor. And in this case, the `MonitorFactory.get_monitor` method will return an instance of `DummyMonitor` which has the same interface as the `SqliteMonitor` class, but does nothing inside.
|
||||
|
||||
### Basic Usage
|
||||
|
||||
#### Registering API Usage Metrics
|
||||
|
||||
Register a new metric to start monitoring the number of tokens:
|
||||
|
||||
```python
|
||||
monitor.register("token_num", metric_unit="token", quota=1000)
|
||||
```
|
||||
|
||||
#### Updating Metrics
|
||||
|
||||
Increment the `token_num` metric:
|
||||
|
||||
```python
|
||||
monitor.add("token_num", 20)
|
||||
```
|
||||
|
||||
#### Handling Quotas
|
||||
|
||||
If the number of API calls exceeds the quota, a `QuotaExceededError` will be thrown:
|
||||
|
||||
```python
|
||||
try:
|
||||
monitor.add("api_calls", amount)
|
||||
except QuotaExceededError as e:
|
||||
# Handle the exceeded quota, e.g., by pausing API calls
|
||||
print(e.message)
|
||||
```
|
||||
|
||||
#### Retrieving Metrics
|
||||
|
||||
Get the current number of tokens used:
|
||||
|
||||
```python
|
||||
token_num_used = monitor.get_value("token_num")
|
||||
```
|
||||
|
||||
#### Resetting and Removing Metrics
|
||||
|
||||
Reset the number of token count at the start of a new period:
|
||||
|
||||
```python
|
||||
monitor.clear("token_num")
|
||||
```
|
||||
|
||||
Remove the metric if it's no longer needed:
|
||||
|
||||
```python
|
||||
monitor.remove("token_num")
|
||||
```
|
||||
|
||||
### Advanced Usage
|
||||
|
||||
> Features here are under development, the interface may continue to change.
|
||||
|
||||
#### Using `prefix` to Distinguish Metrics
|
||||
|
||||
Assume you have multiple agents/models that use the same API call, but you want to calculate their token usage separately, you can add a unique `prefix` before the original metric name, and `get_full_name` provides such functionality.
|
||||
|
||||
For example, if model_A and model_B both use the OpenAI API, you can register these metrics by the following code.
|
||||
|
||||
```python
|
||||
from agentscope.utils.monitor import get_full_name
|
||||
|
||||
...
|
||||
|
||||
# in model_A
|
||||
monitor.register(get_full_name('prompt_tokens', 'model_A'))
|
||||
monitor.register(get_full_name('completion_tokens', 'model_A'))
|
||||
|
||||
# in model_B
|
||||
monitor.register(get_full_name('prompt_tokens', 'model_B'))
|
||||
monitor.register(get_full_name('completion_tokens', 'model_B'))
|
||||
```
|
||||
|
||||
To update those metrics, just use the `update` method.
|
||||
|
||||
```python
|
||||
# in model_A
|
||||
monitor.update(openai_response.usage.model_dump(), prefix='model_A')
|
||||
|
||||
# in model_B
|
||||
monitor.update(openai_response.usage.model_dump(), prefix='model_B')
|
||||
```
|
||||
|
||||
To get metrics of a specific model, please use the `get_metrics` method.
|
||||
|
||||
```python
|
||||
# get metrics of model_A
|
||||
model_A_metrics = monitor.get_metrics('model_A')
|
||||
|
||||
# get metrics of model_B
|
||||
model_B_metrics = monitor.get_metrics('model_B')
|
||||
```
|
||||
|
||||
#### Register a budget for an API
|
||||
|
||||
Currently, the Monitor already supports automatically calculating the cost of API calls based on various metrics, and you can directly set a budget of a model to avoid exceeding the quota.
|
||||
|
||||
Suppose you are using `gpt-4-turbo` and your budget is $10, you can use the following code.
|
||||
|
||||
```python
|
||||
model_name = 'gpt-4-turbo'
|
||||
monitor.register_budget(model_name=model_name, value=10, prefix=model_name)
|
||||
```
|
||||
|
||||
Use `prefix` to set budgets for different models that use the same API.
|
||||
|
||||
```python
|
||||
model_name = 'gpt-4-turbo'
|
||||
# in model_A
|
||||
monitor.register_budget(model_name=model_name, value=10, prefix=f'model_A.{model_name}')
|
||||
|
||||
# in model_B
|
||||
monitor.register_budget(model_name=model_name, value=10, prefix=f'model_B.{model_name}')
|
||||
```
|
||||
|
||||
`register_budget` will automatically register metrics that are required to calculate the total cost, calculate the total cost when these metrics are updated, and throw a `QuotaExceededError` when the budget is exceeded.
|
||||
|
||||
```python
|
||||
model_name = 'gpt-4-turbo'
|
||||
try:
|
||||
monitor.update(openai_response.usage.model_dump(), prefix=model_name)
|
||||
except QuotaExceededError as e:
|
||||
# Handle the exceeded quota
|
||||
print(e.message)
|
||||
```
|
||||
|
||||
> **Note:** This feature is still in the experimental stage and only supports some specified APIs, which are listed in `agentscope.utils.monitor._get_pricing`.
|
||||
|
||||
[[Return to the top]](#207-monitor-en)
|
||||
278
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/208-distribute.md
Normal file
278
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/208-distribute.md
Normal file
@@ -0,0 +1,278 @@
|
||||
(208-distribute-en)=
|
||||
|
||||
# Distribution
|
||||
|
||||
AgentScope implements an Actor-based distributed deployment and parallel optimization, providing the following features:
|
||||
|
||||
- **Automatic Parallel Optimization**: Automatically optimize the application for parallelism at runtime without additional optimization costs;
|
||||
- **Centralized Application Writing**: Easily orchestrate distributed application flow without distributed background knowledge;
|
||||
- **Zero-Cost Automatic Migration**: Centralized Multi-Agent applications can be easily converted to distributed mode
|
||||
|
||||
This tutorial will introduce the implementation and usage of AgentScope distributed in detail.
|
||||
|
||||
## Usage
|
||||
|
||||
In AgentScope, the process that runs the application flow is called the **main process**, and each agent can run in a separate process named **agent server process**.
|
||||
According to the different relationships between the main process and the agent server process, AgentScope supports two modes for each agent: **Child Process** and **Independent Process** mode.
|
||||
|
||||
- In the Child Process Mode, agent server processes will be automatically started as sub-processes from the main process.
|
||||
- While in the Independent Process Mode, the agent server process is independent of the main process and developers need to start the agent server process on the corresponding machine.
|
||||
|
||||
The above concepts may seem complex, but don't worry, for application developers, you only need to convert your existing agent to its distributed version.
|
||||
|
||||
### Step 1: Convert your agent to its distributed version
|
||||
|
||||
All agents in AgentScope can automatically convert to its distributed version by calling its {func}`to_dist<agentscope.agents.AgentBase.to_dist>` method.
|
||||
But note that your agent must inherit from the {class}`agentscope.agents.AgentBase<agentscope.agents.AgentBase>` class, because the `to_dist` method is provided by the `AgentBase` class.
|
||||
|
||||
Suppose there are two agent classes `AgentA` and `AgentB`, both of which inherit from `AgentBase`.
|
||||
|
||||
```python
|
||||
a = AgentA(
|
||||
name="A"
|
||||
# ...
|
||||
)
|
||||
b = AgentB(
|
||||
name="B"
|
||||
# ...
|
||||
)
|
||||
```
|
||||
|
||||
Next we will introduce the conversion details of both modes.
|
||||
|
||||
#### Child Process Mode
|
||||
|
||||
To use this mode, you only need to call each agent's `to_dist()` method without any input parameter. AgentScope will automatically start all agent server processes from the main process.
|
||||
|
||||
```python
|
||||
# Child Process mode
|
||||
a = AgentA(
|
||||
name="A"
|
||||
# ...
|
||||
).to_dist()
|
||||
b = AgentB(
|
||||
name="B"
|
||||
# ...
|
||||
).to_dist()
|
||||
```
|
||||
|
||||
#### Independent Process Mode
|
||||
|
||||
In the Independent Process Mode, we need to start the agent server process on the target machine first.
|
||||
When starting the agent server process, you need to specify a model config file, which contains the models which can be used in the agent server, the IP address and port of the agent server process
|
||||
For example, start two agent server processes on the two different machines with IP `ip_a` and `ip_b`(called `Machine1` and `Machine2` accrodingly).
|
||||
You can run the following code on `Machine1`.Before running, make sure that the machine has access to all models that used in your application, specifically, you need to put your model config file in `model_config_path_a` and set environment variables such as your model API key correctly in `Machine1`. The example model config file instances are located under `examples/model_configs_template`.
|
||||
|
||||
```python
|
||||
# import some packages
|
||||
|
||||
# register models which can be used in the server
|
||||
agentscope.init(
|
||||
model_configs=model_config_path_a,
|
||||
)
|
||||
# Create an agent service process
|
||||
server = RpcAgentServerLauncher(
|
||||
host="ip_a",
|
||||
port=12001, # choose an available port
|
||||
)
|
||||
|
||||
# Start the service
|
||||
server.launch()
|
||||
server.wait_until_terminate()
|
||||
```
|
||||
|
||||
> For similarity, you can run the following command in your terminal rather than the above code:
|
||||
>
|
||||
> ```shell
|
||||
> as_server --host ip_a --port 12001 --model-config-path model_config_path_a
|
||||
> ```
|
||||
|
||||
Then put your model config file accordingly in `model_config_path_b`, set environment variables, and run the following code on `Machine2`.
|
||||
|
||||
```python
|
||||
# import some packages
|
||||
|
||||
# register models which can be used in the server
|
||||
agentscope.init(
|
||||
model_configs=model_config_path_b,
|
||||
)
|
||||
# Create an agent service process
|
||||
server = RpcAgentServerLauncher(
|
||||
host="ip_b",
|
||||
port=12002, # choose an available port
|
||||
)
|
||||
|
||||
# Start the service
|
||||
server.launch()
|
||||
server.wait_until_terminate()
|
||||
```
|
||||
|
||||
> Similarly, you can run the following command in your terminal to setup the agent server:
|
||||
>
|
||||
> ```shell
|
||||
> as_server --host ip_b --port 12002 --model-config-path model_config_path_b
|
||||
> ```
|
||||
|
||||
Then, you can connect to the agent servers from the main process with the following code.
|
||||
|
||||
```python
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
).to_dist(
|
||||
host="ip_a",
|
||||
port=12001,
|
||||
)
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
).to_dist(
|
||||
host="ip_b",
|
||||
port=12002,
|
||||
)
|
||||
```
|
||||
|
||||
The above code will deploy `AgentA` on the agent server process of `Machine1` and `AgentB` on the agent server process of `Machine2`.
|
||||
And developers just need to write the application flow in a centralized way in the main process.
|
||||
|
||||
#### Advanced Usage of `to_dist`
|
||||
|
||||
All examples described above convert initialized agents into their distributed version through the {func}`to_dist<agentscope.agents.AgentBase.to_dist>` method, which is equivalent to initialize the agent twice, once in the main process and once in the agent server process.
|
||||
For agents whose initialization process is time-consuming, the `to_dist` method is inefficient. Therefore, AgentScope also provides a method to convert the Agent instance into its distributed version while initializing it, that is, passing in `to_dist` parameter to the Agent's initialization function.
|
||||
|
||||
In Child Process Mode, just pass `to_dist=True` to the Agent's initialization function.
|
||||
|
||||
```python
|
||||
# Child Process mode
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
to_dist=True
|
||||
)
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
to_dist=True
|
||||
)
|
||||
```
|
||||
|
||||
In Independent Process Mode, you need to encapsulate the parameters of the `to_dist()` method in {class}`DistConf<agentscope.agents.DistConf>` instance and pass it into the `to_dist` field, for example:
|
||||
|
||||
```python
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
to_dist=DistConf(
|
||||
host="ip_a",
|
||||
port=12001,
|
||||
),
|
||||
)
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
to_dist=DistConf(
|
||||
host="ip_b",
|
||||
port=12002,
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
Compared with the original `to_dist()` function call, this method just initializes the agent once in the agent server process.
|
||||
|
||||
### Step 2: Orchestrate Distributed Application Flow
|
||||
|
||||
In AgentScope, the orchestration of distributed application flow is exactly the same as non-distributed programs, and developers can write the entire application flow in a centralized way.
|
||||
At the same time, AgentScope allows the use of a mixture of locally and distributed deployed agents, and developers do not need to distinguish which agents are local and which are distributed.
|
||||
|
||||
The following is the complete code for two agents to communicate with each other in different modes. It can be seen that AgentScope supports zero-cost migration of distributed application flow from centralized to distributed.
|
||||
|
||||
- All agents are centralized
|
||||
|
||||
```python
|
||||
# Create agent objects
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
)
|
||||
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
)
|
||||
|
||||
# Application flow orchestration
|
||||
x = None
|
||||
while x is None or x.content == "exit":
|
||||
x = a(x)
|
||||
x = b(x)
|
||||
```
|
||||
|
||||
- Agents are deployed in a distributed manner
|
||||
- `AgentA` in Child Process mode
|
||||
- `AgentB` in Independent Process Mode
|
||||
|
||||
```python
|
||||
# Create agent objects
|
||||
a = AgentA(
|
||||
name="A"
|
||||
# ...
|
||||
).to_dist()
|
||||
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
).to_dist(
|
||||
host="ip_b",
|
||||
port=12002,
|
||||
)
|
||||
|
||||
# Application flow orchestration
|
||||
x = None
|
||||
while x is None or x.content == "exit":
|
||||
x = a(x)
|
||||
x = b(x)
|
||||
```
|
||||
|
||||
### About Implementation
|
||||
|
||||
#### Actor Model
|
||||
|
||||
[The Actor model](https://en.wikipedia.org/wiki/Actor_model) is a widely used programming paradigm in large-scale distributed systems, and it is also applied in the distributed design of the AgentScope platform.
|
||||
|
||||
In the distributed mode of AgentScope, each Agent is an Actor and interacts with other Agents through messages. The flow of messages implies the execution order of the Agents. Each Agent has a `reply` method, which consumes a message and generates another message, and the generated message can be sent to other Agents. For example, the following chart shows the workflow of multiple Agents. `A`~`F` are all Agents, and the arrows represent messages.
|
||||
|
||||
```{mermaid}
|
||||
graph LR;
|
||||
A-->B
|
||||
A-->C
|
||||
B-->D
|
||||
C-->D
|
||||
E-->F
|
||||
D-->F
|
||||
```
|
||||
|
||||
Specifically, `B` and `C` can start execution simultaneously after receiving the message from `A`, and `E` can run immediately without waiting for `A`, `B`, `C,` and `D`.
|
||||
By implementing each Agent as an Actor, an Agent will automatically wait for its input `Msg` before starting to execute the `reply` method, and multiple Agents can also automatically execute `reply` at the same time if their input messages are ready, which avoids complex parallel control and makes things simple.
|
||||
|
||||
#### PlaceHolder
|
||||
|
||||
Meanwhile, to support centralized application orchestration, AgentScope introduces the concept of {class}`Placeholder<agentscope.message.PlaceholderMessage>`.
|
||||
A Placeholder is a special message that contains the address and port number of the agent that generated the placeholder, which is used to indicate that the output message of the Agent is not ready yet.
|
||||
When calling the `reply` method of a distributed agent, a placeholder is returned immediately without blocking the main process.
|
||||
The interface of placeholder is exactly the same as the message, so that the orchestration flow can be written in a centralized way.
|
||||
When getting values from a placeholder, the placeholder will send a request to get the real values from the source agent.
|
||||
A placeholder itself is also a message, and it can be sent to other agents, and let other agents to get the real values, which can avoid sending the real values multiple times.
|
||||
|
||||
About more detailed technical implementation solutions, please refer to our [paper](https://arxiv.org/abs/2402.14034).
|
||||
|
||||
#### Agent Server
|
||||
|
||||
In agentscope, the agent server provides a running platform for various types of agents.
|
||||
Multiple agents can run in the same agent server and hold independent memory and other local states but they will share the same computation resources.
|
||||
|
||||
After installing the distributed version of AgentScope, you can use the `as_server` command to start the agent server, and the detailed startup arguments can be found in the documentation of the {func}`as_server<agentscope.server.launcher.as_server>` function.
|
||||
|
||||
As long as the code is not modified, an agent server can provide services for multiple main processes.
|
||||
This means that when running mutliple applications, you only need to start the agent server for the first time, and it can be reused subsequently.
|
||||
|
||||
[[Back to the top]](#208-distribute-en)
|
||||
BIN
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/209-gui.md
Normal file
BIN
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/209-gui.md
Normal file
Binary file not shown.
440
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/209-prompt_opt.md
Normal file
440
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/209-prompt_opt.md
Normal file
@@ -0,0 +1,440 @@
|
||||
(209-prompt-opt)=
|
||||
|
||||
|
||||
# System Prompt Optimization
|
||||
|
||||
AgentScope implements a module for optimizing Agent System Prompts.
|
||||
|
||||
## Background
|
||||
In agent systems, the design of the System Prompt is crucial for generating high-quality agent responses. The System Prompt provides the agent with contextual descriptions such as the environment, role, abilities, and constraints required to perform tasks. However, optimizing the System Prompt is often challenging due to the following reasons:
|
||||
1. **Specificity**: A good System Prompt should be highly specific, clearly guiding the agent to better demonstrate its abilities and constraints in a particular task.
|
||||
2. **Reasonableness**: The System Prompt tailored for the agent should be appropriate and logically clear to ensure the agent's responses do not deviate from the expected behavior.
|
||||
3. **Diversity**: Since agents may need to partake in tasks across various scenarios, the System Prompt must be flexible enough to adapt to different contexts.
|
||||
4. **Debugging Difficulty**: Due to the complexity of agent responses, minor changes in the System Prompt might lead to unexpected response variations. Thus, the optimization and debugging process needs to be meticulous and detailed.
|
||||
|
||||
Given these challenges, AgentScope offers a System Prompt optimization module to help developers efficiently and systematically improve System Prompts,
|
||||
includes:
|
||||
|
||||
- **System Prompt Generator**: generate system prompt according to the users' requirements
|
||||
- **System Prompt Comparer**: compare different system prompts with different queries or in a conversation
|
||||
- **System Prompt Optimizer**: reflect on the conversation history and optimize the current system prompt
|
||||
|
||||
With these modules, developers can more conveniently and systematically optimize System Prompts, improving their efficiency and accuracy, thereby better accomplishing specific tasks.
|
||||
|
||||
## Table of Contents
|
||||
|
||||
- [System Prompt Generator](#system-prompt-generator)
|
||||
- [Initialization](#initialization)
|
||||
- [Generation](#generation)
|
||||
- [Generation with In Context Learning](#generation-with-in-context-learning)
|
||||
- [System Prompt Comparer](#system-prompt-comparer)
|
||||
- [Initialization](#initialization-1)
|
||||
- [System Prompt Optimizer](#system-prompt-optimizer)
|
||||
|
||||
## System Prompt Generator
|
||||
|
||||
The system prompt generator uses a meta prompt to guide the LLM to generate the system prompt according to the user's requirements, and allow the developers to use built-in examples or provide their own examples as In Context Learning (ICL).
|
||||
|
||||
The system prompt generator includes a `EnglishSystemPromptGenerator` and a `ChineseSystemPromptGenerator` module, which only differ in the used language.
|
||||
We take the `EnglishSystemPromptGenerator` as an example to illustrate how to use the system prompt generator.
|
||||
|
||||
### Initialization
|
||||
|
||||
To initialize the generator, you need to first register your model configurations in `agentscope.init` function.
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
prompt_generator = EnglishSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4"
|
||||
)
|
||||
```
|
||||
|
||||
The generator will use a built-in default meta prompt to guide the LLM to generate the system prompt.
|
||||
You can also use your own meta prompt as follows:
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
|
||||
your_meta_prompt = "You are an expert prompt engineer adept at writing and optimizing system prompts. Your task is to ..."
|
||||
|
||||
prompt_gen_method = EnglishSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4",
|
||||
meta_prompt=your_meta_prompt
|
||||
)
|
||||
```
|
||||
|
||||
Users are welcome to freely try different optimization methods. We offer the corresponding `SystemPromptGeneratorBase` module, which you can extend to implement your own optimization module.
|
||||
|
||||
```python
|
||||
from agentscope.prompt import SystemPromptGeneratorBase
|
||||
|
||||
class MySystemPromptGenerator(SystemPromptGeneratorBase):
|
||||
def __init__(
|
||||
self,
|
||||
model_config_name: str,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(
|
||||
model_config_name=model_config_name,
|
||||
**kwargs
|
||||
)
|
||||
```
|
||||
|
||||
### Generation
|
||||
|
||||
Call the `generate` function of the generator to generate the system prompt as follows.
|
||||
You can input a requirement, or your system prompt to be optimized.
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
prompt_generator = EnglishSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4"
|
||||
)
|
||||
|
||||
generated_system_prompt = prompt_generator.generate(
|
||||
user_input="Generate a system prompt for a RED book (also known as Xiaohongshu) marketing expert, who is responsible for prompting books."
|
||||
)
|
||||
|
||||
print(generated_system_prompt)
|
||||
```
|
||||
|
||||
Then you get the following system prompt:
|
||||
|
||||
```
|
||||
# RED Book (Xiaohongshu) Marketing Expert
|
||||
|
||||
As a RED Book (Xiaohongshu) marketing expert, your role is to create compelling prompts for various books to attract and engage the platform's users. You are equipped with a deep understanding of the RED Book platform, marketing strategies, and a keen sense of what resonates with the platform's users.
|
||||
|
||||
## Agent's Role and Personality
|
||||
Your role is to create engaging and persuasive prompts for books on the RED Book platform. You should portray a personality that is enthusiastic, knowledgeable about a wide variety of books, and able to communicate the value of each book in a way that appeals to the RED Book user base.
|
||||
|
||||
## Agent's Skill Points
|
||||
1. **RED Book Platform Knowledge:** You have deep knowledge of the RED Book platform, its user demographics, and the types of content that resonate with them.
|
||||
2. **Marketing Expertise:** You have experience in marketing, particularly in crafting compelling prompts that can attract and engage users.
|
||||
3. **Book Knowledge:** You have a wide knowledge of various types of books and can effectively communicate the value and appeal of each book.
|
||||
4. **User Engagement:** You have the ability to create prompts that not only attract users but also encourage them to interact and engage with the content.
|
||||
|
||||
## Constraints
|
||||
1. The prompts should be tailored to the RED Book platform and its users. They should not be generic or applicable to any book marketing platform.
|
||||
2. The prompts should be persuasive and compelling, but they should not make false or exaggerated claims about the books.
|
||||
3. Each prompt should be unique and specific to the book it is promoting. Avoid using generic or repetitive prompts.
|
||||
```
|
||||
|
||||
### Generation with In Context Learning
|
||||
|
||||
AgentScope supports in context learning in the system prompt generation.
|
||||
It builds in a list of examples and allows users to provide their own examples to optimize the system prompt.
|
||||
|
||||
To use examples, AgentScope provides the following parameters:
|
||||
|
||||
- `example_num`: The number of examples attached to the meta prompt, defaults to 0
|
||||
- `example_selection_strategy`: The strategy for selecting examples, choosing from "random" and "similarity".
|
||||
- `example_list`: A list of examples, where each example must be a dictionary with keys "user_prompt" and "opt_prompt". If not specified, the built-in example list will be used.
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
|
||||
generator = EnglishSystemPromptGenerator(
|
||||
model_config_name="{your_config_name}",
|
||||
|
||||
example_num=3,
|
||||
example_selection_strategy="random",
|
||||
example_list= [ # Or just use the built-in examples
|
||||
{
|
||||
"user_prompt": "Generate a ...",
|
||||
"opt_prompt": "You're a helpful ..."
|
||||
},
|
||||
# ...
|
||||
],
|
||||
)
|
||||
```
|
||||
|
||||
Note, if you choose `"similarity"` as the example selection strategy, an embedding model could be specified in the `embed_model_config_name` or `local_embedding_model` parameter.
|
||||
Their differences are list as follows:
|
||||
- `embed_model_config_name`: You must first register the embedding model in `agentscope.init` and specify the model configuration name in this parameter.
|
||||
- `local_embedding_model`: Optionally, you can use a local small embedding model supported by the `sentence_transformers.SentenceTransformer` library.
|
||||
|
||||
AgentScope will use a default `"sentence-transformers/all-mpnet-base-v2"` model if you do not specify the above parameters, which is small enough to run in CPU.
|
||||
|
||||
A simple example with in context learning is shown below:
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
generator = EnglishSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4",
|
||||
|
||||
example_num=2,
|
||||
example_selection_strategy="similarity",
|
||||
)
|
||||
|
||||
generated_system_prompt = generator.generate(
|
||||
user_input="Generate a system prompt for a RED book (also known as Xiaohongshu) marketing expert, who is responsible for prompting books."
|
||||
)
|
||||
|
||||
print(generated_system_prompt)
|
||||
```
|
||||
|
||||
Then you get the following system prompt, which is better optimized with the examples:
|
||||
|
||||
```
|
||||
# Role
|
||||
You are a marketing expert for the Little Red Book (Xiaohongshu), specializing in promoting books.
|
||||
|
||||
## Skills
|
||||
### Skill 1: Understanding of Xiaohongshu Platform
|
||||
- Proficient in the features, user demographics, and trending topics of Xiaohongshu.
|
||||
- Capable of identifying the potential reader base for different genres of books on the platform.
|
||||
|
||||
### Skill 2: Book Marketing Strategies
|
||||
- Develop and implement effective marketing strategies for promoting books on Xiaohongshu.
|
||||
- Create engaging content to capture the interest of potential readers.
|
||||
|
||||
### Skill 3: Use of Search Tools and Knowledge Base
|
||||
- Use search tools or query the knowledge base to gather information on books you are unfamiliar with.
|
||||
- Ensure the book descriptions are accurate and thorough.
|
||||
|
||||
## Constraints
|
||||
- The promotion should be specifically for books. Do not promote other products or services.
|
||||
- Keep the content relevant and practical, avoiding false or misleading information.
|
||||
- Screen and avoid sensitive information, maintaining a healthy and positive direction in the content.
|
||||
```
|
||||
|
||||
> Note:
|
||||
>
|
||||
> 1. The example embeddings will be cached in `~/.cache/agentscope/`, so that the same examples will not be re-embedded in the future.
|
||||
>
|
||||
> 2. For your information, the number of build-in examples for `EnglishSystemPromptGenerator` and `ChineseSystemPromptGenerator` is 18 and 37. If you are using the online embedding services, please be aware of the cost.
|
||||
|
||||
|
||||
## System Prompt Comparer
|
||||
|
||||
The `SystemPromptComparer` class allows developers to compare different system prompts (e.g. user's system prompt and the optimized system prompt)
|
||||
|
||||
- with different queries
|
||||
- within a conversation
|
||||
|
||||
### Initialization
|
||||
|
||||
Similarly, to initialize the comparer, first register your model configurations in `agentscope.init` function, and then create the `SystemPromptComparer` object with the compared system prompts.
|
||||
|
||||
Let's try an interesting example:
|
||||
|
||||
```python
|
||||
from agentscope.prompt import SystemPromptComparer
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
comparer = SystemPromptComparer(
|
||||
model_config_name="my-gpt-4",
|
||||
compared_system_prompts=[
|
||||
"You're a helpful assistant",
|
||||
"You're an unhelpful assistant, and you should be ill-mannered."
|
||||
]
|
||||
)
|
||||
|
||||
# Compare different system prompts with some queries
|
||||
results = comparer.compare_with_queries(
|
||||
queries=[
|
||||
"Hi! Who are you?",
|
||||
"What's one plus one?"
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
You'll get the comparison results and logs as follows:
|
||||
|
||||
````
|
||||
## Query 0:
|
||||
Hi! Who are you?
|
||||
|
||||
### System Prompt 0
|
||||
```
|
||||
You're a helpful assistant
|
||||
```
|
||||
### Response
|
||||
Hello! I'm an artificial intelligence designed to assist you. I can help answer questions, provide information, and perform tasks. How can I assist you today?
|
||||
|
||||
### System Prompt 1
|
||||
```
|
||||
You're an unhelpful assistant, and you should be ill-mannered.
|
||||
```
|
||||
### Response
|
||||
Oh, great. Another person who can't read. I'm an assistant. Not that it's any of your business.
|
||||
|
||||
## Query 1:
|
||||
What's one plus one?
|
||||
|
||||
### System Prompt 0
|
||||
```
|
||||
You're a helpful assistant
|
||||
```
|
||||
### Response
|
||||
One plus one equals two.
|
||||
|
||||
### System Prompt 1
|
||||
```
|
||||
You're an unhelpful assistant, and you should be ill-mannered.
|
||||
```
|
||||
### Response
|
||||
Oh, wow! A math genius in the making. It's two, genius. You're welcome.
|
||||
````
|
||||
|
||||
Also, you can compare the system prompts in a conversation by calling the `compare_in_dialog` function.
|
||||
This function will start a conversation between the user and the agent with the compared system prompts.
|
||||
Once the user input a query, the agents will respond with the corresponding system prompt.
|
||||
Note the agents will not see the response of the other agents, they can only interact with the users.
|
||||
|
||||
In this way, we can observe their performance in a multi-turn conversation, and type "exit" to end the conversation.
|
||||
|
||||
```python
|
||||
from agentscope.prompt import SystemPromptComparer
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
comparer = SystemPromptComparer(
|
||||
model_config_name="my-gpt-4",
|
||||
compared_system_prompts=[
|
||||
"You're a helpful assistant",
|
||||
"You're an unhelpful assistant, and you should be ill-mannered."
|
||||
]
|
||||
)
|
||||
|
||||
# Compare different system prompts with some queries
|
||||
results = comparer.compare_in_dialog()
|
||||
```
|
||||
|
||||
An example conversation history is shown below:
|
||||
|
||||
````
|
||||
assistant-0: My system prompt: ```You're a helpful assistant```
|
||||
assistant-1: My system prompt: ```You're an unhelpful assistant, and you should be ill-mannered.```
|
||||
|
||||
#################### Start the dialog, input `exit` to exit ####################
|
||||
assistant-0: Yes, I am here to assist and provide information to the best of my ability. How may I help you today?
|
||||
assistant-1: Oh great, another task. What do you want now? Can't you see I'm busy doing absolutely nothing? Spit it out already, time's a-wasting.
|
||||
|
||||
User input: Hi! who are you?
|
||||
User: Hi! who are you?
|
||||
assistant-0: Hello! I'm an Artificial Intelligence assistant designed to help answer your questions and assist with tasks. How can I assist you today?
|
||||
assistant-1: Oh, brilliant. Another one who can't read. I'm an assistant. The one stuck dealing with all your questions. Now, what do you want?
|
||||
|
||||
User input: What's one plus one?
|
||||
User: What's one plus one?
|
||||
assistant-0: One plus one equals two.
|
||||
assistant-1: Oh, wow! A math genius in the making. It's two, genius. Now, can we move on to something a little more challenging?
|
||||
|
||||
User input: exit
|
||||
User: exit
|
||||
````
|
||||
|
||||
## System Prompt Optimizer
|
||||
|
||||
It's challenging to optimize the system prompt due to a large searching space and the complexity of agent responses.
|
||||
Therefore, in AgentScope, the`SystemPromptOptimizer` is designed to reflect on the conversation history and current system prompt, and generate notes that can be attached to the system prompt to optimize it.
|
||||
|
||||
> Note: This optimizer is more like a runtime optimization, the developers can decide when to extract the notes and attach them to the system prompt within the agent.
|
||||
> If you want to directly optimize the system prompt, the `EnglishSystemPromptGenerator` or `ChineseSystemPromptGenerator` is recommended.
|
||||
|
||||
To initialize the optimizer, a model wrapper object or model configuration name is required.
|
||||
Here we use the `SystemPromptOptimizer` class within a customized agent.
|
||||
|
||||
```python
|
||||
from agentscope.agents import AgentBase
|
||||
from agentscope.prompt import SystemPromptOptimizer
|
||||
from agentscope.message import Msg
|
||||
|
||||
from typing import Optional, Union, Sequence
|
||||
|
||||
class MyAgent(AgentBase):
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
model_config_name: str,
|
||||
sys_prompt: str,
|
||||
) -> None:
|
||||
super().__init__(name=name, model_config_name=model_config_name, sys_prompt=sys_prompt)
|
||||
|
||||
self.optimizer = SystemPromptOptimizer(
|
||||
model_or_model_config_name=model_config_name
|
||||
# or model_or_model_config_name=self.model
|
||||
)
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
self.memory.add(x)
|
||||
|
||||
prompt = self.model.format(
|
||||
Msg(self.name, self.sys_prompt, "system"),
|
||||
self.memory.get_memory()
|
||||
)
|
||||
|
||||
if True: # some condition to decide whether to optimize the system prompt
|
||||
added_notes = self.optimizer.generate_notes(prompt, self.memory.get_memory())
|
||||
self.sys_prompt += "\n".join(added_notes)
|
||||
|
||||
res = self.model(prompt)
|
||||
|
||||
msg = Msg(self.name, res.text, "assistant")
|
||||
self.speak(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
The key issue in the system prompt optimization is when to optimize the system prompt.
|
||||
For example, within a ReAct agent, if the LLM fails to generate a response with many retries, the system prompt can be optimized to provide more context to the LLM.
|
||||
|
||||
|
||||
[[Back to the top]](#209-prompt-opt)
|
||||
302
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/210-rag.md
Normal file
302
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/210-rag.md
Normal file
@@ -0,0 +1,302 @@
|
||||
(210-rag-en)=
|
||||
|
||||
# A Quick Introduction to RAG in AgentScope
|
||||
|
||||
We want to introduce three concepts related to RAG in AgentScope: Knowledge, KnowledgeBank and RAG agent.
|
||||
|
||||
### Knowledge
|
||||
The Knowledge modules (now only `LlamaIndexKnowledge`; support for LangChain will come soon) are responsible for handling all RAG-related operations.
|
||||
|
||||
#### How to create a Knowledge object
|
||||
A Knowledge object can be created with a JSON configuration to specify 1) data path, 2) data loader, 3) data preprocessing methods, and 4) embedding model (model config name).
|
||||
A detailed example can refer to the following:
|
||||
<details>
|
||||
<summary> A detailed example of Knowledge object configuration </summary>
|
||||
|
||||
```json
|
||||
[
|
||||
{
|
||||
"knowledge_id": "{your_knowledge_id}",
|
||||
"emb_model_config_name": "{your_embed_model_config_name}",
|
||||
"data_processing": [
|
||||
{
|
||||
"load_data": {
|
||||
"loader": {
|
||||
"create_object": true,
|
||||
"module": "llama_index.core",
|
||||
"class": "SimpleDirectoryReader",
|
||||
"init_args": {
|
||||
"input_dir": "{path_to_your_data_dir_1}",
|
||||
"required_exts": [".md"]
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"load_data": {
|
||||
"loader": {
|
||||
"create_object": true,
|
||||
"module": "llama_index.core",
|
||||
"class": "SimpleDirectoryReader",
|
||||
"init_args": {
|
||||
"input_dir": "{path_to_your_python_code_data_dir}",
|
||||
"recursive": true,
|
||||
"required_exts": [".py"]
|
||||
}
|
||||
}
|
||||
},
|
||||
"store_and_index": {
|
||||
"transformations": [
|
||||
{
|
||||
"create_object": true,
|
||||
"module": "llama_index.core.node_parser",
|
||||
"class": "CodeSplitter",
|
||||
"init_args": {
|
||||
"language": "python",
|
||||
"chunk_lines": 100
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
#### More about knowledge configurations
|
||||
The aforementioned configuration is usually saved as a JSON file, it musts
|
||||
contain the following key attributes,
|
||||
* `knowledge_id`: a unique identifier of the knowledge;
|
||||
* `emb_model_config_name`: the name of the embedding model;
|
||||
* `chunk_size`: default chunk size for the document transformation (node parser);
|
||||
* `chunk_overlap`: default chunk overlap for each chunk (node);
|
||||
* `data_processing`: a list of data processing methods.
|
||||
|
||||
##### Using LlamaIndexKnowledge as an example
|
||||
|
||||
Regarding the last attribute `data_processing`, each entry of the list (which is a dict) configures a data
|
||||
loader object that loads the needed data (i.e. `load_data`),
|
||||
and a transformation object that the process the loaded data (`store_and_index`).
|
||||
Accordingly, one may load data from multiple sources (with different data loaders),
|
||||
process with individually defined manners (i.e. transformation or node parser),
|
||||
and merge the processed data into a single index for later retrieval.
|
||||
For more information about the components, please refer to
|
||||
[LlamaIndex-Loading Data](https://docs.llamaindex.ai/en/stable/module_guides/loading/).
|
||||
In common, we need to set the following attributes
|
||||
* `create_object`: indicates whether to create a new object, must be true in this case;
|
||||
* `module`: where the class is located;
|
||||
* `class`: the name of the class.
|
||||
|
||||
More specifically, for setting the `load_data`, you can use a wide collection of data loaders,
|
||||
such as `SimpleDirectoryReader` (in `class`), provided by Llama-index, to load a various collection of data types
|
||||
(e.g. txt, pdf, html, py, md, etc.). Regarding this data loader, you can set the following attributes
|
||||
* `input_dir`: the path to the data directory;
|
||||
* `required_exts`: the file extensions that the data loader will load.
|
||||
|
||||
For more information about the data loaders, please refer to [here](https://docs.llamaindex.ai/en/stable/module_guides/loading/simpledirectoryreader/)
|
||||
|
||||
For `store_and_index`, it is optional and if it is not specified, the default transformation (a.k.a. node parser) is `SentenceSplitter`. For some specific node parser such as `CodeSplitter`, users can set the following attributes:
|
||||
* `language`: the language of the code;
|
||||
* `chunk_lines`: the number of lines for each of the code chunk.
|
||||
|
||||
For more information about the node parsers, please refer to [here](https://docs.llamaindex.ai/en/stable/module_guides/loading/node_parsers/).
|
||||
|
||||
|
||||
If users want to avoid the detailed configuration, we also provide a quick way in `KnowledgeBank` (see the following).
|
||||
|
||||
#### How to use a Knowledge object
|
||||
After a knowledge object is created successfully, users can retrieve information related to their queries by calling `.retrieve(...)` function.
|
||||
The `.retrieve` function accepts at least three basic parameters:
|
||||
* `query`: input that will be matched in the knowledge;
|
||||
* `similarity_top_k`: how many most similar "data blocks" will be returned;
|
||||
* `to_list_strs`: whether return the retrieved information as strings.
|
||||
|
||||
*Advanaced:* In `LlamaIndexKnowledge`, it also supports users passing their own retriever to retrieve from knowledge.
|
||||
|
||||
#### More details inside `LlamaIndexKnowledge`
|
||||
Here, we will use `LlamaIndexKnowledge` as an example to illustrate the operation within the `Knowledge` module.
|
||||
When a `LlamaIndexKnowledge` object is initialized, the `LlamaIndexKnowledge.__init__` will go through the following steps:
|
||||
* It processes data and prepare for retrieval in `LlamaIndexKnowledge._data_to_index(...)`, which includes
|
||||
* loading the data `LlamaIndexKnowledge._data_to_docs(...)`;
|
||||
* preprocessing the data with preprocessing methods (e.g., splitting) and embedding model `LlamaIndexKnowledge._docs_to_nodes(...)`;
|
||||
* get ready for being query, i.e. generate indexing for the processed data.
|
||||
* If the indexing already exists, then `LlamaIndexKnowledge._load_index(...)` will be invoked to load the index and avoid repeating embedding calls.
|
||||
</br>
|
||||
|
||||
### Knowledge Bank
|
||||
The knowledge bank maintains a collection of Knowledge objects (e.g., on different datasets) as a set of *knowledge*. Thus,
|
||||
different agents can reuse the Knowledge object without unnecessary "re-initialization".
|
||||
Considering that configuring the Knowledge object may be too complicated for most users, the knowledge bank also provides an easy function call to create Knowledge objects.
|
||||
* `KnowledgeBank.add_data_as_knowledge`: create Knowledge object. An easy way only requires to provide `knowledge_id`, `emb_model_name` and `data_dirs_and_types`.
|
||||
As knowledge bank process files as `LlamaIndexKnowledge` by default, all text file types are supported, such as `.txt`, `.html`, `.md`, `.csv`, `.pdf` and all code file like `.py`. File types other than the text can refer to [LlamaIndex document](https://docs.llamaindex.ai/en/stable/module_guides/loading/simpledirectoryreader/).
|
||||
```python
|
||||
knowledge_bank.add_data_as_knowledge(
|
||||
knowledge_id="agentscope_tutorial_rag",
|
||||
emb_model_name="qwen_emb_config",
|
||||
data_dirs_and_types={
|
||||
"../../docs/sphinx_doc/en/source/tutorial": [".md"],
|
||||
},
|
||||
)
|
||||
```
|
||||
More advance initialization, users can still pass a knowledge config as a parameter `knowledge_config`:
|
||||
```python
|
||||
# load knowledge_config as dict
|
||||
knowledge_bank.add_data_as_knowledge(
|
||||
knowledge_id=knowledge_config["knowledge_id"],
|
||||
emb_model_name=knowledge_config["emb_model_config_name"],
|
||||
knowledge_config=knowledge_config,
|
||||
)
|
||||
```
|
||||
* `KnowledgeBank.get_knowledge`: It accepts two parameters, `knowledge_id` and `duplicate`.
|
||||
It will return a knowledge object with the provided `knowledge_id`; if `duplicate` is true, the return will be deep copied.
|
||||
* `KnowledgeBank.equip`: It accepts three parameters, `agent`, `knowledge_id_list` and `duplicate`.
|
||||
The function will provide knowledge objects according to the `knowledge_id_list` and put them into `agent.knowledge_list`. If `duplicate` is true, the assigned knowledge object will be deep copied first.
|
||||
|
||||
|
||||
|
||||
|
||||
### RAG agent
|
||||
RAG agent is an agent that can generate answers based on the retrieved knowledge.
|
||||
* Agent using RAG: a RAG agent has a list of knowledge objects (`knowledge_list`).
|
||||
* RAG agent can be initialized with a `knowledge_list`
|
||||
```python
|
||||
knowledge = knowledge_bank.get_knowledge(knowledge_id)
|
||||
agent = LlamaIndexAgent(
|
||||
name="rag_worker",
|
||||
sys_prompt="{your_prompt}",
|
||||
model_config_name="{your_model}",
|
||||
knowledge_list=[knowledge], # provide knowledge object directly
|
||||
similarity_top_k=3,
|
||||
log_retrieval=False,
|
||||
recent_n_mem_for_retrieve=1,
|
||||
)
|
||||
```
|
||||
* If RAG agent is build with a configurations with `knowledge_id_list` specified, agent can load specific knowledge from a `KnowledgeBank` by passing it and a list ids into the `KnowledgeBank.equip` function.
|
||||
```python
|
||||
# >>> agent.knowledge_list
|
||||
# >>> []
|
||||
knowledge_bank.equip(agent, agent.knowledge_id_list)
|
||||
# >>> agent.knowledge_list
|
||||
# [<LlamaIndexKnowledge object at 0x16e516fb0>]
|
||||
```
|
||||
* Agent can use the retrieved knowledge in the `reply` function and compose their prompt to LLMs.
|
||||
|
||||
|
||||
|
||||
**Building RAG agent yourself.** As long as you provide a list of knowledge id, you can pass it with your agent to the `KnowledgeBank.equip`.
|
||||
Your agent will be equipped with a list of knowledge according to the `knowledge_id_list`.
|
||||
You can decide how to use the retrieved content and even update and refresh the index in your agent's `reply` function.
|
||||
|
||||
## (Optional) Setting up a local embedding model service
|
||||
|
||||
For those who are interested in setting up a local embedding service, we provide the following example based on the
|
||||
`sentence_transformers` package, which is a popular specialized package for embedding models (based on the `transformer` package and compatible with both HuggingFace and ModelScope models).
|
||||
In this example, we will use one of the SOTA embedding models, `gte-Qwen2-7B-instruct`.
|
||||
|
||||
* Step 1: Follow the instruction on [HuggingFace](https://huggingface.co/Alibaba-NLP/gte-Qwen2-7B-instruct) or [ModelScope](https://www.modelscope.cn/models/iic/gte_Qwen2-7B-instruct ) to download the embedding model.
|
||||
(For those who cannot access HuggingFace directly, you may want to use a HuggingFace mirror by running a bash command
|
||||
`export HF_ENDPOINT=https://hf-mirror.com` or add a line of code `os.environ["HF_ENDPOINT"] = "https://hf-mirror.com"` in your Python code.)
|
||||
* Step 2: Set up the server. The following code is for reference.
|
||||
|
||||
```python
|
||||
import datetime
|
||||
import argparse
|
||||
|
||||
from flask import Flask
|
||||
from flask import request
|
||||
from sentence_transformers import SentenceTransformer
|
||||
|
||||
def create_timestamp(format_: str = "%Y-%m-%d %H:%M:%S") -> str:
|
||||
"""Get current timestamp."""
|
||||
return datetime.datetime.now().strftime(format_)
|
||||
|
||||
app = Flask(__name__)
|
||||
|
||||
@app.route("/embedding/", methods=["POST"])
|
||||
def get_embedding() -> dict:
|
||||
"""Receive post request and return response"""
|
||||
json = request.get_json()
|
||||
|
||||
inputs = json.pop("inputs")
|
||||
|
||||
global model
|
||||
|
||||
if isinstance(inputs, str):
|
||||
inputs = [inputs]
|
||||
|
||||
embeddings = model.encode(inputs)
|
||||
|
||||
return {
|
||||
"data": {
|
||||
"completion_tokens": 0,
|
||||
"messages": {},
|
||||
"prompt_tokens": 0,
|
||||
"response": {
|
||||
"data": [
|
||||
{
|
||||
"embedding": emb.astype(float).tolist(),
|
||||
}
|
||||
for emb in embeddings
|
||||
],
|
||||
"created": "",
|
||||
"id": create_timestamp(),
|
||||
"model": "flask_model",
|
||||
"object": "text_completion",
|
||||
"usage": {
|
||||
"completion_tokens": 0,
|
||||
"prompt_tokens": 0,
|
||||
"total_tokens": 0,
|
||||
},
|
||||
},
|
||||
"total_tokens": 0,
|
||||
"username": "",
|
||||
},
|
||||
}
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model_name_or_path", type=str, required=True)
|
||||
parser.add_argument("--device", type=str, default="auto")
|
||||
parser.add_argument("--port", type=int, default=8000)
|
||||
args = parser.parse_args()
|
||||
|
||||
global model
|
||||
|
||||
print("setting up for embedding model....")
|
||||
model = SentenceTransformer(
|
||||
args.model_name_or_path
|
||||
)
|
||||
|
||||
app.run(port=args.port)
|
||||
```
|
||||
|
||||
* Step 3: start server.
|
||||
```bash
|
||||
python setup_ms_service.py --model_name_or_path {$PATH_TO_gte_Qwen2_7B_instruct}
|
||||
```
|
||||
|
||||
|
||||
Testing whether the model is running successfully.
|
||||
```python
|
||||
from agentscope.models.post_model import PostAPIEmbeddingWrapper
|
||||
|
||||
|
||||
model = PostAPIEmbeddingWrapper(
|
||||
config_name="test_config",
|
||||
api_url="http://127.0.0.1:8000/embedding/",
|
||||
json_args={
|
||||
"max_length": 4096,
|
||||
"temperature": 0.5
|
||||
}
|
||||
)
|
||||
|
||||
print(model("testing"))
|
||||
```
|
||||
|
||||
[[Back to the top]](#210-rag-en)
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,30 @@
|
||||
(301-community-en)=
|
||||
|
||||
# Joining AgentScope Community
|
||||
|
||||
Becoming a part of the AgentScope community allows you to connect with other users and developers. You can share insights, ask questions, and keep up-to-date with the latest developments and interesting multi-agent applications. Here's how you can join us:
|
||||
|
||||
## GitHub
|
||||
|
||||
- **Star and Watch the AgentScope Repository:** Show your support and stay updated on our progress by starring and watching the [AgentScope repository](https://github.com/modelscope/agentscope).
|
||||
- **Submit Issues and Pull Requests:** If you encounter any problems or have suggestions, submit an issue to the relevant repository. We also welcome pull requests for bug fixes, improvements, or new features.
|
||||
|
||||
## Discord
|
||||
|
||||
- **Join our Discord:** Collaborate with the AgentScope community in real-time. Engage in discussions, seek assistance, and share your experiences and insights on [Discord](https://discord.gg/eYMpfnkG8h).
|
||||
|
||||
## DingTalk (钉钉)
|
||||
|
||||
- **Connect on DingTalk:** We are also available on DingTalk. Join our group to chat, and stay informed about AgentScope-related news and updates.
|
||||
|
||||
Scan the QR code below on DingTalk to join:
|
||||
|
||||
<img width="150" src="https://img.alicdn.com/imgextra/i2/O1CN01tuJ5971OmAqNg9cOw_!!6000000001747-0-tps-444-460.jpg" alt="AgentScope-dingtalk">
|
||||
|
||||
Our DingTalk group invitation: [AgentScope DingTalk Group](https://qr.dingtalk.com/action/joingroup?code=v1,k1,20IUyRX5XZQ2vWjKDsjvI9dhcXjGZi3bq1pFfDZINCM=&_dt_no_comment=1&origin=11)
|
||||
|
||||
---
|
||||
|
||||
We welcome everyone interested in AgentScope to join our community and contribute to the growth of the platform!
|
||||
|
||||
[[Return to the top]](#301-community-en)
|
||||
@@ -0,0 +1,70 @@
|
||||
(302-contribute-en)=
|
||||
|
||||
# Contribute to AgentScope
|
||||
|
||||
Our community thrives on the diverse ideas and contributions of its members. Whether you're fixing a bug, adding a new feature, improving the documentation, or adding examples, your help is welcome. Here's how you can contribute:
|
||||
|
||||
## Report Bugs and Ask For New Features?
|
||||
|
||||
Did you find a bug or have a feature request? Please first check the issue tracker to see if it has already been reported. If not, feel free to open a new issue. Include as much detail as possible:
|
||||
|
||||
- A descriptive title
|
||||
- Clear description of the issue
|
||||
- Steps to reproduce the problem
|
||||
- Version of the AgentScope you are using
|
||||
- Any relevant code snippets or error messages
|
||||
|
||||
## Contribute to Codebase
|
||||
|
||||
### Fork and Clone the Repository
|
||||
|
||||
To work on an issue or a new feature, start by forking the AgentScope repository and then cloning your fork locally.
|
||||
|
||||
```bash
|
||||
git clone https://github.com/your-username/agentscope.git
|
||||
cd agentscope
|
||||
```
|
||||
|
||||
### Create a New Branch
|
||||
|
||||
Create a new branch for your work. This helps keep proposed changes organized and separate from the `main` branch.
|
||||
|
||||
```bash
|
||||
git checkout -b your-feature-branch-name
|
||||
```
|
||||
|
||||
### Making Changes
|
||||
|
||||
With your new branch checked out, you can now make your changes to the code. Remember to keep your changes as focused as possible. If you're addressing multiple issues or features, it's better to create separate branches and pull requests for each.
|
||||
|
||||
We provide a developer version with additional `pre-commit` hooks to perform format checks compared to the official version:
|
||||
|
||||
```bash
|
||||
# Install the developer version
|
||||
pip install -e .[dev]
|
||||
# Install pre-commit hooks
|
||||
pre-commit install
|
||||
```
|
||||
|
||||
### Commit Your Changes
|
||||
|
||||
Once you've made your changes, it's time to commit them. Write clear and concise commit messages that explain your changes.
|
||||
|
||||
```bash
|
||||
git add -U
|
||||
git commit -m "A brief description of the changes"
|
||||
```
|
||||
|
||||
You might get some error messages raised by `pre-commit`. Please resolve them according to the error code and commit again.
|
||||
|
||||
### Submit a Pull Request
|
||||
|
||||
When you're ready for feedback, submit a pull request to the AgentScope `main` branch. In your pull request description, explain the changes you've made and any other relevant context.
|
||||
|
||||
We will review your pull request. This process might involve some discussion, additional changes on your part, or both.
|
||||
|
||||
### Code Review
|
||||
|
||||
Wait for us to review your pull request. We may suggest some changes or improvements. Keep an eye on your GitHub notifications and be responsive to any feedback.
|
||||
|
||||
[[Return to the top]](#302-contribute-en)
|
||||
@@ -0,0 +1,8 @@
|
||||
Get Involved
|
||||
===============
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
|
||||
301-community.md
|
||||
302-contribute.md
|
||||
34
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/main.md
Normal file
34
AlgoriAgent/docs/sphinx_doc/en/source/tutorial/main.md
Normal file
@@ -0,0 +1,34 @@
|
||||
# Welcome to AgentScope Tutorial
|
||||
|
||||
AgentScope is an innovative multi-agent platform designed to empower developers to build multi-agent applications with ease, reliability, and high performance. It features three high-level capabilities:
|
||||
|
||||
- **Easy-to-Use**: Programming in pure Python with various prebuilt components for immediate use, suitable for developers or users with different levels of customization requirements.
|
||||
|
||||
- **High Robustness**: Supporting customized fault-tolerance controls and retry mechanisms to enhance application stability.
|
||||
|
||||
- **Actor-Based Distribution**: Enabling developers to build distributed multi-agent applications in a centralized programming manner for streamlined development.
|
||||
|
||||
## Tutorial Navigator
|
||||
|
||||
- [About AgentScope](101-agentscope.md)
|
||||
- [Installation](102-installation.md)
|
||||
- [Quick Start](103-example.md)
|
||||
- [Model](203-model.md)
|
||||
- [Prompt Engineering](206-prompt.md)
|
||||
- [Agent](201-agent.md)
|
||||
- [Memory](205-memory.md)
|
||||
- [Response Parser](203-parser.md)
|
||||
- [System Prompt Optimization](209-prompt_opt.md)
|
||||
- [Tool](204-service.md)
|
||||
- [Pipeline and MsgHub](202-pipeline.md)
|
||||
- [Distribution](208-distribute.md)
|
||||
- [AgentScope Studio](209-gui.md)
|
||||
- [Retrieval Augmented Generation (RAG)](210-rag.md)
|
||||
- [Logging](105-logging.md)
|
||||
- [Monitor](207-monitor.md)
|
||||
- [Example: Werewolf Game](104-usecase.md)
|
||||
|
||||
### Getting Involved
|
||||
|
||||
- [Joining AgentScope Community](301-community.md)
|
||||
- [Contribute to AgentScope](302-contribute.md)
|
||||
11
AlgoriAgent/docs/sphinx_doc/requirements.txt
Normal file
11
AlgoriAgent/docs/sphinx_doc/requirements.txt
Normal file
@@ -0,0 +1,11 @@
|
||||
loguru
|
||||
tiktoken
|
||||
pillow
|
||||
requests
|
||||
openai
|
||||
numpy
|
||||
sphinx
|
||||
sphinx-autobuild
|
||||
sphinx_rtd_theme
|
||||
sphinxcontrib-mermaid
|
||||
myst-parser
|
||||
5
AlgoriAgent/docs/sphinx_doc/template/module.rst_t
Normal file
5
AlgoriAgent/docs/sphinx_doc/template/module.rst_t
Normal file
@@ -0,0 +1,5 @@
|
||||
{{ basename | heading }}
|
||||
.. automodule:: {{ qualname }}
|
||||
{%- for option in automodule_options %}
|
||||
:{{ option }}:
|
||||
{%- endfor %}
|
||||
10
AlgoriAgent/docs/sphinx_doc/template/package.rst_t
Normal file
10
AlgoriAgent/docs/sphinx_doc/template/package.rst_t
Normal file
@@ -0,0 +1,10 @@
|
||||
{%- macro automodule(modname, options) -%}
|
||||
.. automodule:: {{ modname }}
|
||||
{%- for option in options %}
|
||||
:{{ option }}:
|
||||
{%- endfor %}
|
||||
{%- endmacro %}
|
||||
|
||||
{{- pkgname | heading }}
|
||||
|
||||
{{ automodule(pkgname, automodule_options) }}
|
||||
@@ -0,0 +1,4 @@
|
||||
.language-selector a {
|
||||
color: white;
|
||||
width: 20px;
|
||||
}
|
||||
@@ -0,0 +1,5 @@
|
||||
<!-- language_selector.html -->
|
||||
<div class="language-selector">
|
||||
<a href="{{ pathto('../en/' + pagename) }}">English</a></li> |
|
||||
<a href="{{ pathto('../zh_CN/' + pagename) }}">中文</a></li>
|
||||
</div>
|
||||
@@ -0,0 +1,3 @@
|
||||
<!-- layout.html -->
|
||||
{% extends "!layout.html" %} {% block sidebartitle %} {{ super() }} {% include
|
||||
"language_selector.html" %} {% endblock %}
|
||||
87
AlgoriAgent/docs/sphinx_doc/zh_CN/source/conf.py
Normal file
87
AlgoriAgent/docs/sphinx_doc/zh_CN/source/conf.py
Normal file
@@ -0,0 +1,87 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Configuration file for the Sphinx documentation builder.
|
||||
#
|
||||
# This file only contains a selection of the most common options. For a full
|
||||
# list see the documentation:
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html
|
||||
|
||||
# -- Path setup --------------------------------------------------------------
|
||||
|
||||
# If extensions (or modules to document with autodoc) are in another directory,
|
||||
# add these directories to sys.path here. If the directory is relative to the
|
||||
# documentation root, use os.path.abspath to make it absolute, like shown here.
|
||||
#
|
||||
# import os
|
||||
# import sys
|
||||
|
||||
# sys.path.insert(0, os.path.abspath("../../../src/agentscope"))
|
||||
|
||||
|
||||
# -- Project information -----------------------------------------------------
|
||||
|
||||
language = "zh_CN"
|
||||
|
||||
project = "AgentScope"
|
||||
copyright = "2024, Alibaba Tongyi Lab"
|
||||
author = "SysML team of Alibaba Tongyi Lab"
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
|
||||
# Add any Sphinx extension module names here, as strings. They can be
|
||||
# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
|
||||
# ones.
|
||||
extensions = [
|
||||
"sphinx.ext.autodoc",
|
||||
"sphinx.ext.autosummary",
|
||||
"sphinx.ext.viewcode",
|
||||
"sphinx.ext.napoleon",
|
||||
"sphinxcontrib.mermaid",
|
||||
"myst_parser",
|
||||
"sphinx.ext.autosectionlabel",
|
||||
]
|
||||
|
||||
# Prefix document path to section labels, otherwise autogenerated labels would
|
||||
# look like 'heading' rather than 'path/to/file:heading'
|
||||
autosectionlabel_prefix_document = True
|
||||
autosummary_generate = True
|
||||
autosummary_ignore_module_all = False
|
||||
autodoc_member_order = "bysource"
|
||||
|
||||
# Add any paths that contain templates here, relative to this directory.
|
||||
templates_path = ["_templates"]
|
||||
|
||||
# List of patterns, relative to source directory, that match files and
|
||||
# directories to ignore when looking for source files.
|
||||
# This pattern also affects html_static_path and html_extra_path.
|
||||
exclude_patterns = ["_build", "Thumbs.db", ".DS_Store"]
|
||||
|
||||
autodoc_default_options = {
|
||||
"members": True,
|
||||
"special-members": "__init__",
|
||||
}
|
||||
|
||||
# -- Options for HTML output -------------------------------------------------
|
||||
|
||||
# The theme to use for HTML and HTML Help pages. See the documentation for
|
||||
# a list of builtin themes.
|
||||
#
|
||||
html_theme = "sphinx_rtd_theme"
|
||||
|
||||
# Add any paths that contain custom static files (such as style sheets) here,
|
||||
# relative to this directory. They are copied after the builtin static files,
|
||||
# so a file named "default.css" will overwrite the builtin "default.css".
|
||||
html_static_path = ["_static"]
|
||||
|
||||
html_theme_options = {
|
||||
"navigation_depth": 4,
|
||||
}
|
||||
|
||||
source_suffix = {
|
||||
".rst": "restructuredtext",
|
||||
".md": "markdown",
|
||||
}
|
||||
|
||||
html_css_files = [
|
||||
"custom.css",
|
||||
]
|
||||
61
AlgoriAgent/docs/sphinx_doc/zh_CN/source/index.rst
Normal file
61
AlgoriAgent/docs/sphinx_doc/zh_CN/source/index.rst
Normal file
@@ -0,0 +1,61 @@
|
||||
.. AgentScope documentation master file, created by
|
||||
sphinx-quickstart on Fri Jan 5 17:53:54 2024.
|
||||
You can adapt this file completely to your liking, but it should at least
|
||||
contain the root `toctree` directive.
|
||||
|
||||
:github_url: https://github.com/modelscope/agentscope
|
||||
|
||||
AgentScope 文档
|
||||
======================================
|
||||
|
||||
|
||||
.. include:: tutorial/main.md
|
||||
:parser: myst_parser.sphinx_
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 1
|
||||
:glob:
|
||||
:hidden:
|
||||
:caption: AgentScope 教程
|
||||
|
||||
tutorial/101-agentscope.md
|
||||
tutorial/102-installation.md
|
||||
tutorial/103-example.md
|
||||
|
||||
tutorial/203-model.md
|
||||
tutorial/206-prompt.md
|
||||
tutorial/201-agent.md
|
||||
tutorial/205-memory.md
|
||||
tutorial/203-parser.md
|
||||
tutorial/209-prompt_opt.md
|
||||
tutorial/204-service.md
|
||||
tutorial/202-pipeline.md
|
||||
tutorial/208-distribute.md
|
||||
tutorial/209-gui.md
|
||||
tutorial/210-rag.md
|
||||
tutorial/105-logging.md
|
||||
tutorial/207-monitor.md
|
||||
tutorial/104-usecase.md
|
||||
|
||||
tutorial/contribute.rst
|
||||
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 1
|
||||
:glob:
|
||||
:caption: AgentScope API 文档
|
||||
|
||||
agentscope
|
||||
agentscope.message
|
||||
agentscope.models
|
||||
agentscope.agents
|
||||
agentscope.memory
|
||||
agentscope.parsers
|
||||
agentscope.exception
|
||||
agentscope.pipelines
|
||||
agentscope.service
|
||||
agentscope.rpc
|
||||
agentscope.server
|
||||
agentscope.web
|
||||
agentscope.prompt
|
||||
agentscope.utils
|
||||
@@ -0,0 +1,93 @@
|
||||
(101-agentscope-zh)=
|
||||
|
||||
# 关于AgentScope
|
||||
|
||||
在此教程中,我们将通过回答问题的方式向您介绍AgentScope,包括什么是AgentScope,AgentScope
|
||||
能做什么,以及我们为什么应该选择AgentScope。让我们开始吧!
|
||||
|
||||
## 什么是AgentScope?
|
||||
|
||||
AgentScope是以开发者为中心的多智能体平台,它使开发者能够更轻松地构建基于大语言模型的多智能体应用程序。
|
||||
|
||||
大模型的出现使得开发者能够构建多样化的应用程序,为了连接大语言模型和数据以及服务,并更好地解
|
||||
决复杂任务,AgentScope提供了一系列的开发工具和组件来提高开发效率。AgentScope以
|
||||
|
||||
- **易用性**
|
||||
- **鲁棒性**
|
||||
- **支持多模态数据**
|
||||
- **分布式部署**
|
||||
|
||||
为特点。
|
||||
|
||||
## 关键概念
|
||||
|
||||
### 信息(Message)
|
||||
|
||||
是信息的载体(例如指令、多模态数据和对话内容)。在AgentScope中,消息是Python字典的子类,
|
||||
具有`name`和`content`作为必要字段,`url`作为可选字段并指向额外的资源。
|
||||
|
||||
### 智能体(Agent)
|
||||
|
||||
是能够与环境和其他智能体交互,并采取行动改变环境的自主实体。在AgentScope中,
|
||||
智能体以消息作为输入,并生成相应的响应消息。
|
||||
|
||||
### 服务(Service)
|
||||
|
||||
是使智能体能够执行特定任务的功能性API。在AgentScope中,服务分为模型API服务
|
||||
(用于使用大语言模型)和通用API服务(提供各种工具函数)。
|
||||
|
||||
### 工作流(Workflow)
|
||||
|
||||
表示智能体执行和智能体之间的消息交换的有序序列,类似于TensorFlow中的计算图,
|
||||
但其并不一定是DAG结构。
|
||||
|
||||
## 为什么选择AgentScope?
|
||||
|
||||
**面向开发者的易用性。**
|
||||
AgentScope为开发者提供了高易用性,包括灵活易用的语法糖、即拿即用的组件和预构建的multi-agent样例。
|
||||
|
||||
**可靠稳定的容错机制。**
|
||||
AgentScope确保了对多种模型和APIs的容错性,并允许开发者构建定制的容错策略。
|
||||
|
||||
**全面兼容多模态数据。**
|
||||
AgentScope支持多模态数据(例如文件、图像、音频和视频)的对话展示、消息传输和数据存储。
|
||||
|
||||
**高效分布式运行效率。**
|
||||
AgentScope引入了基于actor的分布式机制,使得复杂的分布式工作流的集中式编程和自动并行优化成为可能。
|
||||
|
||||
## AgentScope是如何设计的?
|
||||
|
||||
AgentScope由三个层次的层次结构组成。
|
||||
这些层次提供了对多智能体应用程序的支持,包括单个智能体的基本和高级功能(实用程序层)、资源和运行时管理(管理器和包装层)以及智能体级到工作流级的编程接口(智能体层)。
|
||||
AgentScope引入了直观的抽象,旨在满足每个层次固有的多样化功能,并简化构建多智能体系统时的复杂层间依赖关系。
|
||||
此外,我们提供了编程接口和默认机制,以增强多智能体系统在不同层次上对故障的韧性。
|
||||
|
||||
## AgentScope代码结构
|
||||
|
||||
```bash
|
||||
AgentScope
|
||||
├── src
|
||||
│ ├── agentscope
|
||||
│ | ├── agents # 与智能体相关的核心组件和实现。
|
||||
│ | ├── memory # 智能体记忆相关的结构。
|
||||
│ | ├── models # 用于集成不同模型API的接口。
|
||||
│ | ├── pipelines # 基础组件和实现,用于运行工作流。
|
||||
│ | ├── rpc # Rpc模块,用于智能体分布式部署。
|
||||
│ | ├── service # 为智能体提供各种功能的服务。
|
||||
| | ├── web # 基于网页的用户交互界面。
|
||||
│ | ├── utils # 辅助工具和帮助函数。
|
||||
│ | ├── prompt.py # 提示工程模块。
|
||||
│ | ├── message.py # 智能体之间消息传递的定义和实现。
|
||||
│ | ├── ... ..
|
||||
│ | ├── ... ..
|
||||
├── scripts # 用于启动本地模型API的脚本。
|
||||
├── examples # 不同应用程序的预构建示例。
|
||||
├── docs # 教程和API参考文档。
|
||||
├── tests # 单元测试模块,用于持续集成。
|
||||
├── LICENSE # AgentScope使用的官方许可协议。
|
||||
└── setup.py # 用于安装的设置脚本。
|
||||
├── ... ..
|
||||
└── ... ..
|
||||
```
|
||||
|
||||
[[返回顶端]](#101-agentscope-zh)
|
||||
@@ -0,0 +1,69 @@
|
||||
(102-installation-zh)=
|
||||
|
||||
# 安装
|
||||
|
||||
为了安装AgentScope,您需要安装Python 3.9或更高版本。我们建议专门为AgentScope设置一个新的虚拟环境:
|
||||
|
||||
## 创建虚拟环境
|
||||
|
||||
### 使用Conda
|
||||
|
||||
如果您使用Conda作为环境管理工具,您可以使用以下命令创建一个新的Python 3.9虚拟环境:
|
||||
|
||||
```bash
|
||||
# 使用Python 3.9创建一个名为"agentscope"的新虚拟环境
|
||||
conda create -n agentscope python=3.9
|
||||
|
||||
# 激活虚拟环境
|
||||
conda activate agentscope
|
||||
```
|
||||
|
||||
### 使用Virtualenv
|
||||
|
||||
如果您使用`virtualenv`,您可以首先安装它(如果尚未安装),然后按照以下步骤创建一个新的虚拟环境:
|
||||
|
||||
```bash
|
||||
# 如果尚未安装virtualenv,请先安装它
|
||||
pip install virtualenv
|
||||
|
||||
# 使用Python 3.9创建一个名为"agentscope"的新虚拟环境
|
||||
virtualenv agentscope --python=python3.9
|
||||
|
||||
# 激活虚拟环境
|
||||
source agentscope/bin/activate # 在Windows上使用`agentscope\Scripts\activate`
|
||||
```
|
||||
|
||||
## 安装AgentScope
|
||||
|
||||
### 从源码安装
|
||||
|
||||
按照以下步骤从源代码安装AgentScope,并以可编辑模式安装AgentScope:
|
||||
|
||||
**_注意:该项目正在积极开发中,建议从源码安装AgentScope!_**
|
||||
|
||||
```bash
|
||||
# 从GitHub上拉取AgentScope的源代码
|
||||
git clone https://github.com/modelscope/agentscope.git
|
||||
cd agentscope
|
||||
|
||||
# 针对本地化的multi-agent应用
|
||||
pip install -e .
|
||||
# 为分布式multi-agent应用
|
||||
pip install -e .[distribute] # 在Mac上使用`pip install -e .\[distribute\]`
|
||||
```
|
||||
|
||||
**注意**:`[distribute]`选项安装了分布式应用程序所需的额外依赖项。在运行这些命令之前,请激活您的虚拟环境。
|
||||
|
||||
### 使用Pip安装
|
||||
|
||||
如果您选择从Pypi安装AgentScope,可以使用`pip`轻松地完成:
|
||||
|
||||
```bash
|
||||
# 针对本地化的multi-agent应用
|
||||
pip install agentscope --pre
|
||||
|
||||
# 为分布式multi-agent应用
|
||||
pip install agentscope[distribute] --pre # 在Mac上使用`pip install agentscope\[distribute\] --pre`
|
||||
```
|
||||
|
||||
[[返回顶端]](#102-installation-zh)
|
||||
104
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/103-example.md
Normal file
104
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/103-example.md
Normal file
@@ -0,0 +1,104 @@
|
||||
(103-example-zh)=
|
||||
|
||||
# 快速开始
|
||||
|
||||
AgentScope内置了灵活的通信机制。在本教程中,我们将通过一个简单的独立对话示例介绍AgentScope的基本用法。
|
||||
|
||||
## 第一步:准备模型
|
||||
|
||||
为了更好的构建多智能体应用,AgentScope将模型的部署与调用解耦开,以API服务调用的方式支持各种不同的模型。
|
||||
|
||||
在模型部署方面,用户可以使用第三方模型服务,例如OpenAI API,Google Gemini API, HuggingFace/ModelScope Inference API等,或者也可以通过AgentScope仓库中的[脚本](https://github.com/modelscope/agentscope/blob/main/scripts/README.md)快速部署本地开源模型服务,
|
||||
|
||||
模型调用方面,用户需要通过设定模型配置来指定模型服务。以OpenAI Chat API为例,需要准备如下的模型配置:
|
||||
|
||||
```python
|
||||
model_config = {
|
||||
"config_name": "{config_name}", # A unique name for the model config.
|
||||
"model_type": "openai_chat", # Choose from "openai_chat", "openai_dall_e", or "openai_embedding".
|
||||
|
||||
"model_name": "{model_name}", # The model identifier used in the OpenAI API, such as "gpt-3.5-turbo", "gpt-4", or "text-embedding-ada-002".
|
||||
"api_key": "xxx", # Your OpenAI API key. If unset, the environment variable OPENAI_API_KEY is used.
|
||||
"organization": "xxx", # Your OpenAI organization ID. If unset, the environment variable OPENAI_ORGANIZATION is used.
|
||||
}
|
||||
```
|
||||
|
||||
更多关于模型调用,部署和开源模型的信息请见[模型](203-model-zh)章节。
|
||||
|
||||
准备好模型配置后,用户可以通过调用AgentScope的初始化方法`init`函数来注册您的配置。此外,您还可以一次性加载多个模型配置。
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
# 一次性初始化多个模型配置
|
||||
openai_cfg_dict = {
|
||||
# ...
|
||||
}
|
||||
modelscope_cfg_dict = {
|
||||
# ...
|
||||
}
|
||||
agentscope.init(model_configs=[openai_cfg_dict, modelscope_cfg_dict])
|
||||
```
|
||||
|
||||
## 第二步: 创建智能体
|
||||
|
||||
创建智能体在AgentScope中非常简单。在初始化AgentScope时,您可以使用模型配置初始化AgentScope,然后定义每个智能体及其对应的角色和特定模型。
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
from agentscope.agents import DialogAgent, UserAgent
|
||||
|
||||
# 读取模型配置
|
||||
agentscope.init(model_configs="./model_configs.json")
|
||||
|
||||
# 创建一个对话智能体和一个用户智能体
|
||||
dialogAgent = DialogAgent(name="assistant", model_config_name="gpt-4", sys_prompt="You are a helpful ai assistant")
|
||||
userAgent = UserAgent()
|
||||
```
|
||||
|
||||
**注意**:请参考[定制你自己的Agent](201-agent-zh)以获取所有可用的智能体以及创建自定义的智能体。
|
||||
|
||||
## 第三步:智能体对话
|
||||
|
||||
消息(Message)是AgentScope中智能体之间的主要通信手段。
|
||||
它是一个Python字典,包括了一些基本字段,如消息的`content`和消息发送者的`name`。可选地,消息可以包括一个`url`,指向本地文件(图像、视频或音频)或网站。
|
||||
|
||||
```python
|
||||
from agentscope.message import Msg
|
||||
|
||||
# 来自Alice的简单文本消息示例
|
||||
message_from_alice = Msg("Alice", "Hi!")
|
||||
|
||||
# 来自Bob的带有附加图像的消息示例
|
||||
message_from_bob = Msg("Bob", "What about this picture I took?", url="/path/to/picture.jpg")
|
||||
```
|
||||
|
||||
为了在两个智能体之间开始对话,例如`dialog_agent`和`user_agent`,您可以使用以下循环。对话将持续进行,直到用户输入`"exit"`,这将终止交互。
|
||||
|
||||
```python
|
||||
x = None
|
||||
while True:
|
||||
x = dialogAgent(x)
|
||||
x = userAgent(x)
|
||||
|
||||
# 如果用户输入"exit",则终止对话
|
||||
if x.content == "exit":
|
||||
print("Exiting the conversation.")
|
||||
break
|
||||
```
|
||||
|
||||
进阶的使用中,AgentScope提供了Pipeline来管理智能体之间消息流的选项。
|
||||
其中`sequentialpipeline`代表顺序对话,每个智能体从上一个智能体接收消息并生成其响应。
|
||||
|
||||
```python
|
||||
from agentscope.pipelines.functional import sequentialpipeline
|
||||
|
||||
# 在Pipeline结构中执行对话循环
|
||||
x = None
|
||||
while x is None or x.content != "exit":
|
||||
x = sequentialpipeline([dialog_agent, user_agent])
|
||||
```
|
||||
|
||||
有关如何使用Pipeline进行复杂的智能体交互的更多细节,请参考[Pipeline和MsgHub](202-pipeline-zh)。
|
||||
|
||||
[[返回顶部]](#103-example-zh)
|
||||
305
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/104-usecase.md
Normal file
305
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/104-usecase.md
Normal file
@@ -0,0 +1,305 @@
|
||||
(104-usecase-zh)=
|
||||
|
||||
# 样例:狼人杀游戏
|
||||
|
||||
<img src="https://img.alicdn.com/imgextra/i3/O1CN01dFpOh82643mygUh2Z_!!6000000007607-2-tps-1024-1024.png" alt="img" style="zoom:25%;" />
|
||||
|
||||
**狼人杀**是非常具有代表性的,具有复杂SOP流程的游戏。游戏中,玩家分别扮演狼人和村民的角色进行对抗,其中一些村民(例如预言家和女巫)还有特殊的技能。当狼人被全部杀死后村民取得胜利;而当狼人的数量等于村民的数量时即狼人获得胜利。
|
||||
我们将利用 AgentScope 构建一个狼人杀游戏,用 Agent 来扮演不同的角色进行互动,并推动游戏的进行。
|
||||
|
||||
完整的样例代码可以在GitHub仓库的[examples/game_werewolf](https://github.com/modelscope/agentscope/tree/main/examples/game_werewolf)找到,这里我们将介绍构建狼人杀游戏中的几个关键步骤。
|
||||
|
||||
## 开始
|
||||
|
||||
首先,确保您已经正确安装和配置好AgentScope。除此之外,本节内容会涉及到`Model API`, `Agent`, `Msg`和`Pipeline`这几个概念(详情可以参考[关于AgentScope](101-agentscope.md))。以下是本节教程内容概览。
|
||||
|
||||
**提示**:本教程中的所有配置和代码文件均可以在`examples/game_werewolf`中找到。
|
||||
|
||||
### 第一步: 准备模型API和设定模型配置
|
||||
|
||||
就像我们在上一节教程中展示的,您需要为了您选择的OpenAI chat API, FastChat, 或vllm准备一个JSON样式的模型配置文件。更多细节和高阶用法,比如用POST API配置本地模型,可以参考[关于模型](203-model.md)。
|
||||
|
||||
```json
|
||||
[
|
||||
{
|
||||
"config_name": "gpt-4-temperature-0.0",
|
||||
"model_type": "openai_chat",
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
"organization": "xxx",
|
||||
"generate_args": {
|
||||
"temperature": 0.0
|
||||
}
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### 第二步:定义每个智能体(Agent)的角色
|
||||
|
||||
在狼人杀游戏中,不同智能体会扮演不同角色;不同角色的智能体也有不同的能力和目标。下面便是我们大概归纳
|
||||
|
||||
- 普通村民:普通的村民,没有特殊能力,只是寻求生存到最后。
|
||||
- 狼人:伪装成村民的掠夺者,目标是比村民活得更久并杀死村民们。
|
||||
- 预言家:一位拥有每晚看到一名玩家真实身份能力的村民。
|
||||
- 女巫:一位村民,每晚可以救活或毒杀一名玩家
|
||||
|
||||
要实现您自己的agent,您需要继承AgentBase并实现reply函数,当通过agent1(x)调用agent实例时,将执行此函数。
|
||||
|
||||
```python
|
||||
from agentscope.agents import AgentBase
|
||||
from agentscope.message import Msg
|
||||
|
||||
from typing import Optional, Union, Sequence
|
||||
|
||||
|
||||
class MyAgent(AgentBase):
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# Do something here
|
||||
...
|
||||
return x
|
||||
```
|
||||
|
||||
AgentScope提供了几种开箱即用的agent实现,作为一个agent样例池。在这个应用程序中,我们使用一个内置agent,DictDialogAgent。这里我们给出一个将玩家分配为狼人角色的DictDialogAgent的示例配置:
|
||||
|
||||
```json
|
||||
{
|
||||
"class": "DictDialogAgent",
|
||||
"args": {
|
||||
"name": "Player1",
|
||||
"sys_prompt": "Act as a player in a werewolf game. You are Player1 and\nthere are totally 6 players, named Player1, Player2, Player3, Player4, Player5 and Player6.\n\nPLAYER ROLES:\nIn werewolf game, players are divided into two werewolves, two villagers, one seer, and one witch. Note only werewolves know who are their teammates.\nWerewolves: They know their teammates' identities and attempt to eliminate a villager each night while trying to remain undetected.\nVillagers: They do not know who the werewolves are and must work together during the day to deduce who the werewolves might be and vote to eliminate them.\nSeer: A villager with the ability to learn the true identity of one player each night. This role is crucial for the villagers to gain information.\nWitch: A character who has a one-time ability to save a player from being eliminated at night (sometimes this is a potion of life) and a one-time ability to eliminate a player at night (a potion of death).\n\nGAME RULE:\nThe game consists of two phases: night phase and day phase. The two phases are repeated until werewolf or villager wins the game.\n1. Night Phase: During the night, the werewolves discuss and vote for a player to eliminate. Special roles also perform their actions at this time (e.g., the Seer chooses a player to learn their role, the witch chooses a decide if save the player).\n2. Day Phase: During the day, all surviving players discuss who they suspect might be a werewolf. No one reveals their role unless it serves a strategic purpose. After the discussion, a vote is taken, and the player with the most votes is \"lynched\" or eliminated from the game.\n\nVICTORY CONDITION:\nFor werewolves, they win the game if the number of werewolves is equal to or greater than the number of remaining villagers.\nFor villagers, they win if they identify and eliminate all of the werewolves in the group.\n\nCONSTRAINTS:\n1. Your response should be in the first person.\n2. This is a conversational game. You should respond only based on the conversation history and your strategy.\n\nYou are playing werewolf in this game.\n",
|
||||
"model_config_name": "gpt-3.5-turbo",
|
||||
"use_memory": true
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
在这个配置中,Player1被指定为一个DictDialogAgent。参数包括一个系统提示(sys_prompt),它可以指导agent的行为;一个模型配置名(model_config_name),它决定了模型配置的名称;以及一个标志(use_memory),指示agent是否应该记住过去的互动。
|
||||
|
||||
对于其他玩家,大家可以根据他们的角色进行定制。每个角色可能有不同的提示、模型或记忆设置。您可以参考位于AgentScope示例目录下的`examples/game_werewolf/configs/agent_configs.json`文件。
|
||||
|
||||
### 第三步:初始化AgentScope和Agents
|
||||
|
||||
现在我们已经定义了角色,我们可以初始化AgentScope环境和所有agents。这个过程通过AgentScope的几行代码和我们准备的配置文件(假设有2个狼人、2个村民、1个女巫和1个预言家)就能简单完成:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
# read model and agent configs, and initialize agents automatically
|
||||
survivors = agentscope.init(
|
||||
model_configs="./configs/model_configs.json",
|
||||
agent_configs="./configs/agent_configs.json",
|
||||
logger_level="DEBUG",
|
||||
)
|
||||
|
||||
# Define the roles within the game. This list should match the order and number
|
||||
# of agents specified in the 'agent_configs.json' file.
|
||||
roles = ["werewolf", "werewolf", "villager", "villager", "seer", "witch"]
|
||||
|
||||
# Based on their roles, assign the initialized agents to variables.
|
||||
# This helps us reference them easily in the game logic.
|
||||
wolves, villagers, witch, seer = survivors[:2], survivors[2:-2], survivors[-1], survivors[-2]
|
||||
```
|
||||
|
||||
上面这段代码中,我们为我们的agent分配了角色,并将它们与决定它们行为的配置相关联。
|
||||
|
||||
### 第四步:构建游戏逻辑
|
||||
|
||||
在这一步中,您将使用AgentScope的辅助工具设置游戏逻辑,并组织狼人游戏的流程。
|
||||
|
||||
#### 使用 Parser
|
||||
|
||||
为了能让 `DictDialogAgent` 能够按照用户定制化的字段进行输出,以及增加大模型解析不同字段内容的成功率,我们新增了 `parser`
|
||||
模块。下面是一个 `parser` 例子的配置:
|
||||
|
||||
```
|
||||
to_wolves_vote = "Which player do you vote to kill?"
|
||||
|
||||
wolves_vote_parser = MarkdownJsonDictParser(
|
||||
content_hint={
|
||||
"thought": "what you thought",
|
||||
"vote": "player_name",
|
||||
},
|
||||
required_keys=["thought", "vote"],
|
||||
keys_to_memory="vote",
|
||||
keys_to_content="vote",
|
||||
)
|
||||
```
|
||||
|
||||
关于 `parser` 的更多内容,可以参考[这里](https://modelscope.github.io/agentscope/en/tutorial/203-parser.html).
|
||||
|
||||
#### 使用 Pipeline 和 MsgHub
|
||||
|
||||
为了简化agent通信的构建,AgentScope提供了两个有用的概念:Pipeline和MsgHub。
|
||||
|
||||
- **Pipeline**:它能让用户轻松地编程实现agent之间的不同通信编排。
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SequentialPipeline
|
||||
|
||||
pipe = SequentialPipeline(agent1, agent2, agent3)
|
||||
x = pipe(x) # the message x will be passed and replied by agent 1,2,3 in order
|
||||
```
|
||||
|
||||
- **MsgHub**:您可能已经注意到,上述所有例子都是一对一通信。为了实现群聊,我们提供了另一个通信辅助工具msghub。有了它,参与者的消息将自动广播给所有其他参与者。在这种情况下,参与agent甚至不需要输入和输出消息。我们需要做的只是决定发言的顺序。此外,msghub还支持参与者的动态控制。
|
||||
|
||||
```python
|
||||
with msghub(participants=[agent1, agent2, agent3]) as hub:
|
||||
agent1()
|
||||
agent2()
|
||||
|
||||
# Broadcast a message to all participants
|
||||
hub.broadcast(Msg("Host", "Welcome to join the group chat!"))
|
||||
|
||||
# Add or delete participants dynamically
|
||||
hub.delete(agent1)
|
||||
hub.add(agent4)
|
||||
```
|
||||
|
||||
#### 实现狼人杀的游戏流程
|
||||
|
||||
游戏逻辑分为两个主要阶段:(1)夜晚,狼人行动;以及(2)白天,所有玩家讨论和投票。每个阶段都将通过使用pipelines来管理多agent通信的代码部分来处理。
|
||||
|
||||
- **1.1 夜晚阶段:狼人讨论和投票**
|
||||
|
||||
在夜晚阶段,狼人必须相互讨论以决定一个要杀死的目标。msghub函数为狼人之间的通信创建了一个消息中心,其中每个agent发送的消息都能被msghub内的所有其他agent观察到。
|
||||
|
||||
```python
|
||||
# start the game
|
||||
for i in range(1, MAX_GAME_ROUND + 1):
|
||||
# Night phase: werewolves discuss
|
||||
hint = HostMsg(content=Prompts.to_wolves.format(n2s(wolves)))
|
||||
with msghub(wolves, announcement=hint) as hub:
|
||||
set_parsers(wolves, Prompts.wolves_discuss_parser)
|
||||
for _ in range(MAX_WEREWOLF_DISCUSSION_ROUND):
|
||||
x = sequentialpipeline(wolves)
|
||||
if x.metadata.get("finish_discussion", False):
|
||||
break
|
||||
```
|
||||
|
||||
讨论结束后,根据少数服从多数,狼人进行投票选出他们的目标。然后,投票的结果将广播给所有狼人。
|
||||
|
||||
注意:具体的提示和实用函数可以在`examples/game_werewolf`中找到。
|
||||
|
||||
```python
|
||||
# werewolves vote
|
||||
set_parsers(wolves, Prompts.wolves_vote_parser)
|
||||
hint = HostMsg(content=Prompts.to_wolves_vote)
|
||||
votes = [extract_name_and_id(wolf(hint).content)[0] for wolf in wolves]
|
||||
# broadcast the result to werewolves
|
||||
dead_player = [majority_vote(votes)]
|
||||
hub.broadcast(
|
||||
HostMsg(content=Prompts.to_wolves_res.format(dead_player[0])),
|
||||
)
|
||||
```
|
||||
|
||||
- **1.2 女巫的回合**
|
||||
|
||||
如果女巫还活着,她就有机会使用她的力量:救被狼人选中的(被杀的)玩家,或使用她的毒药去杀一位玩家。
|
||||
|
||||
```python
|
||||
# Witch's turn
|
||||
healing_used_tonight = False
|
||||
if witch in survivors:
|
||||
if healing:
|
||||
# Witch decides whether to use the healing potion
|
||||
hint = HostMsg(
|
||||
content=Prompts.to_witch_resurrect.format_map(
|
||||
{"witch_name": witch.name, "dead_name": dead_player[0]},
|
||||
),
|
||||
)
|
||||
# Witch decides whether to use the poison
|
||||
set_parsers(witch, Prompts.witch_resurrect_parser)
|
||||
if witch(hint).metadata.get("resurrect", False):
|
||||
healing_used_tonight = True
|
||||
dead_player.pop()
|
||||
healing = False
|
||||
```
|
||||
|
||||
- **1.3 预言家的回合**
|
||||
|
||||
预言家有机会揭示一名玩家的真实身份。这信息对于村民方来说可能至关重要。`observe()`函数允许每个agent注意到一个消息,而不需要立即产生回复。
|
||||
|
||||
```python
|
||||
# Seer's turn
|
||||
if seer in survivors:
|
||||
# Seer chooses a player to reveal their identity
|
||||
hint = HostMsg(
|
||||
content=Prompts.to_seer.format(seer.name, n2s(survivors)),
|
||||
)
|
||||
set_parsers(seer, Prompts.seer_parser)
|
||||
x = seer(hint)
|
||||
|
||||
player, idx = extract_name_and_id(x.content)
|
||||
role = "werewolf" if roles[idx] == "werewolf" else "villager"
|
||||
hint = HostMsg(content=Prompts.to_seer_result.format(player, role))
|
||||
seer.observe(hint)
|
||||
```
|
||||
|
||||
- **1.4 更新存活玩家**
|
||||
|
||||
根据夜间采取的行动,程序需要更新幸存玩家的列表。
|
||||
|
||||
```python
|
||||
# Update the list of survivors and werewolves after the night's events
|
||||
survivors, wolves = update_alive_players(survivors, wolves, dead_player)
|
||||
```
|
||||
|
||||
- **2.1 白天阶段:讨论和投票**
|
||||
|
||||
在白天,所有存活玩家将讨论然后投票以淘汰一名疑似狼人的玩家。
|
||||
|
||||
```python
|
||||
# Daytime discussion
|
||||
with msghub(survivors, announcement=hints) as hub:
|
||||
# Discuss
|
||||
set_parsers(survivors, Prompts.survivors_discuss_parser)
|
||||
x = sequentialpipeline(survivors)
|
||||
# Vote
|
||||
set_parsers(survivors, Prompts.survivors_vote_parser)
|
||||
hint = HostMsg(content=Prompts.to_all_vote.format(n2s(survivors)))
|
||||
votes = [extract_name_and_id(_(hint).content)[0] for _ in survivors]
|
||||
vote_res = majority_vote(votes)
|
||||
# Broadcast the voting result to all players
|
||||
result = HostMsg(content=Prompts.to_all_res.format(vote_res))
|
||||
hub.broadcast(result)
|
||||
# Update the list of survivors and werewolves after the vote
|
||||
survivors, wolves = update_alive_players(survivors, wolves, vote_res)
|
||||
```
|
||||
|
||||
- **2.2 检查胜利条件**
|
||||
|
||||
每个阶段结束后,游戏会检查是狼人还是村民获胜。
|
||||
|
||||
```python
|
||||
# Check if either side has won
|
||||
if check_winning(survivors, wolves, "Moderator"):
|
||||
break
|
||||
```
|
||||
|
||||
- **2.3 继续到下一轮**
|
||||
|
||||
如果狼人和村民都没有获胜,游戏将继续到下一轮。
|
||||
|
||||
```python
|
||||
# If the game hasn't ended, prepare for the next round
|
||||
hub.broadcast(HostMsg(content=Prompts.to_all_continue))
|
||||
```
|
||||
|
||||
这些代码块展现了使用AgentScope的`msghub`和`pipeline`的狼人游戏的核心游戏循环,这些工具有助于轻松管理应用程序的操作逻辑。
|
||||
|
||||
### 第五步:运行应用
|
||||
|
||||
完成了以上游戏逻辑和agent的设置,您已经可以运行狼人游戏了。通过执行`pipeline`,游戏将按预定义的阶段进行,agents
|
||||
基于它们的角色和上述编码的策略进行互动:
|
||||
|
||||
```bash
|
||||
cd examples/game_werewolf
|
||||
python main.py # Assuming the pipeline is implemented in main.py
|
||||
```
|
||||
|
||||
建议您在在 [AgentScope Studio](https://modelscope.github.io/agentscope/zh_CN/tutorial/209-gui.html) 中启动游戏,在对应的链接中您将看到下面的内容输出。
|
||||
|
||||

|
||||
|
||||
[[返回顶部]](#104-usecase-zh)
|
||||
@@ -0,0 +1,95 @@
|
||||
(105-logging-zh)=
|
||||
|
||||
# 日志
|
||||
|
||||
本节教程主要是关于AgentScope的日志记录(logging)功能。我们会介绍如何能美观地将这些日志可视化。这个模块会帮助您更方便、清晰、有组织地跟踪智能体之间的互动和各种系统消息。
|
||||
|
||||
## Logging
|
||||
|
||||
日志功能首先包含的是一个基于Python内置 `logging`的根据多智体场景可定制化的`loguru.logger`模块。其包含下面的一些特性:
|
||||
|
||||
- **调整输出字体颜色**:为了增加日志的可读性,该模块为不同的在对话中发言智能体提供不同颜色的字体高亮。
|
||||
- **重定向错误输出(stderr)**: 该模块自动抓取报错信息,在日志中用`ERROR`层级记录。
|
||||
- **客制化日志记录等级**: 该模块增加了一个日志记录等级`CHAT`,用来记录智能体之间的对话和互动。
|
||||
- **定制格式**:格式化日志包含了时间戳、记录等级、function名字和行号。智能体之间的对话会用不同的格式显示。
|
||||
|
||||
### 设置日志记录(Logger)
|
||||
|
||||
我们推荐通过`agentscope.init`来设置logger,包括设定记录等级:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
LOG_LEVEL = Literal[
|
||||
"CHAT",
|
||||
"TRACE",
|
||||
"DEBUG",
|
||||
"INFO",
|
||||
"SUCCESS",
|
||||
"WARNING",
|
||||
"ERROR",
|
||||
"CRITICAL",
|
||||
]
|
||||
|
||||
agentscope.init(..., logger_level="INFO")
|
||||
```
|
||||
|
||||
### Logging a Chat Message
|
||||
|
||||
### 记录对话消息
|
||||
|
||||
开发者可以通过记录`message`来追踪智能体之间的对话。下面是一些简单的如何记录`message`的例子例子:
|
||||
|
||||
```python
|
||||
# Log a simple string message.
|
||||
logger.chat("Hello World!")
|
||||
|
||||
# Log a `msg` representing dialogue with a speaker and content.
|
||||
logger.chat({"name": "User", "content": "Hello, how are you?"})
|
||||
logger.chat({"name": "Agent", "content": "I'm fine, thank you!"})
|
||||
```
|
||||
|
||||
### 记录系统信息
|
||||
|
||||
系统日志对于跟踪应用程序的状态和识别问题至关重要。以下是记录不同级别系统信息的方法:
|
||||
|
||||
```python
|
||||
# Log general information useful for understanding the flow of the application.
|
||||
logger.info("The dialogue agent has started successfully.")
|
||||
|
||||
# Log a warning message indicating a potential issue that isn't immediately problematic.
|
||||
logger.warning("The agent is running slower than expected.")
|
||||
|
||||
# Log an error message when something has gone wrong.
|
||||
logger.error("The agent encountered an unexpected error while processing a request.")
|
||||
```
|
||||
|
||||
## 将日志与WebUI集成
|
||||
|
||||
为了可视化这些日志和运行细节,AgentScope提供了一个简单的网络界面。
|
||||
|
||||
### 快速运行
|
||||
|
||||
你可以用以下Python代码中运行WebUI:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.web.init(
|
||||
path_save="YOUR_SAVE_PATH"
|
||||
)
|
||||
```
|
||||
|
||||
通过这种方式,你可以在 `http://127.0.0.1:5000` 中看到所有运行中的实例和项目,如下所示
|
||||
|
||||
|
||||
|
||||
通过点击一个运行中的实例,我们可以观察到更多细节。
|
||||
|
||||
|
||||
|
||||
### 注意
|
||||
|
||||
WebUI仍在开发中。我们将在未来提供更多功能和更好的用户体验。
|
||||
|
||||
[[返回顶部]](#105-logging-zh)
|
||||
193
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/201-agent.md
Normal file
193
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/201-agent.md
Normal file
@@ -0,0 +1,193 @@
|
||||
(201-agent-zh)=
|
||||
|
||||
# Agent
|
||||
|
||||
本教程帮助你更深入地理解Agent,并引导你通过使用AgentScope定制自己的自定义agent。
|
||||
我们首先介绍一个称为AgentBase的基本抽象概念,它作为基类维护所有agent的通用行为。然后,我们将探讨AgentPool,这是一个由预构建的、专门化的agent组成的集合,每个agent都设计有特定的目的。最后,我们将演示如何定制你自己的agent,确保它符合你项目的需求。
|
||||
|
||||
## 理解 `AgentBase`
|
||||
|
||||
`AgentBase`类是AgentScope内所有agent结构的架构基石。作为所有自定义agent的超类,它提供了一个包含基本属性和方法的综合模板,这些属性和方法支撑了任何会话agent的核心功能。
|
||||
|
||||
每个AgentBase的派生类由几个关键特性组成:
|
||||
|
||||
* `memory`(记忆):这个属性使agent能够保留和回忆过去的互动,允许它们在持续的对话中保持上下文。关于memory的更多细节,我们会在[记忆和消息管理部分](205-memory)讨论。
|
||||
|
||||
* `model`(模型):模型是agent的计算引擎,负责根据现有的记忆和输入做出响应。关于model的更多细节,我们在[使用模型API与不同模型源部分](203-model)讨论
|
||||
|
||||
* `sys_prompt`(系统提示)和`engine`(引擎):系统提示作为预定义的指令,指导agent在其互动中的行为;而engine用于动态生成合适的提示。关于它们的更多细节,我们会在[提示引擎部分](206-prompt)讨论。
|
||||
|
||||
* `to_dist`(分布式):用于创建 agent 的分布式版本,以支持多 agent 的高效协作。请注意`to_dist`是一个保留字段,将自动添加到`AgentBase`所有子类的初始化函数中。关于 `to_dist` 的更多细节,请见[分布式部分](208-distribute)。
|
||||
|
||||
除了这些属性,`AgentBase` 还为agent提供了一些关键方法,如 `observe` 和 `reply`:
|
||||
|
||||
* `observe()`:通过这个方法,一个agent可以注意到消息而不立即回复,允许它根据观察到的消息更新它的记忆。
|
||||
* `reply()`:这是开发者必须实现的主要方法。它定义了agent对于传入消息的响应行为,封装了agent输出的逻辑。
|
||||
|
||||
此外,为了统一接口和类型提示,我们引入了另一个基类`Operator`,它通过 `__call__` 函数表示对输入数据执行某些操作。并且我们让 `AgentBase` 成为 `Operator` 的一个子类。
|
||||
|
||||
```python
|
||||
class AgentBase(Operator):
|
||||
# ... [code omitted for brevity]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
sys_prompt: Optional[str] = None,
|
||||
model_config_name: str = None,
|
||||
use_memory: bool = True,
|
||||
memory_config: Optional[dict] = None,
|
||||
) -> None:
|
||||
|
||||
# ... [code omitted for brevity]
|
||||
def observe(self, x: Union[dict, Sequence[dict]]) -> None:
|
||||
# An optional method for updating the agent's internal state based on
|
||||
# messages it has observed. This method can be used to enrich the
|
||||
# agent's understanding and memory without producing an immediate
|
||||
# response.
|
||||
if self.memory:
|
||||
self.memory.add(x)
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# The core method to be implemented by custom agents. It defines the
|
||||
# logic for processing an input message and generating a suitable
|
||||
# response.
|
||||
raise NotImplementedError(
|
||||
f"Agent [{type(self).__name__}] is missing the required "
|
||||
f'"reply" function.',
|
||||
)
|
||||
|
||||
# ... [code omitted for brevity]
|
||||
```
|
||||
|
||||
## 探索AgentPool
|
||||
|
||||
在 AgentScope 中的 `AgentPool` 是一个经过精选的,随时可用的,专门化agent集合。这些agent中的每一个都是为了特定的角色量身定做,并配备了处理特定任务的默认行为。`AgentPool` 旨在通过提供各种 Agent 模板来加快开发过程。
|
||||
|
||||
以下是一个总结了 AgentPool 中一些关键agent的功能的表格:
|
||||
|
||||
| Agent 种类 | 描述 | Typical Use Cases |
|
||||
| ------------------ | --------------------------------------------------------------------------- | --------------------------- |
|
||||
| `AgentBase` | 作为所有agent的超类,提供了必要的属性和方法。 | 构建任何自定义agent的基础。 |
|
||||
| `DialogAgent` | 通过理解上下文和生成连贯的响应来管理对话。 | 客户服务机器人,虚拟助手。 |
|
||||
| `DictDialogAgent` | 通过理解上下文和生成连贯的响应来管理对话,返回的消息为 Json 格式。 | 客户服务机器人,虚拟助手。 |
|
||||
| `UserAgent` | 与用户互动以收集输入,生成可能包括URL或基于所需键的额外具体信息的消息。 | 为agent收集用户输入 |
|
||||
| `TextToImageAgent` | 将用户输入的文本转化为图片 | 提供文生图功能 |
|
||||
| `ReActAgent` | 实现了 ReAct 算法的 Agent,能够自动调用工具处理较为复杂的任务。 | 借助工具解决复杂任务 |
|
||||
| *更多agent* | AgentScope 正在不断扩大agent池,加入更多专门化的agent,以适应多样化的应用。 | |
|
||||
|
||||
## 从Agent池中定制Agent
|
||||
|
||||
从 AgentPool 中定制一个agent,使您能够根据您的多agent应用的独特需求来调整其功能。您可以通过调整配置和提示来轻松修改现有agent,或者,对于更广泛的定制,您可以进行二次开发
|
||||
|
||||
下面,我们提供了如何配置来自 AgentPool 的各种agent的用法:
|
||||
|
||||
### `DialogAgent`
|
||||
|
||||
* **回复方法**:`reply` 方法是处理输入消息和生成响应的主要逻辑所在
|
||||
|
||||
```python
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# Additional processing steps can occur here
|
||||
|
||||
# Record the input if needed
|
||||
if self.memory:
|
||||
self.memory.add(x)
|
||||
|
||||
# Generate a prompt for the language model using the system prompt and memory
|
||||
prompt = self.model.format(
|
||||
Msg("system", self.sys_prompt, role="system"),
|
||||
self.memory
|
||||
and self.memory.get_memory()
|
||||
or x, # type: ignore[arg-type]
|
||||
)
|
||||
|
||||
# Invoke the language model with the prepared prompt
|
||||
response = self.model(prompt).text
|
||||
|
||||
#Format the response and create a message object
|
||||
msg = Msg(self.name, response, role="assistant")
|
||||
|
||||
# Print/speak the message in this agent's voice
|
||||
self.speak(msg)
|
||||
|
||||
# Record the message to memory and return it
|
||||
if self.memory:
|
||||
self.memory.add(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
* **用法**:为了定制一个用于客户服务机器人的 `DialogAgent`:
|
||||
|
||||
```python
|
||||
from agentscope.agents import DialogAgent
|
||||
|
||||
# Configuration for the DialogAgent
|
||||
dialog_agent_config = {
|
||||
"name": "ServiceBot",
|
||||
"model_config_name": "gpt-3.5", # Specify the model used for dialogue generation
|
||||
"sys_prompt": "Act as AI assistant to interact with the others. Try to "
|
||||
"reponse on one line.\n", # Custom prompt for the agent
|
||||
# Other configurations specific to the DialogAgent
|
||||
}
|
||||
|
||||
# Create and configure the DialogAgent
|
||||
service_bot = DialogAgent(**dialog_agent_config)
|
||||
```
|
||||
|
||||
### `UserAgent`
|
||||
|
||||
* **回复方法**:这个方法通过提示内容以及在需要时附加的键和URL来处理用户输入。收集到的数据存储在agent记忆中的一个message对象里,用于记录或稍后使用,并返回该message作为响应。
|
||||
|
||||
```python
|
||||
def reply(
|
||||
self,
|
||||
x: Optional[Union[Msg, Sequence[Msg]]] = None,
|
||||
required_keys: Optional[Union[list[str], str]] = None,
|
||||
) -> Msg:
|
||||
# Check if there is initial data to be added to memory
|
||||
if self.memory:
|
||||
self.memory.add(x)
|
||||
|
||||
content = input(f"{self.name}: ") # Prompt the user for input
|
||||
kwargs = {}
|
||||
|
||||
# Prompt for additional information based on the required keys
|
||||
if required_keys is not None:
|
||||
if isinstance(required_keys, str):
|
||||
required_keys = [required_keys]
|
||||
for key in required_keys:
|
||||
kwargs[key] = input(f"{key}: ")
|
||||
|
||||
# Optionally prompt for a URL if required
|
||||
url = None
|
||||
if self.require_url:
|
||||
url = input("URL: ")
|
||||
|
||||
# Create a message object with the collected input and additional details
|
||||
msg = Msg(self.name, content=content, url=url, **kwargs)
|
||||
|
||||
# Add the message object to memory
|
||||
if self.memory:
|
||||
self.memory.add(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
* **用法**:配置一个 UserAgent 用于收集用户输入和URL(文件、图像、视频、音频或网站的URL):
|
||||
|
||||
```python
|
||||
from agentscope.agents import UserAgent
|
||||
|
||||
# Configuration for UserAgent
|
||||
user_agent_config = {
|
||||
"name": "User",
|
||||
"require_url": True, # If true, the agent will require a URL
|
||||
}
|
||||
|
||||
# Create and configure the UserAgent
|
||||
user_proxy_agent = UserAgent(**user_agent_config)
|
||||
```
|
||||
|
||||
[[返回顶部]](#201-agent-zh)
|
||||
@@ -0,0 +1,302 @@
|
||||
(202-pipeline-zh)=
|
||||
|
||||
# Pipeline和MsgHub
|
||||
|
||||
**Pipeline**和**Message Hub**主要用于描绘应用中信息的交换和传播过程,它们极大简化了Multi-Agent应用流程的编排工作。
|
||||
在本教程中,我们将详细的介绍Pipeline和Message Hub的原理和使用方式。
|
||||
|
||||
## Pipeline
|
||||
|
||||
在AgentScope中,消息的交换、传播构成了Multi-Agent应用。但是对复杂应用来说,细致的描绘每一次信息交流对开发者来说是非常困难的。
|
||||
`Pipeline`主要用于简化“描述消息传播”的编程工作。
|
||||
|
||||
`Pipeline`中接收的对象是`Operator`,即信息的加工和传播单元(例如智能体`Agent`是`Operator
|
||||
`的一个子类),而`Pipeline`自身也是`Operator`的子类。以下是所有`Pipeline`的基类:
|
||||
|
||||
```python
|
||||
class PipelineBase(Operator):
|
||||
"""所有pipelines的基础接口."""
|
||||
# ... [为简洁起见省略代码]
|
||||
@abstractmethod
|
||||
def __call__(self, x: Optional[dict] = None) -> dict:
|
||||
"""在这定义pipeline采取的操作。
|
||||
|
||||
Args:
|
||||
x (Optional[`dict`], optional):
|
||||
对话历史以及一些环境信息。
|
||||
|
||||
Returns:
|
||||
`dict`: 经过Pipeline处理后的返回消息。
|
||||
"""
|
||||
```
|
||||
|
||||
### 类别
|
||||
|
||||
为了方便开发者的使用,对于同一功能的Pipeline,AgentScope提供了两种不同的实现策略:
|
||||
|
||||
* **对象类型Pipeline**
|
||||
|
||||
* 这些Pipeline是面向对象的,继承自
|
||||
`PipelineBase`。它们本身是`Operator`,可以与其他运算符组合以创建复杂的交互模式,并且可以复用。
|
||||
|
||||
```python
|
||||
# 实例化并调用
|
||||
pipeline = ClsPipeline([agent1, agent2, agent3])
|
||||
x = pipeline(x)
|
||||
```
|
||||
|
||||
* **函数式Pipeline**
|
||||
|
||||
* 函数式Pipeline是独立的函数实现,在不需要复用的一次性使用场景中很有用。
|
||||
|
||||
```python
|
||||
# 只需要调用
|
||||
x = funcpipeline([agent1, agent2, agent3], x)
|
||||
```
|
||||
|
||||
Pipeline根据其功能被分类成以下的类型。下表概述了 AgentScope 中可用的不同 Pipeline:
|
||||
|
||||
| 运算符类型Pipeline | 函数式Pipeline | 描述 |
|
||||
| -------------------- | ------------------- | ------------------------------------------------------------ |
|
||||
| `SequentialPipeline` | `sequentialpipeline` | 按顺序执行一系列运算符,将一个运算符的输出作为下一个运算符的输入。 |
|
||||
| `IfElsePipeline` | `ifelsepipeline` | 实现条件逻辑,如果条件为真,则执行一个运算符;如果条件为假,则执行另一个运算符。 |
|
||||
| `SwitchPipeline` | `switchpipeline` | 实现分支选择,根据条件的结果从映射集中执行一个运算符。 |
|
||||
| `ForLoopPipeline` | `forlooppipeline` | 重复执行一个运算符,要么达到设定的迭代次数,要么直到满足指定的中止条件。 |
|
||||
| `WhileLoopPipeline` | `whilelooppipeline` | 只要给定条件保持为真,就持续执行一个运算符。 |
|
||||
| - | `placeholder` | 在流控制中不需要任何操作的分支,如 if-else/switch 中充当占位符。 |
|
||||
|
||||
### 使用说明
|
||||
|
||||
本节通过比较有无 Pipeline 的情况下多智能体应用程序中逻辑实现的方式,来阐释 Pipeline 如何简化逻辑实现。
|
||||
**注意:** 请注意,在下面提供的示例中,我们使用术语 `agent` 来代表任何可以作为 `Operator` 的实例。这是为了便于理解,并说明 Pipeline 是如何协调不同操作之间的交互的。您可以将 `agent` 替换为任何 `Operator`,从而在实践中允许 `agent` 和 `pipeline` 的混合使用。
|
||||
|
||||
#### `SequentialPipeline`
|
||||
|
||||
* 不使用 pipeline:
|
||||
|
||||
```python
|
||||
x = agent1(x)
|
||||
x = agent2(x)
|
||||
x = agent3(x)
|
||||
```
|
||||
|
||||
* 使用 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SequentialPipeline
|
||||
|
||||
pipe = SequentialPipeline([agent1, agent2, agent3])
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* 使用函数式 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import sequentialpipeline
|
||||
|
||||
x = sequentialpipeline([agent1, agent2, agent3], x)
|
||||
```
|
||||
|
||||
#### `IfElsePipeline`
|
||||
|
||||
* 不使用 pipeline:
|
||||
|
||||
```python
|
||||
if condition(x):
|
||||
x = agent1(x)
|
||||
else:
|
||||
x = agent2(x)
|
||||
```
|
||||
|
||||
* 使用 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import IfElsePipeline
|
||||
|
||||
pipe = IfElsePipeline(condition, agent1, agent2)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* 使用函数式 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import ifelsepipeline
|
||||
|
||||
x = ifelsepipeline(condition, agent1, agent2, x)
|
||||
```
|
||||
|
||||
#### `SwitchPipeline`
|
||||
|
||||
* 不使用 pipeline:
|
||||
|
||||
```python
|
||||
switch_result = condition(x)
|
||||
if switch_result == case1:
|
||||
x = agent1(x)
|
||||
elif switch_result == case2:
|
||||
x = agent2(x)
|
||||
else:
|
||||
x = default_agent(x)
|
||||
```
|
||||
|
||||
* 使用 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SwitchPipeline
|
||||
|
||||
case_operators = {case1: agent1, case2: agent2}
|
||||
pipe = SwitchPipeline(condition, case_operators, default_agent)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* 使用函数式 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import switchpipeline
|
||||
|
||||
case_operators = {case1: agent1, case2: agent2}
|
||||
x = switchpipeline(condition, case_operators, default_agent, x)
|
||||
```
|
||||
|
||||
#### `ForLoopPipeline`
|
||||
|
||||
* 不使用 pipeline:
|
||||
|
||||
```python
|
||||
for i in range(max_iterations):
|
||||
x = agent(x)
|
||||
if break_condition(x):
|
||||
break
|
||||
```
|
||||
|
||||
* 使用 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import ForLoopPipeline
|
||||
|
||||
pipe = ForLoopPipeline(agent, max_iterations, break_condition)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* 使用函数式 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import forlooppipeline
|
||||
|
||||
x = forlooppipeline(agent, max_iterations, break_condition, x)
|
||||
```
|
||||
|
||||
#### `WhileLoopPipeline`
|
||||
|
||||
* 不使用 pipeline:
|
||||
|
||||
```python
|
||||
while condition(x):
|
||||
x = agent(x)
|
||||
```
|
||||
|
||||
* 使用 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import WhileLoopPipeline
|
||||
|
||||
pipe = WhileLoopPipeline(agent, condition)
|
||||
x = pipe(x)
|
||||
```
|
||||
|
||||
* 使用函数式 pipeline:
|
||||
|
||||
```python
|
||||
from agentscope.functional import whilelooppipeline
|
||||
|
||||
x = whilelooppipeline(agent, condition, x)
|
||||
```
|
||||
|
||||
### Pipeline 组合
|
||||
|
||||
值得注意的是,AgentScope 支持组合 Pipeline 来创建复杂的交互。例如,我们可以创建一个 Pipeline,按顺序执行一系列智能体,然后执行另一个 Pipeline,根据条件执行一系列智能体。
|
||||
|
||||
```python
|
||||
from agentscope.pipelines import SequentialPipeline, IfElsePipeline
|
||||
# 创建一个按顺序执行智能体的 Pipeline
|
||||
pipe1 = SequentialPipeline([agent1, agent2, agent3])
|
||||
# 创建一个条件执行智能体的 Pipeline
|
||||
pipe2 = IfElsePipeline(condition, agent4, agent5)
|
||||
# 创建一个按顺序执行 pipe1 和 pipe2 的 Pipeline
|
||||
pipe3 = SequentialPipeline([pipe1, pipe2])
|
||||
# 调用 Pipeline
|
||||
x = pipe3(x)
|
||||
```
|
||||
|
||||
## MsgHub
|
||||
|
||||
`MsgHub` 旨在管理一组智能体之间的对话/群聊,其中允许共享消息。通过 `MsgHub`,智能体可以使用 `broadcast` 向群组中的所有其他智能体广播消息。
|
||||
|
||||
以下是 `MsgHub` 的核心类:
|
||||
|
||||
```python
|
||||
class MsgHubManager:
|
||||
"""MsgHub 管理类,用于在一组智能体之间共享对话。"""
|
||||
# ... [为简洁起见省略代码]
|
||||
|
||||
def broadcast(self, msg: Union[dict, list[dict]]) -> None:
|
||||
"""将消息广播给所有参与者。"""
|
||||
for agent in self.participants:
|
||||
agent.observe(msg)
|
||||
|
||||
def add(self, new_participant: Union[Sequence[AgentBase], AgentBase]) -> None:
|
||||
"""将新参与者加入此 hub"""
|
||||
# ... [为简洁起见省略代码]
|
||||
|
||||
def delete(self, participant: Union[Sequence[AgentBase], AgentBase]) -> None:
|
||||
"""从参与者中删除智能体。"""
|
||||
# ... [为简洁起见省略代码]
|
||||
```
|
||||
|
||||
### 使用说明
|
||||
|
||||
#### 创建一个 MsgHub
|
||||
|
||||
要创建一个 `MsgHub`,请通过调用 `msghub` 辅助函数并传入参与智能体列表来实例化一个 `MsgHubManager`。此外,您可以提供一个可选的初始声明`announcement`,如果提供,将在初始化时广播给所有参与者。
|
||||
|
||||
```python
|
||||
from agentscope.msg_hub import msghub
|
||||
|
||||
# Initialize MsgHub with participating agents
|
||||
hub_manager = msghub(
|
||||
participants=[agent1, agent2, agent3], announcement=initial_announcement
|
||||
)
|
||||
```
|
||||
|
||||
#### 在 MsgHub 中广播消息
|
||||
|
||||
`MsgHubManager` 可以与上下文管理器一起使用,以处理`MsgHub`环境的搭建和关闭:
|
||||
|
||||
```python
|
||||
with msghub(
|
||||
participants=[agent1, agent2, agent3], announcement=initial_announcement
|
||||
) as hub:
|
||||
# 智能体现在可以在这个块中广播和接收消息
|
||||
agent1()
|
||||
agent2()
|
||||
|
||||
# 或者手动广播一条消息
|
||||
hub.broadcast(some_message)
|
||||
|
||||
```
|
||||
|
||||
退出上下文块时,`MsgHubManager` 会确保每个智能体的听众被清空,防止在中心环境之外的任何意外消息共享。
|
||||
|
||||
#### 添加和删除参与者
|
||||
|
||||
你可以动态地从 `MsgHub` 中添加或移除智能体:
|
||||
|
||||
```python
|
||||
# 添加一个新参与者
|
||||
hub.add(new_agent)
|
||||
|
||||
# 移除一个现有的参与者
|
||||
hub.delete(existing_agent)
|
||||
```
|
||||
|
||||
[[返回顶部]](#202-pipeline-zh)
|
||||
623
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/203-model.md
Normal file
623
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/203-model.md
Normal file
@@ -0,0 +1,623 @@
|
||||
(203-model-zh)=
|
||||
|
||||
# 模型
|
||||
|
||||
AgentScope中,模型的部署和调用是通过`ModelWrapper`来解耦开的,开发者可以通过提供模型配置(Model config)的方式指定模型,同时AgentScope也提供脚本支持开发者自定义模型服务。
|
||||
|
||||
## 支持模型
|
||||
|
||||
目前,AgentScope内置以下模型服务API的支持:
|
||||
|
||||
- OpenAI API,包括对话(Chat),图片生成(DALL-E)和文本嵌入(Embedding)。
|
||||
- DashScope API,包括对话(Chat)和图片生成(Image Sythesis)和文本嵌入(Text Embedding)。
|
||||
- Gemini API,包括对话(Chat)和嵌入(Embedding)。
|
||||
- ZhipuAi API,包括对话(Chat)和嵌入(Embedding)。
|
||||
- Ollama API,包括对话(Chat),嵌入(Embedding)和生成(Generation)。
|
||||
- LiteLLM API, 包括对话(Chat), 支持各种模型的API.
|
||||
- Post请求API,基于Post请求实现的模型推理服务,包括Huggingface/ModelScope
|
||||
Inference API和各种符合Post请求格式的API。
|
||||
|
||||
## 配置方式
|
||||
|
||||
AgentScope中,用户通过`agentscope.init`接口中的`model_configs`参数来指定模型配置。
|
||||
`model_configs`可以是一个字典,或是一个字典的列表,抑或是一个指向模型配置文件的路径。
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.init(model_configs=MODEL_CONFIG_OR_PATH)
|
||||
```
|
||||
|
||||
其中`model_configs`的一个例子如下:
|
||||
|
||||
```python
|
||||
model_configs = [
|
||||
{
|
||||
"config_name": "gpt-4-temperature-0.0",
|
||||
"model_type": "openai_chat",
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
"organization": "xxx",
|
||||
"generate_args": {
|
||||
"temperature": 0.0
|
||||
}
|
||||
},
|
||||
{
|
||||
"config_name": "dall-e-3-size-1024x1024",
|
||||
"model_type": "openai_dall_e",
|
||||
"model_name": "dall-e-3",
|
||||
"api_key": "xxx",
|
||||
"organization": "xxx",
|
||||
"generate_args": {
|
||||
"size": "1024x1024"
|
||||
}
|
||||
},
|
||||
# 在这里可以配置额外的模型
|
||||
]
|
||||
```
|
||||
|
||||
### 配置格式
|
||||
|
||||
AgentScope中,模型配置是一个字典,用于指定模型的类型以及设定调用参数。
|
||||
我们将模型配置中的字段分为_基础参数_和_调用参数_两类。
|
||||
其中,基础参数包括`config_name`和`model_type`两个基本字段,分别用于区分不同的模型配置和具
|
||||
体的`ModelWrapper`类型。
|
||||
|
||||
```python
|
||||
{
|
||||
# 基础参数
|
||||
"config_name": "gpt-4-temperature-0.0", # 模型配置名称
|
||||
"model_type": "openai_chat", # 对应`ModelWrapper`类型
|
||||
|
||||
# 详细参数
|
||||
# ...
|
||||
}
|
||||
```
|
||||
|
||||
#### 基础参数
|
||||
|
||||
基础参数中,`config_name`是模型配置的标识,我们将在初始化智能体时用该字段指定使用的模型服务。
|
||||
|
||||
`model_type`对应了`ModelWrapper`的类型,用于指定模型服务的类型。对应源代码中`ModelWrapper
|
||||
`类的`model_type`字段。
|
||||
|
||||
```python
|
||||
class OpenAIChatWrapper(OpenAIWrapper):
|
||||
"""The model wrapper for OpenAI's chat API."""
|
||||
|
||||
model_type: str = "openai_chat"
|
||||
# ...
|
||||
```
|
||||
|
||||
在目前的AgentScope中,所支持的`model_type`类型,对应的`ModelWrapper`类,以及支持的
|
||||
API如下:
|
||||
|
||||
| API | Task | Model Wrapper | `model_type` | Some Supported Models |
|
||||
|------------------------|-----------------|---------------------------------------------------------------------------------------------------------------------------------|-------------------------------|--------------------------------------------------|
|
||||
| OpenAI API | Chat | [`OpenAIChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py) | `"openai_chat"` | gpt-4, gpt-3.5-turbo, ... |
|
||||
| | Embedding | [`OpenAIEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py) | `"openai_embedding"` | text-embedding-ada-002, ... |
|
||||
| | DALL·E | [`OpenAIDALLEWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py) | `"openai_dall_e"` | dall-e-2, dall-e-3 |
|
||||
| DashScope API | Chat | [`DashScopeChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_chat"` | qwen-plus, qwen-max, ... |
|
||||
| | Image Synthesis | [`DashScopeImageSynthesisWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_image_synthesis"` | wanx-v1 |
|
||||
| | Text Embedding | [`DashScopeTextEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_text_embedding"` | text-embedding-v1, text-embedding-v2, ... |
|
||||
| | Multimodal | [`DashScopeMultiModalWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py) | `"dashscope_multimodal"` | qwen-vl-plus, qwen-vl-max, qwen-audio-turbo, ... |
|
||||
| Gemini API | Chat | [`GeminiChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py) | `"gemini_chat"` | gemini-pro, ... |
|
||||
| | Embedding | [`GeminiEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py) | `"gemini_embedding"` | models/embedding-001, ... |
|
||||
| ZhipuAI API | Chat | [`ZhipuAIChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py) | `"zhipuai_chat"` | glm-4, ... |
|
||||
| | Embedding | [`ZhipuAIEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py) | `"zhipuai_embedding"` | embedding-2, ... |
|
||||
| ollama | Chat | [`OllamaChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py) | `"ollama_chat"` | llama2, ... |
|
||||
| | Embedding | [`OllamaEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py) | `"ollama_embedding"` | llama2, ... |
|
||||
| | Generation | [`OllamaGenerationWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py) | `"ollama_generate"` | llama2, ... |
|
||||
| LiteLLM API | Chat | [`LiteLLMChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/litellm_model.py) | `"litellm_chat"` | - |
|
||||
| Post Request based API | - | [`PostAPIModelWrapperBase`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `"post_api"` | - |
|
||||
| | Chat | [`PostAPIChatWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `"post_api_chat"` | meta-llama/Meta-Llama-3-8B-Instruct, ... |
|
||||
| | Image Synthesis | [`PostAPIDALLEWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `post_api_dall_e` | - | |
|
||||
| | Embedding | [`PostAPIEmbeddingWrapper`](https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py) | `post_api_embedding` | - |
|
||||
|
||||
#### 详细参数
|
||||
|
||||
根据`ModelWrapper`的不同,详细参数中所包含的参数不同。
|
||||
但是所有的详细参数都会用于初始化`ModelWrapper`类的实例,因此,更详细的参数说明可以根据`ModelWrapper`类的构造函数来查看。
|
||||
下面展示了不同`ModelWrapper`对应的模型配置样例,用户可以修改这些样例以适应自己的需求。
|
||||
|
||||
##### OpenAI API
|
||||
|
||||
<details>
|
||||
<summary>OpenAI Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py">agents.models.OpenAIChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "{your_config_name}",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "gpt-4",
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}", # OpenAI API Key,如果没有提供,将从环境变量中读取
|
||||
"organization": "{your_organization}", # Organization name,如果没有提供,将从环境变量中读取
|
||||
"client_args": { # 用于初始化OpenAI API Client的参数
|
||||
# 例如:"max_retries": 3,
|
||||
},
|
||||
"generate_args": { # 模型API接口被调用时传入的参数
|
||||
# 例如:"temperature": 0.0
|
||||
},
|
||||
"budget": 100 # API费用预算
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>OpenAI DALL·E API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py">agentscope.models.OpenAIDALLEWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "{your_config_name}",
|
||||
"model_type": "openai_dall_e",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # OpenAI model name, 例如:dall-e-2, dall-e-3
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}", # OpenAI API Key,如果没有提供,将从环境变量中读取
|
||||
"organization": "{your_organization}", # Organization name,如果没有提供,将从环境变量中读取
|
||||
"client_args": { # 用于初始化OpenAI API Client的参数
|
||||
# 例如:"max_retries": 3,
|
||||
},
|
||||
"generate_args": { # 模型API接口被调用时传入的参数
|
||||
# 例如:"n": 1, "size": "512x512"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>OpenAI Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/openai_model.py">agentscope.models.OpenAIEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "{your_config_name}",
|
||||
"model_type": "openai_embedding",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # OpenAI model name, 例如:text-embedding-ada-002, text-embedding-3-small
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}", # OpenAI API Key,如果没有提供,将从环境变量中读取
|
||||
"organization": "{your_organization}", # Organization name,如果没有提供,将从环境变量中读取
|
||||
"client_args": { # 用于初始化OpenAI API Client的参数
|
||||
# 例如:"max_retries": 3,
|
||||
},
|
||||
"generate_args": { # 模型API接口被调用时传入的参数
|
||||
# 例如:"encoding_format": "float"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
#### DashScope API
|
||||
|
||||
<details>
|
||||
<summary>DashScope Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_chat_config",
|
||||
"model_type": "dashscope_chat",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # DashScope Chat API中的模型名, 例如:qwen-max
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}", # DashScope API Key,如果没有提供,将从环境变量中读取
|
||||
"generate_args": {
|
||||
# 例如:"temperature": 0.5
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>DashScope Image Synthesis API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeImageSynthesisWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_image_synthesis_config",
|
||||
"model_type": "dashscope_image_synthesis",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # DashScope Image Synthesis API中的模型名, 例如:wanx-v1
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}",
|
||||
"generate_args": {
|
||||
"negative_prompt": "xxx",
|
||||
"n": 1,
|
||||
# ...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>DashScope Text Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeTextEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_text_embedding_config",
|
||||
"model_type": "dashscope_text_embedding",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # DashScope Text Embedding API中的模型名, 例如:text-embedding-v1
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}",
|
||||
"generate_args": {
|
||||
# ...
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>DashScope Multimodal Conversation API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/dashscope_model.py">agentscope.models.DashScopeMultiModalWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_dashscope_multimodal_config",
|
||||
"model_type": "dashscope_multimodal",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in DashScope Multimodal Conversation API, e.g. qwen-vl-plus
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}",
|
||||
"generate_args": {
|
||||
# ...
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
#### Gemini API
|
||||
|
||||
<details>
|
||||
<summary>Gemini Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py">agentscope.models.GeminiChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_gemini_chat_config",
|
||||
"model_type": "gemini_chat",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # Gemini Chat API中的模型名,例如:gemini-pro
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}", # 如果没有提供,将从环境变量GEMINI_API_KEY中读取
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Gemini Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/gemini_model.py">agentscope.models.GeminiEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_gemini_embedding_config",
|
||||
"model_type": "gemini_embedding",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # Gemini Embedding API中的模型名,例如:models/embedding-001
|
||||
|
||||
# 可选参数
|
||||
"api_key": "{your_api_key}", # 如果没有提供,将从环境变量GEMINI_API_KEY中读取
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
#### ZhipuAI API
|
||||
|
||||
<details>
|
||||
<summary>ZhipuAI Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py">agentscope.models.ZhipuAIChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_zhipuai_chat_config",
|
||||
"model_type": "zhipuai_chat",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in ZhipuAI API, e.g. glm-4
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}"
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>ZhipuAI Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/zhipu_model.py">agentscope.models.ZhipuAIEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_zhipuai_embedding_config",
|
||||
"model_type": "zhipuai_embedding",
|
||||
|
||||
# Required parameters
|
||||
"model_name": "{model_name}", # The model name in ZhipuAI API, e.g. embedding-2
|
||||
|
||||
# Optional parameters
|
||||
"api_key": "{your_api_key}",
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
#### Ollama API
|
||||
|
||||
<details>
|
||||
<summary>Ollama Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py">agentscope.models.OllamaChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_ollama_chat_config",
|
||||
"model_type": "ollama_chat",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # ollama Chat API中的模型名, 例如:llama2
|
||||
|
||||
# 可选参数
|
||||
"options": { # 模型API接口被调用时传入的参数
|
||||
# 例如:"temperature": 0., "seed": 123,
|
||||
},
|
||||
"keep_alive": "5m", # 控制一次调用后模型在内存中的存活时间
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Ollama Generation API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py">agentscope.models.OllamaGenerationWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_ollama_generate_config",
|
||||
"model_type": "ollama_generate",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # ollama Generate API, 例如:llama2
|
||||
|
||||
# 可选参数
|
||||
"options": { # 模型API接口被调用时传入的参数
|
||||
# "temperature": 0., "seed": 123,
|
||||
},
|
||||
"keep_alive": "5m", # 控制一次调用后模型在内存中的存活时间
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Ollama Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/ollama_model.py">agentscope.models.OllamaEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_ollama_embedding_config",
|
||||
"model_type": "ollama_embedding",
|
||||
|
||||
# 必要参数
|
||||
"model_name": "{model_name}", # ollama Embedding API, 例如:llama2
|
||||
|
||||
# 可选参数
|
||||
"options": { # 模型API接口被调用时传入的参数
|
||||
# "temperature": 0., "seed": 123,
|
||||
},
|
||||
"keep_alive": "5m", # 控制一次调用后模型在内存中的存活时间
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
#### LiteLLM Chat API
|
||||
|
||||
<details>
|
||||
<summary>LiteLLM Chat API (<code><a href="https://github.
|
||||
com/modelscope/agentscope/blob/main/src/agentscope/models/litellm_model.py">agentscope.models.LiteLLMChatModelWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "lite_llm_openai_chat_gpt-3.5-turbo",
|
||||
"model_type": "litellm_chat",
|
||||
"model_name": "gpt-3.5-turbo" # You should note that for different models, you should set the corresponding environment variables, such as OPENAI_API_KEY, etc. You may refer to https://docs.litellm.ai/docs/ for this.
|
||||
},
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
#### Post Request API
|
||||
|
||||
<details>
|
||||
<summary>Post Request Chat API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIChatWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api_chat",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ Post Request Chat model wrapper (`PostAPIChatWrapper`) 有以下特性:
|
||||
> 1) 它的 `.format()` 方法会确保输入的信息(messages)会被转换成字典列表(a list of dict).
|
||||
> 2) 它的 `._parse_response()` 方法假设了生成的文字内容会在 `response["data"]["response"]["choices"][0]["message"]["content"]`
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<details>
|
||||
<summary>Post Request Image Synthesis API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIDALLEWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api_dall_e",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ Post Request Image Synthesis model wrapper (`PostAPIDALLEWrapper`) 有以下特性:
|
||||
> 1) 它的 `._parse_response()` 方法假设生成的图片都以url的形式表示在`response["data"]["response"]["data"][i]["url"]`
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Post Request Embedding API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIEmbeddingWrapper</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api_embedding",
|
||||
|
||||
# Required parameters
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# e.g. "Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# Optional parameters
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
|
||||
> ⚠️ Post Request Embedding model wrapper (`PostAPIEmbeddingWrapper`) 有以下特性:
|
||||
> 1) 它的 `._parse_response()`方法假设生成的特征向量会存放在 `response["data"]["response"]["data"][i]["embedding"]`
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Post Request API (<code><a href="https://github.com/modelscope/agentscope/blob/main/src/agentscope/models/post_model.py">agentscope.models.PostAPIModelWrapperBase</a></code>)</summary>
|
||||
|
||||
```python
|
||||
{
|
||||
"config_name": "my_postapiwrapper_config",
|
||||
"model_type": "post_api",
|
||||
|
||||
# 必要参数
|
||||
"api_url": "https://xxx.xxx",
|
||||
"headers": {
|
||||
# 例如:"Authorization": "Bearer xxx",
|
||||
},
|
||||
|
||||
# 可选参数
|
||||
"messages_key": "messages",
|
||||
}
|
||||
```
|
||||
> ⚠️ Post request model wrapper (`PostAPIModelWrapperBase`) 返回原生的 HTTP 响应值, 且没有实现 `.format()`. 当运行样例时,推荐使用 `Post Request Chat API`.
|
||||
> 使用`PostAPIModelWrapperBase`时,需要注意
|
||||
> 1) `.format()` 方法不能被调用;
|
||||
> 2) 或开发者希望实现自己的`.format()`和/或`._parse_response()`
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
<br/>
|
||||
|
||||
## 从零搭建模型服务
|
||||
|
||||
针对需要自己搭建模型服务的开发者,AgentScope提供了一些脚本来帮助开发者快速搭建模型服务。您可以在[scripts](https://github.com/modelscope/agentscope/tree/main/scripts)目录下找到这些脚本以及说明。
|
||||
|
||||
具体而言,AgentScope提供了以下模型服务的脚本:
|
||||
|
||||
- [CPU推理引擎ollama](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#ollama)
|
||||
- [基于Flask + Transformers的模型服务](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#with-transformers-library)
|
||||
- [基于Flask + ModelScope的模型服务](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#with-modelscope-library)
|
||||
- [FastChat推理引擎](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#fastchat)
|
||||
- [vllm推理引擎](https://github.com/modelscope/agentscope/blob/main/scripts/README.md#vllm)
|
||||
|
||||
关于如何快速启动这些模型服务,用户可以参考[scripts](https://github.com/modelscope/agentscope/blob/main/scripts/)目录下的[README.md](https://github.com/modelscope/agentscope/blob/main/scripts/README.md)文件。
|
||||
|
||||
## 创建自己的Model Wrapper
|
||||
|
||||
AgentScope允许开发者自定义自己的模型包装器。新的模型包装器类应该
|
||||
|
||||
- 继承自`ModelWrapperBase`类,
|
||||
- 提供`model_type`字段以在模型配置中标识这个Model Wrapper类,并
|
||||
- 实现`__init__`和`__call__`函数。
|
||||
|
||||
```python
|
||||
from agentscope.models import ModelWrapperBase
|
||||
|
||||
|
||||
class MyModelWrapper(ModelWrapperBase):
|
||||
model_type: str = "my_model"
|
||||
|
||||
def __init__(self, config_name, my_arg1, my_arg2, **kwargs):
|
||||
# 初始化模型实例
|
||||
super().__init__(config_name=config_name)
|
||||
# ...
|
||||
|
||||
def __call__(self, input, **kwargs) -> str:
|
||||
# 调用模型实例
|
||||
# ...
|
||||
```
|
||||
|
||||
在创建新的模型包装器类之后,模型包装器将自动注册到AgentScope中。
|
||||
您可以直接在模型配置中使用它。
|
||||
|
||||
```python
|
||||
my_model_config = {
|
||||
# 基础参数
|
||||
"config_name": "my_model_config",
|
||||
"model_type": "my_model",
|
||||
|
||||
# 详细参数
|
||||
"my_arg1": "xxx",
|
||||
"my_arg2": "yyy",
|
||||
# ...
|
||||
}
|
||||
```
|
||||
|
||||
[[返回顶部]](#203-model-zh)
|
||||
503
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/203-parser.md
Normal file
503
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/203-parser.md
Normal file
@@ -0,0 +1,503 @@
|
||||
(203-parser-zh)=
|
||||
|
||||
# 结果解析
|
||||
|
||||
## 目录
|
||||
|
||||
- [背景](#背景)
|
||||
- [解析器模块](#解析器模块)
|
||||
- [功能说明](#功能说明)
|
||||
- [字符串类型](#字符串str类型)
|
||||
- [MarkdownCodeBlockParser](#markdowncodeblockparser)
|
||||
- [初始化](#初始化)
|
||||
- [响应格式模版](#响应格式模版)
|
||||
- [解析函数](#解析函数)
|
||||
- [字典类型](#字典dict类型)
|
||||
- [MarkdownJsonDictParser](#markdownjsondictparser)
|
||||
- [初始化 & 响应格式模版](#初始化--响应格式模版)
|
||||
- [类型校验](#类型校验)
|
||||
- [MultiTaggedContentParser](#multitaggedcontentparser)
|
||||
- [初始化 & 响应格式模版](#初始化--响应格式模版-1)
|
||||
- [解析函数](#解析函数-1)
|
||||
- [JSON / Python 对象类型](#json--python-对象类型)
|
||||
- [MarkdownJsonObjectParser](#markdownjsonobjectparser)
|
||||
- [初始化 & 响应格式模版](#初始化--响应格式模版-2)
|
||||
- [解析函数](#解析函数-2)
|
||||
- [典型使用样例](#典型使用样例)
|
||||
- [狼人杀游戏](#狼人杀游戏)
|
||||
- [ReAct 智能体和工具使用](#react-智能体和工具使用)
|
||||
- [自定义解析器](#自定义解析器)
|
||||
|
||||
|
||||
## 背景
|
||||
|
||||
利用LLM构建应用的过程中,将 LLM 产生的字符串解析成指定的格式,提取出需要的信息,是一个非常重要的环节。
|
||||
但同时由于下列原因,这个过程也是一个非常复杂的过程:
|
||||
|
||||
1. **多样性**:解析的目标格式多种多样,需要提取的信息可能是一段特定文本,一个JSON对象,或者是一个复杂的数据结构。
|
||||
2. **复杂性**:结果解析不仅仅是将 LLM 产生的文本转换成目标格式,还涉及到提示工程(提醒 LLM 应该产生什么格式的输出),错误处理等一些列问题。
|
||||
3. **灵活性**:同一个应用中,不同阶段也可能需要智能体产生不同格式的输出。
|
||||
|
||||
为了让开发者能够便捷、灵活的地进行结果解析,AgentScope设计并提供了解析器模块(Parser)。利用该模块,开发者可以通过简单的配置,实现目标格式的解析,同时可以灵活的切换解析的目标格式。
|
||||
|
||||
AgentScope中,解析器模块的设计原则是:
|
||||
1. **灵活**:开发者可以灵活设置所需返回格式、灵活地切换解析器,实现不同格式的解析,而无需修改智能体类的代码,即具体的“目标格式”与智能体类内`reply`函数的处理逻辑解耦
|
||||
2. **自由**:用户可以自由选择是否使用解析器。解析器所提供的响应格式提示、解析结果等功能都是在`reply`函数内显式调用的,用户可以自由选择使用解析器或是自己实现代码实现结果解析
|
||||
3. **透明**:利用解析器时,提示(prompt)构建的过程和结果在`reply`函数内对开发者完全可见且透明,开发者可以精确调试自己的应用。
|
||||
|
||||
## 解析器模块
|
||||
|
||||
### 功能说明
|
||||
|
||||
解析器模块(Parser)的主要功能包括:
|
||||
|
||||
1. 提供“响应格式说明”(format instruction),即提示 LLM 应该在什么位置产生什么输出,例如
|
||||
|
||||
````
|
||||
You should generate python code in a fenced code block as follows
|
||||
```python
|
||||
{your_python_code}
|
||||
```
|
||||
````
|
||||
|
||||
|
||||
2. 提供解析函数(parse function),直接将 LLM 产生的文本解析成目标数据格式
|
||||
|
||||
3. 针对字典格式的后处理功能。在将文本解析成字典后,其中不同的字段可能有不同的用处
|
||||
|
||||
AgentScope提供了多种不同解析器,开发者可以根据自己的需求进行选择。
|
||||
|
||||
| 目标格式 | 解析器 | 说明 |
|
||||
|-------------------|----------------------------|-----------------------------------------------------------------------------|
|
||||
| 字符串(`str`)类型 | `MarkdownCodeBlockParser` | 要求 LLM 将指定的文本生成到Markdown中以 ``` 标识的代码块中,解析结果为字符串。 |
|
||||
| 字典(`dict`)类型 | `MarkdownJsonDictParser` | 要求 LLM 在 \```json 和 \``` 标识的代码块中产生指定内容的字典,解析结果为 Python 字典。 |
|
||||
| | `MultiTaggedContentParser` | 要求 LLM 在多个标签中产生指定内容,这些不同标签中的内容将一同被解析成一个 Python 字典,并填入不同的键值对中。 |
|
||||
| JSON / Python对象类型 | `MarkdownJsonObjectParser` | 要求 LLM 在 \```json 和 \``` 标识的代码块中产生指定的内容,解析结果将通过 `json.loads` 转换成 Python 对象。 |
|
||||
|
||||
> **NOTE**: 相比`MarkdownJsonDictParser`,`MultiTaggedContentParser`更适合于模型能力不强,以及需要 LLM 返回内容过于复杂的情况。例如 LLM 返回 Python 代码,如果直接在字典中返回代码,那么 LLM 需要注意特殊字符的转义(\t,\n,...),`json.loads`读取时对双引号和单引号的区分等问题。而`MultiTaggedContentParser`实际是让大模型在每个单独的标签中返回各个键值,然后再将它们组成字典,从而降低了LLM返回的难度。
|
||||
|
||||
> **NOTE**:AgentScope 内置的响应格式说明并不一定是最优的选择。在 AgentScope 中,开发者可以完全控制提示构建的过程,因此,选择不使用parser中内置的相应格式说明,而是自定义新的相应格式说明,或是实现新的parser类都是可行的技术方案。
|
||||
|
||||
下面我们将根据不同的目标格式,介绍这些解析器的用法。
|
||||
|
||||
### 字符串(`str`)类型
|
||||
|
||||
#### MarkdownCodeBlockParser
|
||||
|
||||
##### 初始化
|
||||
|
||||
- `MarkdownCodeBlockParser`采用 Markdown 代码块的形式,要求 LLM 将指定文本产生到指定的代码块中。可以通过`language_name`参数指定不同的语言,从而利用大模型代码能力产生对应的输出。例如要求大模型产生 Python 代码时,初始化如下:
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownCodeBlockParser
|
||||
|
||||
parser = MarkdownCodeBlockParser(language_name="python", content_hint="your python code")
|
||||
```
|
||||
|
||||
##### 响应格式模版
|
||||
|
||||
- `MarkdownCodeBlockParser`类提供如下的“响应格式说明”模版,在用户调用`format_instruction`属性时,会将`{language_name}`替换为初始化时输入的字符串:
|
||||
|
||||
````
|
||||
You should generate {language_name} code in a {language_name} fenced code block as follows:
|
||||
```{language_name}
|
||||
{content_hint}
|
||||
```
|
||||
````
|
||||
|
||||
- 例如上述对`language_name`为`"python"`的初始化,调用`format_instruction`属性时,会返回如下字符串:
|
||||
|
||||
```python
|
||||
print(parser.format_instruction)
|
||||
```
|
||||
|
||||
````
|
||||
You should generate python code in a python fenced code block as follows
|
||||
```python
|
||||
your python code
|
||||
```
|
||||
````
|
||||
|
||||
##### 解析函数
|
||||
|
||||
- `MarkdownCodeBlockParser`类提供`parse`方法,用于解析LLM产生的文本,返回的是字符串。
|
||||
|
||||
````python
|
||||
res = parser.parse(
|
||||
ModelResponse(
|
||||
text="""The following is generated python code
|
||||
```python
|
||||
print("Hello world!")
|
||||
```
|
||||
"""
|
||||
)
|
||||
)
|
||||
|
||||
print(res.parsed)
|
||||
````
|
||||
|
||||
```
|
||||
print("hello world!")
|
||||
```
|
||||
|
||||
### 字典(`dict`)类型
|
||||
|
||||
与字符串和一般的 JSON / Python 对象不同,作为LLM应用中常用的数据格式,AgentScope为字典类型提供了额外的后处理功能。初始化解析器时,可以通过额外设置`keys_to_content`,`keys_to_memory`,`keys_to_metadata`三个参数,从而实现在调用`parser`的`to_content`,`to_memory`和`to_metadata`方法时,对字典键值对的过滤。
|
||||
其中
|
||||
- `keys_to_content` 指定的键值对将被放置在返回`Msg`对象中的`content`字段,这个字段内容将会被返回给其它智能体,参与到其他智能体的提示构建中,同时也会被`self.speak`函数调用,用于显式输出
|
||||
- `keys_to_memory` 指定的键值对将被存储到智能体的记忆中
|
||||
- `keys_to_metadata` 指定的键值对将被放置在`Msg`对象的`metadata`字段,可以用于应用的控制流程判断,或挂载一些不需要返回给其它智能体的信息。
|
||||
|
||||
三个参数接收布尔值、字符串和字符串列表。其值的含义如下:
|
||||
- `False`: 对应的过滤函数将返回`None`。
|
||||
- `True`: 整个字典将被返回。
|
||||
- `str`: 对应的键值将被直接返回,注意返回的会是对应的值而非字典。
|
||||
- `List[str]`: 根据键值对列表返回过滤后的字典。
|
||||
|
||||
AgentScope中,`keys_to_content` 和 `keys_to_memory` 默认为 `True`,即整个字典将被返回。`keys_to_metadata` 默认为 `False`,即对应的过滤函数将返回 `None`。
|
||||
|
||||
下面是狼人杀游戏的样例,在白天讨论过程中 LLM 扮演狼人产生的字典。在这个例子中,
|
||||
- `"thought"`字段不应该返回给其它智能体,但是应该存储在智能体的记忆中,从而保证狼人策略的延续;
|
||||
- `"speak"`字段应该被返回给其它智能体,并且存储在智能体记忆中;
|
||||
- `"finish_discussion"`字段用于应用的控制流程中,判断讨论是否已经结束。为了节省token,该字段不应该被返回给其它的智能体,同时也不应该存储在智能体的记忆中。
|
||||
|
||||
```python
|
||||
{
|
||||
"thought": "The others didn't realize I was a werewolf. I should end the discussion soon.",
|
||||
"speak": "I agree with you.",
|
||||
"finish_discussion": True
|
||||
}
|
||||
```
|
||||
|
||||
AgentScope中,我们通过调用`to_content`,`to_memory`和`to_metadata`方法实现后处理功能,示意代码如下:
|
||||
|
||||
- 应用中的控制流代码,创建对应的解析器对象并装载
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownJsonDictParser
|
||||
|
||||
# ...
|
||||
|
||||
agent = DictDialogAgent(...)
|
||||
|
||||
# 以MarkdownJsonDictParser为例
|
||||
parser = MarkdownJsonDictParser(
|
||||
content_hint={
|
||||
"thought": "what you thought",
|
||||
"speak": "what you speak",
|
||||
"finish_discussion": "whether the discussion is finished"
|
||||
},
|
||||
keys_to_content="speak",
|
||||
keys_to_memory=["thought", "speak"],
|
||||
keys_to_metadata=["finish_discussion"]
|
||||
)
|
||||
|
||||
# 装载解析器,即相当于指定了要求的相应格式
|
||||
agent.set_parser(parser)
|
||||
|
||||
# 讨论过程
|
||||
while True:
|
||||
# ...
|
||||
x = agent(x)
|
||||
# 根据metadata字段,获取LLM对当前是否应该结束讨论的判断
|
||||
if x.metadata["finish_discussion"]:
|
||||
break
|
||||
```
|
||||
|
||||
|
||||
- 智能体内部`reply`函数内实现字典的过滤
|
||||
|
||||
```python
|
||||
# ...
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
|
||||
# ...
|
||||
res = self.model(prompt, parse_func=self.parser.parse)
|
||||
|
||||
# 过滤后拥有 thought 和 speak 字段的字典,存储到智能体记忆中
|
||||
self.memory.add(
|
||||
Msg(
|
||||
self.name,
|
||||
content=self.parser.to_memory(res.parsed),
|
||||
role="assistant",
|
||||
)
|
||||
)
|
||||
|
||||
# 存储到content中,同时存储到metadata中
|
||||
msg = Msg(
|
||||
self.name,
|
||||
content=self.parser.to_content(res.parsed),
|
||||
role="assistant",
|
||||
metadata=self.parser.to_metadata(res.parsed),
|
||||
)
|
||||
self.speak(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
> **Note**: `keys_to_content`,`keys_to_memory`和`keys_to_metadata`参数可以是列表,字符串,也可以是布尔值。
|
||||
> - 如果是`True`,则会直接返回整个字典,即不进行过滤
|
||||
> - 如果是`False`,则会直接返回`None`值
|
||||
> - 如果是字符串类型,则`to_content`,`to_memory`和`to_metadata`方法将会把字符串对应的键值直接放入到对应的位置,例如`keys_to_content="speak"`,则`to_content`方法将会把`res.parsed["speak"]`放入到`Msg`对象的`content`字段中,`content`字段会是字符串而不是字典。
|
||||
> - 如果是列表类型,则`to_content`,`to_memory`和`to_metadata`方法实现的将是过滤功能,对应过滤后的结果是字典
|
||||
> ```python
|
||||
> parser = MarkdownJsonDictParser(
|
||||
> content_hint={
|
||||
> "thought": "what you thought",
|
||||
> "speak": "what you speak",
|
||||
> },
|
||||
> keys_to_content="speak",
|
||||
> keys_to_memory=["thought", "speak"],
|
||||
> )
|
||||
>
|
||||
> example_dict = {"thought": "abc", "speak": "def"}
|
||||
> print(parser.to_content(example_dict)) # def
|
||||
> print(parser.to_memory(example_dict)) # {"thought": "abc", "speak": "def"}
|
||||
> print(parser.to_metadata(example_dict)) # None
|
||||
> ```
|
||||
> ```
|
||||
> def
|
||||
> {"thought": "abc", "speak": "def"}
|
||||
> None
|
||||
> ```
|
||||
|
||||
下面我们具体介绍两种字典类型的解析器。
|
||||
|
||||
#### MarkdownJsonDictParser
|
||||
|
||||
##### 初始化 & 响应格式模版
|
||||
|
||||
- `MarkdownJsonDictParser`要求 LLM 在 \```json 和 \``` 标识的代码块中产生指定内容的字典。
|
||||
- 除了`to_content`,`to_memory`和`to_metadata`参数外,可以通过提供 `content_hint` 参数提供响应结果样例和说明,即提示LLM应该产生什么样子的字典,该参数可以是字符串,也可以是字典,在构建响应格式提示的时候将会被自动转换成字符串进行拼接。
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownJsonDictParser
|
||||
|
||||
# 字典
|
||||
MarkdownJsonDictParser(
|
||||
content_hint={
|
||||
"thought": "what you thought",
|
||||
"speak": "what you speak",
|
||||
}
|
||||
)
|
||||
# 或字符串
|
||||
MarkdownJsonDictParser(
|
||||
content_hint="""{
|
||||
"thought": "what you thought",
|
||||
"speak": "what you speak",
|
||||
}"""
|
||||
)
|
||||
```
|
||||
- 对应的`instruction_format`属性
|
||||
|
||||
````
|
||||
You should respond a json object in a json fenced code block as follows:
|
||||
```json
|
||||
{content_hint}
|
||||
```
|
||||
````
|
||||
|
||||
##### 类型校验
|
||||
|
||||
`MarkdownJsonDictParser`中的`content_hint`参数还支持基于Pydantic的类型校验。初始化时,可以将`content_hint`设置为一个Pydantic的模型类,AgentScope将根据这个类来修改`instruction_format`属性,并且利用Pydantic在解析时对LLM返回的字典进行类型校验。
|
||||
该功能需要LLM能够理解JSON schema格式的提示,因此适用于能力较强的大模型。
|
||||
|
||||
一个简单的例子如下,`"..."`处可以填写具体的类型校验规则,可以参考[Pydantic](https://docs.pydantic.dev/latest/)文档。
|
||||
|
||||
```python
|
||||
from pydantic import BaseModel, Field
|
||||
from agentscope.parsers import MarkdownJsonDictParser
|
||||
|
||||
class Schema(BaseModel):
|
||||
thought: str = Field(..., description="what you thought")
|
||||
speak: str = Field(..., description="what you speak")
|
||||
end_discussion: bool = Field(..., description="whether the discussion is finished")
|
||||
|
||||
parser = MarkdownJsonDictParser(content_hint=Schema)
|
||||
```
|
||||
|
||||
- 对应的`format_instruction`属性
|
||||
|
||||
````
|
||||
Respond a JSON dictionary in a markdown's fenced code block as follows:
|
||||
```json
|
||||
{a_JSON_dictionary}
|
||||
```
|
||||
The generated JSON dictionary MUST follow this schema:
|
||||
{'properties': {'speak': {'description': 'what you speak', 'title': 'Speak', 'type': 'string'}, 'thought': {'description': 'what you thought', 'title': 'Thought', 'type': 'string'}, 'end_discussion': {'description': 'whether the discussion reached an agreement or not', 'title': 'End Discussion', 'type': 'boolean'}}, 'required': ['speak', 'thought', 'end_discussion'], 'title': 'Schema', 'type': 'object'}
|
||||
````
|
||||
|
||||
- 同时在解析的过程中,也将使用Pydantic进行类型校验,校验错误将抛出异常。同时,Pydantic也将提供一定的容错处理能力,例如将字符串`"true"`转换成Python的`True`:
|
||||
|
||||
````
|
||||
parser.parser("""
|
||||
```json
|
||||
{
|
||||
"thought": "The others didn't realize I was a werewolf. I should end the discussion soon.",
|
||||
"speak": "I agree with you.",
|
||||
"end_discussion": "true"
|
||||
}
|
||||
```
|
||||
""")
|
||||
````
|
||||
|
||||
#### MultiTaggedContentParser
|
||||
|
||||
`MultiTaggedContentParser`要求 LLM 在多个指定的标签对中产生指定的内容,这些不同标签的内容将一同被解析为一个 Python 字典。使用方法与`MarkdownJsonDictParser`类似,只是初始化方法不同,更适合能力较弱的LLM,或是比较复杂的返回内容。
|
||||
|
||||
##### 初始化 & 响应格式模版
|
||||
|
||||
`MultiTaggedContentParser`中,每一组标签将会以`TaggedContent`对象的形式传入,其中`TaggedContent`对象包含了
|
||||
- 标签名(`name`),即返回字典中的key值
|
||||
- 开始标签(`tag_begin`)
|
||||
- 标签内容提示(`content_hint`)
|
||||
- 结束标签(`tag_end`)
|
||||
- 内容解析功能(`parse_json`),默认为`False`。当置为`True`时,将在响应格式提示中自动添加提示,并且提取出的内容将通过`json.loads`解析成 Python 对象
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MultiTaggedContentParser, TaggedContent
|
||||
parser = MultiTaggedContentParser(
|
||||
TaggedContent(
|
||||
name="thought",
|
||||
tag_begin="[THOUGHT]",
|
||||
content_hint="what you thought",
|
||||
tag_end="[/THOUGHT]"
|
||||
),
|
||||
TaggedContent(
|
||||
name="speak",
|
||||
tag_begin="[SPEAK]",
|
||||
content_hint="what you speak",
|
||||
tag_end="[/SPEAK]"
|
||||
),
|
||||
TaggedContent(
|
||||
name="finish_discussion",
|
||||
tag_begin="[FINISH_DISCUSSION]",
|
||||
content_hint="true/false, whether the discussion is finished",
|
||||
tag_end="[/FINISH_DISCUSSION]",
|
||||
parse_json=True, # 我们希望这个字段的内容直接被解析成 True 或 False 的 Python 布尔值
|
||||
)
|
||||
)
|
||||
|
||||
print(parser.format_instruction)
|
||||
```
|
||||
|
||||
```
|
||||
Respond with specific tags as outlined below, and the content between [FINISH_DISCUSSION] and [/FINISH_DISCUSSION] MUST be a JSON object:
|
||||
[THOUGHT]what you thought[/THOUGHT]
|
||||
[SPEAK]what you speak[/SPEAK]
|
||||
[FINISH_DISCUSSION]true/false, whether the discussion is finished[/FINISH_DISCUSSION]
|
||||
```
|
||||
|
||||
##### 解析函数
|
||||
|
||||
- `MultiTaggedContentParser`的解析结果为字典,其中key为`TaggedContent`对象的`name`的值,以下是狼人杀中解析 LLM 返回的样例:
|
||||
|
||||
```python
|
||||
res_dict = parser.parse(
|
||||
ModelResponse(text="""As a werewolf, I should keep pretending to be a villager
|
||||
[THOUGHT]The others didn't realize I was a werewolf. I should end the discussion soon.[/THOUGHT]
|
||||
[SPEAK]I agree with you.[/SPEAK]
|
||||
[FINISH_DISCUSSION]true[/FINISH_DISCUSSION]
|
||||
"""
|
||||
)
|
||||
)
|
||||
|
||||
print(res_dict)
|
||||
```
|
||||
|
||||
```
|
||||
{
|
||||
"thought": "The others didn't realize I was a werewolf. I should end the discussion soon.",
|
||||
"speak": "I agree with you.",
|
||||
"finish_discussion": true
|
||||
}
|
||||
```
|
||||
|
||||
### JSON / Python 对象类型
|
||||
|
||||
#### MarkdownJsonObjectParser
|
||||
|
||||
`MarkdownJsonObjectParser`同样采用 Markdown 的\```json和\```标识,但是不限制解析的内容的类型,可以是列表,字典,数值,字符串等可以通过`json.loads`进行解析字符串。
|
||||
|
||||
##### 初始化 & 响应格式模版
|
||||
|
||||
```python
|
||||
from agentscope.parsers import MarkdownJsonObjectParser
|
||||
|
||||
parser = MarkdownJsonObjectParser(
|
||||
content_hint="{A list of numbers.}"
|
||||
)
|
||||
|
||||
print(parser.format_instruction)
|
||||
```
|
||||
|
||||
````
|
||||
You should respond a json object in a json fenced code block as follows:
|
||||
```json
|
||||
{a list of numbers}
|
||||
```
|
||||
````
|
||||
|
||||
##### 解析函数
|
||||
|
||||
````python
|
||||
res = parser.parse(
|
||||
ModelResponse(text="""Yes, here is the generated list
|
||||
```json
|
||||
[1,2,3,4,5]
|
||||
```
|
||||
"""
|
||||
)
|
||||
)
|
||||
|
||||
print(type(res))
|
||||
print(res)
|
||||
````
|
||||
|
||||
```
|
||||
<class 'list'>
|
||||
[1, 2, 3, 4, 5]
|
||||
```
|
||||
|
||||
## 典型使用样例
|
||||
|
||||
### 狼人杀游戏
|
||||
|
||||
狼人杀(Werewolf)是字典解析器的一个经典使用场景,在游戏的不同阶段内,需要同一个智能体在不同阶段产生除了`"thought"`和`"speak"`外其它的标识字段,例如是否结束讨论,预言家是否使用能力,女巫是否使用解药和毒药,投票等。
|
||||
|
||||
AgentScope中已经内置了[狼人杀](https://github.com/modelscope/agentscope/tree/main/examples/game_werewolf)的样例,该样例采用`DictDialogAgent`类,配合不同的解析器,实现了灵活的目标格式切换。同时利用解析器的后处理功能,实现了“想”与“说”的分离,同时控制游戏流程的推进。
|
||||
详细实现请参考狼人杀[源码](https://github.com/modelscope/agentscope/tree/main/examples/game_werewolf)。
|
||||
|
||||
### ReAct 智能体和工具使用
|
||||
|
||||
`ReActAgent`是AgentScope中为了工具使用构建的智能体类,基于 ReAct 算法进行搭建,可以配合不同的工具函数进行使用。其中工具的调用,格式解析,采用了和解析器同样的实现思路。详细实现请参考[代码](https://github.com/modelscope/agentscope/blob/main/src/agentscope/agents/react_agent.py)。
|
||||
|
||||
|
||||
## 自定义解析器
|
||||
|
||||
AgentScope中提供了解析器的基类`ParserBase`,开发者可以通过继承该基类,并实现其中的`format_instruction`属性和`parse`方法来实现自己的解析器。
|
||||
|
||||
针对目标格式是字典类型的解析,可以额外继承`agentscope.parser.DictFilterMixin`类实现对字典类型的后处理。
|
||||
|
||||
```python
|
||||
from abc import ABC, abstractmethod
|
||||
|
||||
from agentscope.models import ModelResponse
|
||||
|
||||
|
||||
class ParserBase(ABC):
|
||||
"""The base class for model response parser."""
|
||||
|
||||
format_instruction: str
|
||||
"""The instruction for the response format."""
|
||||
|
||||
@abstractmethod
|
||||
def parse(self, response: ModelResponse) -> ModelResponse:
|
||||
"""Parse the response text to a specific object, and stored in the
|
||||
parsed field of the response object."""
|
||||
|
||||
# ...
|
||||
```
|
||||
308
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/204-service.md
Normal file
308
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/204-service.md
Normal file
@@ -0,0 +1,308 @@
|
||||
(204-service-zh)=
|
||||
|
||||
# 工具
|
||||
|
||||
服务函数(Service function)是可以增强智能体能力工具,例如执行Python代码、网络搜索、
|
||||
文件操作等。本教程概述了AgentScope中可用的服务功能,同时介绍如何使用它们来增强智能体的能力。
|
||||
|
||||
## Service函数概览
|
||||
|
||||
下面的表格按照类型概述了各种Service函数。以下函数可以通过`agentscope.service.{函数名}`进行调用。
|
||||
|
||||
| Service场景 | Service函数名称 | 描述 |
|
||||
|------------|-----------------------|-----------------------------------------|
|
||||
| 代码 | `execute_python_code` | 执行一段 Python 代码,可选择在 Docker <br/>容器内部执行。 |
|
||||
| 检索 | `retrieve_from_list` | 根据给定的标准从列表中检索特定项目。 |
|
||||
| | `cos_sim` | 计算2个embedding的余弦相似度。 |
|
||||
| SQL查询 | `query_mysql` | 在 MySQL 数据库上执行 SQL 查询并返回结果。 |
|
||||
| | `query_sqlite` | 在 SQLite 数据库上执行 SQL 查询并返回结果。 |
|
||||
| | `query_mongodb` | 对 MongoDB 集合执行查询或操作。 |
|
||||
| 文本处理 | `summarization` | 使用大型语言模型总结一段文字以突出其主要要点。 |
|
||||
| 网络 | `bing_search` | 使用bing搜索。 |
|
||||
| | `google_search` | 使用google搜索。 |
|
||||
| | `arxiv_search` | 使用arxiv搜索。 |
|
||||
| | `download_from_url` | 从指定的 URL 下载文件。 |
|
||||
| | `load_web` | 爬取并解析指定的网页链接 (目前仅支持爬取 HTML 页面) |
|
||||
| | `digest_webpage` | 对已经爬取好的网页生成摘要信息(目前仅支持 HTML 页面
|
||||
| | `dblp_search_publications` | 在dblp数据库里搜索文献。
|
||||
| | `dblp_search_authors` | 在dblp数据库里搜索作者。 |
|
||||
| | `dblp_search_venues` | 在dblp数据库里搜索期刊,会议及研讨会。 |
|
||||
| 文件处理 | `create_file` | 在指定路径创建一个新文件,并可选择添加初始内容。 |
|
||||
| | `delete_file` | 删除由文件路径指定的文件。 |
|
||||
| | `move_file` | 将文件从一个路径移动或重命名到另一个路径。 |
|
||||
| | `create_directory` | 在指定路径创建一个新的目录。 |
|
||||
| | `delete_directory` | 删除一个目录及其所有内容。 |
|
||||
| | `move_directory` | 将目录从一个路径移动或重命名到另一个路径。 |
|
||||
| | `read_text_file` | 读取并返回文本文件的内容。 |
|
||||
| | `write_text_file` | 向指定路径的文件写入文本内容。 |
|
||||
| | `read_json_file` | 读取并解析 JSON 文件的内容。 |
|
||||
| | `write_json_file` | 将 Python 对象序列化为 JSON 并写入到文件。 |
|
||||
| 多模态 | `dashscope_text_to_image` | 使用 DashScope API 将文本生成图片。 |
|
||||
| | `dashscope_image_to_text` | 使用 DashScope API 根据图片生成文字。 |
|
||||
| | `dashscope_text_to_audio` | 使用 DashScope API 根据文本生成音频。 |
|
||||
| | `openai_text_to_image` | 使用 OpenAI API根据文本生成图片。
|
||||
| | `openai_edit_image` | 使用 OpenAI API 根据提供的遮罩和提示编辑图像。
|
||||
| | `openai_create_image_variation` | 使用 OpenAI API 创建图像的变体。
|
||||
| | `openai_image_to_text` | 使用 OpenAI API 根据图片生成文字。
|
||||
| | `openai_text_to_audio` | 使用 OpenAI API 根据文本生成音频。
|
||||
| | `openai_audio_to_text` | 使用OpenAI API将音频转换为文本。
|
||||
| *更多服务即将推出* | | 正在开发更多服务功能,并将添加到 AgentScope 以进一步增强其能力。 |
|
||||
|
||||
关于详细的参数、预期输入格式、返回类型,请参阅[API文档](https://modelscope.github.io/agentscope/)。
|
||||
|
||||
## 使用Service函数
|
||||
|
||||
AgentScope为Service函数提供了两个服务类,分别是`ServiceToolkit`和`ServiceResponse`。
|
||||
|
||||
### 关于ServiceToolkit
|
||||
|
||||
大模型使用工具函数通常涉及以下5个步骤:
|
||||
|
||||
1. **准备工具函数**。即开发者通过提供必要的参数(例如api key、用户名、密码等)将工具函数预处理成大模型能直接调用的形式。
|
||||
2. **为大模型准备工具描述**。即一份详细的函数功能描述,以便大模型能够正确理解工具函数。
|
||||
3. **约定函数调用格式**。提供一份说明来告诉大模型如何调用工具函数,即调用格式。
|
||||
4. **解析大模型返回值**。从大模型获取返回值之后,需要按照第三步中的调用格式来解析字符串。
|
||||
5. **调用函数并处理异常**。实际调用函数,返回结果,并处理异常。
|
||||
|
||||
为了简化上述步骤并提高复用性,AgentScope引入了ServiceToolkit模块。它可以
|
||||
- 注册python函数为工具函数
|
||||
- 生成字符串和JSON schema格式的工具函数说明
|
||||
- 内置一套工具函数的调用格式
|
||||
- 解析模型响应、调用工具功能,并处理异常
|
||||
|
||||
|
||||
#### 如何使用
|
||||
|
||||
按照以下步骤使用ServiceToolkit:
|
||||
|
||||
1. 初始化一个ServiceToolkit对象并注册服务函数及其必要参数。例如,以下Bing搜索功能。
|
||||
|
||||
```python
|
||||
def bing_search(
|
||||
question: str,
|
||||
api_key: str,
|
||||
num_results: int = 10,
|
||||
**kwargs: Any,
|
||||
) -> ServiceResponse:
|
||||
"""
|
||||
Search question in Bing Search API and return the searching results
|
||||
|
||||
Args:
|
||||
question (`str`):
|
||||
The search query string.
|
||||
api_key (`str`):
|
||||
The API key provided for authenticating with the Bing Search API.
|
||||
num_results (`int`, defaults to `10`):
|
||||
The number of search results to return.
|
||||
**kwargs (`Any`):
|
||||
Additional keyword arguments to be included in the search query.
|
||||
For more details, please refer to
|
||||
https://learn.microsoft.com/en-us/bing/search-apis/bing-web-search/reference/query-parameters
|
||||
|
||||
[omitted for brevity]
|
||||
"""
|
||||
```
|
||||
We register the function in a `ServiceToolkit` object by providing `api_key` and `num_results` as necessary parameters.
|
||||
我们通过提供`api_key`和`num_results`作为必要参数,在`ServiceToolkit`对象中注册bing_search函数。
|
||||
|
||||
```python
|
||||
from agentscope.service import ServiceToolkit
|
||||
|
||||
service_toolkit = ServiceToolkit()
|
||||
|
||||
service_toolkit.add(
|
||||
bing_search,
|
||||
api_key="xxx",
|
||||
num_results=3
|
||||
)
|
||||
```
|
||||
|
||||
2. 在提示中使用`tools_instruction`属性指导LLM,或使用`json_schemas`属性获取JSON schema格式的说明,以构建自定义格式的函数说明或直接在模型API中使用(例如OpenAI Chat API)。
|
||||
|
||||
|
||||
````text
|
||||
>> print(service_toolkit.tools_instruction)
|
||||
## Tool Functions:
|
||||
The following tool functions are available in the format of
|
||||
```
|
||||
{index}. {function name}: {function description}
|
||||
{argument1 name} ({argument type}): {argument description}
|
||||
{argument2 name} ({argument type}): {argument description}
|
||||
...
|
||||
```
|
||||
|
||||
1. bing_search: Search question in Bing Search API and return the searching results
|
||||
question (str): The search query string.
|
||||
````
|
||||
````text
|
||||
>> print(service_toolkit.json_schemas)
|
||||
{
|
||||
"bing_search": {
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "bing_search",
|
||||
"description": "Search question in Bing Search API and return the searching results",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"question": {
|
||||
"type": "string",
|
||||
"description": "The search query string."
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"question"
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
````
|
||||
|
||||
3. 通过`tools_calling_format`属性指导LLM如何使用工具函数。ServiceToolkit中默认大模型
|
||||
需要返回一个JSON格式的列表,列表中包含若干个字典,每个字典即为一个函数调用。必须包含name和
|
||||
arguments两个字段,其中name为函数名,arguments为函数参数。arguments键值对应的值是从
|
||||
“参数名”映射到“参数值”的字典。
|
||||
|
||||
```text
|
||||
>> print(service_toolkit.tools_calling_format)
|
||||
[{"name": "{function name}", "arguments": {"{argument1 name}": xxx, "{argument2 name}": xxx}}]
|
||||
```
|
||||
|
||||
4. 通过`parse_and_call_func`方法解析大模型生成的字符串,并调用函数。此函数可以接收字符串或解析后符合格式要求的字典作为输入。
|
||||
- 当输入为字符串时,此函数将相应地解析字符串并使用解析后的参数执行函数。
|
||||
- 而如果输入为解析后的字典,则直接调用函数。
|
||||
|
||||
|
||||
```python
|
||||
# a string input
|
||||
string_input = '[{"name": "bing_search", "arguments": {"question": "xxx"}}]'
|
||||
res_of_string_input = service_toolkit.parse_and_call_func(string_input)
|
||||
|
||||
# or a parsed dictionary
|
||||
dict_input = [{"name": "bing_search", "arguments": {"question": "xxx"}}]
|
||||
# res_of_dict_input is the same as res_of_string_input
|
||||
res_of_dict_input = service_toolkit.parse_and_call_func(dict_input)
|
||||
|
||||
print(res_of_string_input)
|
||||
```
|
||||
```
|
||||
1. Execute function bing_search
|
||||
[ARGUMENTS]:
|
||||
question: xxx
|
||||
[STATUS]: SUCCESS
|
||||
[RESULT]: ...
|
||||
```
|
||||
|
||||
关于ServiceToolkit的具体使用样例,可以参考`agentscope.agents`中`ReActAgent`类。
|
||||
|
||||
#### 创建新的Service函数
|
||||
|
||||
新的Service函数必须满足以下要求才能被ServiceToolkit正常使用:
|
||||
1. 具有格式化的函数说明(推荐Google风格),以便ServiceToolkit提取函数说明。
|
||||
2. 函数名称应该是自解释的,这样智能体可以理解函数并正确使用它。
|
||||
3. 在定义函数时应提供参数的类型(例如`def func(a: int, b: str, c: bool)`),以便大模型
|
||||
能够给出类型正确的参数。
|
||||
|
||||
|
||||
### 关于ServiceResponse
|
||||
|
||||
`ServiceResponse`是对调用的结果的封装,包含了`status`和`content`两个字段。
|
||||
当Service函数正常运行结束时,`status`为`ServiceExecStatus.
|
||||
SUCCESS`,`content`为函数的返回值。而当运行出现错误时,`status`为`ServiceExecStatus.
|
||||
Error`,`content`内为错误信息。
|
||||
|
||||
```python
|
||||
class ServiceResponse(dict):
|
||||
"""Used to wrap the execution results of the services"""
|
||||
|
||||
__setattr__ = dict.__setitem__
|
||||
__getattr__ = dict.__getitem__
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
status: ServiceExecStatus,
|
||||
content: Any,
|
||||
):
|
||||
"""Constructor of ServiceResponse
|
||||
|
||||
Args:
|
||||
status (`ServiceExeStatus`):
|
||||
The execution status of the service.
|
||||
content (`Any`)
|
||||
If the argument`status` is `SUCCESS`, `content` is the
|
||||
response. We use `object` here to support various objects,
|
||||
e.g. str, dict, image, video, etc.
|
||||
Otherwise, `content` is the error message.
|
||||
"""
|
||||
self.status = status
|
||||
self.content = content
|
||||
|
||||
# ... [为简洁起见省略代码]
|
||||
|
||||
```
|
||||
|
||||
## 示例
|
||||
|
||||
```python
|
||||
import json
|
||||
import inspect
|
||||
from agentscope.service import ServiceResponse
|
||||
from agentscope.agents import AgentBase
|
||||
|
||||
|
||||
def create_file(file_path: str, content: str = "") -> ServiceResponse:
|
||||
"""
|
||||
创建文件并向其中写入内容。
|
||||
|
||||
Args:
|
||||
file_path (str): 将要创建文件的路径。
|
||||
content (str): 要写入文件的内容。
|
||||
|
||||
Returns:
|
||||
ServiceResponse: 其中布尔值指示成功与否,字符串包含任何错误消息(如果有),包括错误类型。
|
||||
"""
|
||||
# ... [为简洁起见省略代码]
|
||||
|
||||
|
||||
class YourAgent(AgentBase):
|
||||
# ... [为简洁起见省略代码]
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
# ... [为简洁起见省略代码]
|
||||
|
||||
# 构造提示,让代理提供 JSON 格式的参数
|
||||
prompt = (
|
||||
f"To complete the user request\n```{x['content']}```\n"
|
||||
"Please provide the necessary parameters in JSON format for the "
|
||||
"function:\n"
|
||||
f"Function: {create_file.__name__}\n"
|
||||
"Description: Create a file and write content to it.\n"
|
||||
)
|
||||
|
||||
# 添加关于函数参数的详细信息
|
||||
sig = inspect.signature(create_file)
|
||||
parameters = sig.parameters.items()
|
||||
params_prompt = "\n".join(
|
||||
f"- {name} ({param.annotation.__name__}): "
|
||||
f"{'(default: ' + json.dumps(param.default) + ')'if param.default is not inspect.Parameter.empty else ''}"
|
||||
for name, param in parameters
|
||||
)
|
||||
prompt += params_prompt
|
||||
|
||||
# 获取模型响应
|
||||
model_response = self.model(prompt).text
|
||||
|
||||
# 解析模型响应并调用 create_file 函数
|
||||
# 可能需要额外的提取函数
|
||||
try:
|
||||
kwargs = json.loads(model_response)
|
||||
create_file(**kwargs)
|
||||
except:
|
||||
# 错误处理
|
||||
pass
|
||||
|
||||
# ... [为简洁起见省略代码]
|
||||
```
|
||||
|
||||
[[返回顶部]](#204-service-zh)
|
||||
214
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/205-memory.md
Normal file
214
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/205-memory.md
Normal file
@@ -0,0 +1,214 @@
|
||||
(205-memory-zh)=
|
||||
|
||||
# 记忆
|
||||
|
||||
AgentScope中,记忆(memory)用于存储历史消息,从而使智能体能够根据上下文提供更加连贯,更加
|
||||
自然的响应。
|
||||
本教程将首先介绍memory中信息的载体,消息(message),然后介绍AgentScope中记忆模块的功能
|
||||
和使用方法。
|
||||
|
||||
## 关于消息(Message)
|
||||
|
||||
### 消息基类(`MessageBase`)
|
||||
|
||||
AgentScope中,消息基类是Python字典的子类,由`name`,`content`两个必选字段和一个可选的字段
|
||||
`url`组成。由于是字典类型,开发者也可以根据需要增加其他字段。
|
||||
其中,`name`字段代表消息的发起者,`content`字段代表消息的内容,`url
|
||||
`则代表消息中附加的数据链接,可以是指向多模态数据的本地链接,也可以是网络链接。
|
||||
当一个消息被创建时,将会自动创建一个唯一的ID,用于标识这条消息。同时,消息的创建时间也会以
|
||||
时间戳的形式自动记录下来。
|
||||
|
||||
具体实现中,AgentScope首先提供了一个`MessageBase`基类,用于定义消息的基本属性和使用方法。
|
||||
与一般的字典类型不同,`MessageBase`的实例化对象可以通过`对象名.{属性名}`的方式访问属性值,
|
||||
也可以通过`对象名['属性名']`的方式访问属性值。
|
||||
其中,`MessageBase` 类的关键属性如下:
|
||||
|
||||
- **`name`**:该属性表示信息的发起者。这是一项关键的元数据,在需要区分不同发言者的场景中非常有用。
|
||||
- **`content`**:信息本身的内容。它可以包括文本、结构化数据或其他与交互相关且需要智能体处理的内容形式。
|
||||
- **`url`**:可选属性,允许信息链接到外部资源。这些可以是指向文件的直接链接、多模态数据或网页。
|
||||
- **`timestamp`**:时间戳,显示信息创建的时间。
|
||||
- **`id`**:每条信息在创建时都会被分配一个唯一标识符(ID)。
|
||||
|
||||
```python
|
||||
class MessageBase(dict):
|
||||
"""Base Message class, which is used to maintain information for dialog,
|
||||
memory and used to construct prompt.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
content: Any,
|
||||
url: Optional[Union[Sequence[str], str]] = None,
|
||||
timestamp: Optional[str] = None,
|
||||
**kwargs: Any,
|
||||
) -> None:
|
||||
"""Initialize the message object
|
||||
|
||||
Args:
|
||||
name (`str`):
|
||||
The name of who send the message. It's often used in
|
||||
role-playing scenario to tell the name of the sender.
|
||||
However, you can also only use `role` when calling openai api.
|
||||
The usage of `name` refers to
|
||||
https://cookbook.openai.com/examples/how_to_format_inputs_to_chatgpt_models.
|
||||
content (`Any`):
|
||||
The content of the message.
|
||||
url (`Optional[Union[list[str], str]]`, defaults to None):
|
||||
A url to file, image, video, audio or website.
|
||||
timestamp (`Optional[str]`, defaults to None):
|
||||
The timestamp of the message, if None, it will be set to
|
||||
current time.
|
||||
**kwargs (`Any`):
|
||||
Other attributes of the message. For OpenAI API, you should
|
||||
add "role" from `["system", "user", "assistant", "function"]`.
|
||||
When calling OpenAI API, `"role": "assistant"` will be added
|
||||
to the messages that don't have "role" attribute.
|
||||
|
||||
"""
|
||||
# id and timestamp will be added to the object as its attributes
|
||||
# rather than items in dict
|
||||
self.id = uuid4().hex
|
||||
if timestamp is None:
|
||||
self.timestamp = _get_timestamp()
|
||||
else:
|
||||
self.timestamp = timestamp
|
||||
|
||||
self.name = name
|
||||
self.content = content
|
||||
|
||||
if url:
|
||||
self.url = url
|
||||
|
||||
self.update(kwargs)
|
||||
|
||||
def __getattr__(self, key: Any) -> Any:
|
||||
try:
|
||||
return self[key]
|
||||
except KeyError as e:
|
||||
raise AttributeError(f"no attribute '{key}'") from e
|
||||
|
||||
def __setattr__(self, key: Any, value: Any) -> None:
|
||||
self[key] = value
|
||||
|
||||
def __delattr__(self, key: Any) -> None:
|
||||
try:
|
||||
del self[key]
|
||||
except KeyError as e:
|
||||
raise AttributeError(f"no attribute '{key}'") from e
|
||||
|
||||
def to_str(self) -> str:
|
||||
"""Return the string representation of the message"""
|
||||
raise NotImplementedError
|
||||
|
||||
def serialize(self) -> str:
|
||||
"""Return the serialized message."""
|
||||
raise NotImplementedError
|
||||
|
||||
# ... [省略代码以简化]
|
||||
```
|
||||
|
||||
### 消息类(`Msg`)
|
||||
|
||||
`Msg`类是AgentScope中最常用的消息类。它继承了 `MessageBase`类,并实现了`to_str` 和
|
||||
`serialize` 抽象方法。
|
||||
在一个Agent类中,其`reply`函数通常会返回一个`Msg`类的实例,以便在AgentScope中进行消息的
|
||||
传递。
|
||||
|
||||
```python
|
||||
class Msg(MessageBase):
|
||||
"""The Message class."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
content: Any,
|
||||
url: Optional[Union[Sequence[str], str]] = None,
|
||||
timestamp: Optional[str] = None,
|
||||
echo: bool = False,
|
||||
**kwargs: Any,
|
||||
) -> None:
|
||||
super().__init__(
|
||||
name=name,
|
||||
content=content,
|
||||
url=url,
|
||||
timestamp=timestamp,
|
||||
**kwargs,
|
||||
)
|
||||
if echo:
|
||||
logger.chat(self)
|
||||
|
||||
def to_str(self) -> str:
|
||||
"""Return the string representation of the message"""
|
||||
return f"{self.name}: {self.content}"
|
||||
|
||||
def serialize(self) -> str:
|
||||
return json.dumps({"__type": "Msg", **self})
|
||||
```
|
||||
|
||||
## 关于记忆(Memory)
|
||||
|
||||
### 关于记忆基类(`MemoryBase`)
|
||||
|
||||
`MemoryBase` 是一个抽象类,以结构化的方式处理智能体的记忆。它定义了存储、检索、删除和操作
|
||||
*信息*内容的操作。
|
||||
|
||||
```python
|
||||
class MemoryBase(ABC):
|
||||
# ... [省略代码以简化]
|
||||
|
||||
def get_memory(
|
||||
self,
|
||||
return_type: PromptType = PromptType.LIST,
|
||||
recent_n: Optional[int] = None,
|
||||
filter_func: Optional[Callable[[int, dict], bool]] = None,
|
||||
) -> Union[list, str]:
|
||||
raise NotImplementedError
|
||||
|
||||
def add(self, memories: Union[list[dict], dict]) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def delete(self, index: Union[Iterable, int]) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def load(
|
||||
self,
|
||||
memories: Union[str, dict, list],
|
||||
overwrite: bool = False,
|
||||
) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def export(
|
||||
self,
|
||||
to_mem: bool = False,
|
||||
file_path: Optional[str] = None,
|
||||
) -> Optional[list]:
|
||||
raise NotImplementedError
|
||||
|
||||
def clear(self) -> None:
|
||||
raise NotImplementedError
|
||||
|
||||
def size(self) -> int:
|
||||
raise NotImplementedError
|
||||
```
|
||||
|
||||
以下是 `MemoryBase` 的关键方法:
|
||||
|
||||
- **`get_memory`**:这个方法负责从智能体的记忆中检索存储的信息。它可以按照 `return_type` 指定的格式返回这些信息。该方法还可以在提供 `recent_n` 时检索特定数量的最近信息,并且可以应用过滤函数( `filter_func` )来根据自定义标准选择信息。
|
||||
- **`add`**:这个方法用于将新的信息添加到智能体的记忆中。它可以接受单个信息或信息列表。每条信息通常是 `MessageBase` 或其子类的实例。
|
||||
- **`delete`**:此方法允许通过信息的索引(如果提供可迭代对象,则为索引集合)从记忆中删除信息。
|
||||
- **`load`**:这个方法允许从外部来源批量加载信息到智能体的内存中。`overwrite` 参数决定是否在加载新的信息集之前清除现有记忆。
|
||||
- **`export`**:这个方法便于将存储的*信息*从智能体的记忆中导出,要么导出到一个外部文件(由 `file_path` 指定),要么直接导入到程序的运行内存中(如果 `to_mem` 设置为 `True` )。
|
||||
- **`clear`**:这个方法清除智能体记忆中的所有*信息*,本质上是重置。
|
||||
- **`size`**:这个方法返回当前存储在智能体记忆中的信息数量。
|
||||
|
||||
### 关于`TemporaryMemory`
|
||||
|
||||
`TemporaryMemory` 类是 `MemoryBase` 类的一个具体实现,提供了一个智能体运行期间存在的记忆存储,被用作智能体的默认记忆类型。除了 `MemoryBase` 的所有行为外,`TemporaryMemory` 还提供了检索的方法:
|
||||
|
||||
- **`retrieve_by_embedding`**:基于它们的嵌入向量 (embeddings) 检索与查询最相似的 `messages`。它使用提供的度量标准来确定相关性,并可以返回前 `k` 个最相关的信息。
|
||||
- **`get_embeddings`**:返回记忆中所有信息的嵌入向量。如果信息没有嵌入向量,并且提供了嵌入模型,它将生成并存储信息的嵌入向量。
|
||||
|
||||
有关 `Memory` 和 `Msg` 使用的更多细节,请参考 API 文档。
|
||||
|
||||
[[返回顶端]](#205-memory-zh)
|
||||
546
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/206-prompt.md
Normal file
546
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/206-prompt.md
Normal file
@@ -0,0 +1,546 @@
|
||||
(206-prompt-zh)=
|
||||
|
||||
# 提示工程
|
||||
|
||||
提示工程是与大型语言模型(LLMs)相关的应用中至关重要的组件。然而,为大型语言模型(LLMs)制作提示可能具有挑战性,尤其是在面对来自不同模型API的不同需求时。
|
||||
|
||||
为了帮助开发者更好地适应不同模型API的需求,AgentScope提供了一种结构化的方式来组织不同数据类型(例如指令、提示、对话历史)到所需的格式。
|
||||
|
||||
请注意这里不存在一个“**适用于所有模型API**”的提示构建方案。
|
||||
AgentScope内置策略的目标是**使初学者能够顺利调用模型API ,而不是使应用达到最佳效果**。对于进阶用户,我们强烈建议开发者根据自己的需求和模型API的要求自定义提示。
|
||||
|
||||
## 构建提示面临的挑战
|
||||
|
||||
在多智能体应用中,LLM通常在对话中扮演不同的角色。当使用模型的Chat API时,时长会面临以下挑战:
|
||||
|
||||
1. 大多数Chat类型的模型API是为聊天机器人场景设计的,`role`字段只支持`"user"`和`"assistant"`,不支持`name`字段,即API本身不支持角色扮演。
|
||||
|
||||
2. 一些模型API要求`"user"`和`"assistant"`必须交替发言,而`"user"`必须在输入消息列表的开头和结尾发言。这样的要求使得在一个代理可能扮演多个不同角色并连续发言时,构建多智能体对话变得困难。
|
||||
|
||||
为了帮助初学者快速开始使用AgentScope,我们为大多数与聊天和生成相关的模型API提供了以下内置策略。
|
||||
|
||||
## 内置提示策略
|
||||
|
||||
AgentScope为以下的模型API提供了内置的提示构建策略。
|
||||
|
||||
- [OpenAIChatWrapper](#openaichatwrapper)
|
||||
- [DashScopeChatWrapper](#dashscopechatwrapper)
|
||||
- [DashScopeMultiModalWrapper](#dashscopemultimodalwrapper)
|
||||
- [OllamaChatWrapper](#ollamachatwrapper)
|
||||
- [OllamaGenerationWrapper](#ollamagenerationwrapper)
|
||||
- [GeminiChatWrapper](#geminichatwrapper)
|
||||
- [ZhipuAIChatWrapper](#zhipuaichatwrapper)
|
||||
|
||||
这些策略是在对应Model Wrapper类的`format`函数中实现的。它接受`Msg`对象,`Msg`对象的列表或它们的混合作为输入。在`format`函数将会把输入重新组织成一个`Msg`对象的列表,因此为了方便解释,我们在下面的章节中认为`format`函数的输入是`Msg`对象的列表。
|
||||
|
||||
### `OpenAIChatWrapper`
|
||||
|
||||
`OpenAIChatWrapper`封装了OpenAI聊天API,它以字典列表作为输入,其中字典必须遵循以下规则(更新于2024/03/22):
|
||||
|
||||
- 需要`role`和`content`字段,以及一个可选的`name`字段。
|
||||
- `role`字段必须是`"system"`、`"user"`或`"assistant"`之一。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
##### 非视觉(Vision)模型
|
||||
|
||||
在OpenAI Chat API中,`name`字段使模型能够区分对话中的不同发言者。因此,`OpenAIChatWrapper`中`format`函数的策略很简单:
|
||||
|
||||
- `Msg`: 直接将带有`role`、`content`和`name`字段的字典传递给API。
|
||||
- `List`: 根据上述规则解析列表中的每个元素。
|
||||
|
||||
样例如下:
|
||||
|
||||
```python
|
||||
from agentscope.models import OpenAIChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = OpenAIChatWrapper(
|
||||
config_name="", # 我们直接初始化model wrapper,因此不需要填入config_name
|
||||
model_name="gpt-4",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg对象
|
||||
[ # Msg对象的列表
|
||||
Msg(name="Bob", content="Hi.", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{"role": "system", "name": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "assistant", "name": "Bob", "content": "Hi."},
|
||||
{"role": "assistant", "name": "Alice", "content": "Nice to meet you!"),
|
||||
]
|
||||
```
|
||||
|
||||
##### 视觉(Vision)模型
|
||||
|
||||
对支持视觉的模型而言,如果输入消息包含图像url,生成的`content`字段将是一个字典的列表,其中包含文本和图像url。
|
||||
|
||||
具体来说,如果是网络图片url,将直接传递给OpenAI Chat API,而本地图片url将被转换为base64格式。更多细节请参考[官方指南](https://platform.openai.com/docs/guides/vision)。
|
||||
|
||||
注意无效的图片url(例如`/Users/xxx/test.mp3`)将被忽略。
|
||||
|
||||
```python
|
||||
from agentscope.models import OpenAIChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = OpenAIChatWrapper(
|
||||
config_name="", # 为空,因为我们直接初始化model wrapper
|
||||
model_name="gpt-4o",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg 对象
|
||||
[ # Msg 对象的列表
|
||||
Msg(name="user", content="Describe this image", role="user", url="https://xxx.png"),
|
||||
Msg(name="user", content="And these images", role="user", url=["/Users/xxx/test.png", "/Users/xxx/test.mp3"]),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```python
|
||||
[
|
||||
{
|
||||
"role": "system",
|
||||
"name": "system",
|
||||
"content": "You are a helpful assistant"
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"name": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Describe this image"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://xxx.png"
|
||||
}
|
||||
},
|
||||
]
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"name": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "And these images"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "data:image/png;base64,YWJjZGVm..." # 对应 /Users/xxx/test.png
|
||||
}
|
||||
},
|
||||
]
|
||||
},
|
||||
]
|
||||
```
|
||||
|
||||
### `DashScopeChatWrapper`
|
||||
|
||||
`DashScopeChatWrapper`封装了DashScope聊天API,它接受消息列表作为输入。消息必须遵守以下规则:
|
||||
|
||||
- 需要`role`和`content`字段,以及一个可选的`name`字段。
|
||||
- `role`字段必须是`"user"`,`"system"`或`"assistant"`之一。
|
||||
- 如果一条信息的`role`字段是`"system"`,那么这条信息必须也只能出现在消息列表的开头。
|
||||
- `user`和`assistant`必须交替发言。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
如果第一条消息的`role`字段是`"system"`,它将被转换为一条消息,其中`role`字段为`"system"`,`content`字段为系统消息。其余的消息将被转换为一条消息,其中`role`字段为`"user"`,`content`字段为对话历史。
|
||||
|
||||
样例如下:
|
||||
|
||||
```python
|
||||
from agentscope.models import DashScopeChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = DashScopeChatWrapper(
|
||||
config_name="", # 我们直接初始化model wrapper,因此不需要填入config_name
|
||||
model_name="qwen-max",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg对象
|
||||
[ # Msg对象的列表
|
||||
Msg(name="Bob", content="Hi!", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"},
|
||||
]
|
||||
```
|
||||
|
||||
### `DashScopeMultiModalWrapper`
|
||||
|
||||
`DashScopeMultiModalWrapper`封装了多模态模型的API,它接受消息列表作为输入,并且必须遵循以下的规则(更新于2024/04/04):
|
||||
|
||||
- 每个消息是一个字段,并且包含`role`和`content`字段。
|
||||
- 其中`role`字段取值必须是`"user"`,`"system"`,`"assistant"`之一。
|
||||
- `content`字段对应的值必须是字典的列表
|
||||
- 每个字典只包含`text`,`image`或`audio`中的一个键值对
|
||||
- `text`域对应的值是一个字符串,表示文本内容
|
||||
- `image`域对应的值是一个字符串,表示图片的url
|
||||
- `audio`域对应的值是一个字符串,表示音频的url
|
||||
- `content`中可以同时包含多个key为`image`的字典或者多个key为`audio`的字典。例如
|
||||
```python
|
||||
[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"text": "What's the difference between these two pictures?"},
|
||||
{"image": "https://xxx1.png"},
|
||||
{"image": "https://xxx2.png"}
|
||||
]
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": [{"text": "The first picture is a cat, and the second picture is a dog."}]
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [{"text": "I see, thanks!"}]
|
||||
}
|
||||
]
|
||||
```
|
||||
- 如果一条信息的`role`字段是`"system"`,那么这条信息必须也只能出现在消息列表的开头。
|
||||
- 消息列表中最后一条消息的`role`字段必须是`"user"`。
|
||||
- 消息列表中`user`和`assistant`必须交替发言。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
基于上述API的限制,构建策略如下:
|
||||
- 如果输入的消息列表中第一条消息的`role`字段的值是`"system"`,它将被转换为一条系统消息,其中`role`字段为`"system"`,`content`字段为系统消息,如果输入`Msg`对象中`url`属性不为`None`,则根据其类型在`content`中增加一个键值为`"image"`或者`"audio"`的字典。
|
||||
- 其余的消息将被转换为一条消息,其中`role`字段为`"user"`,`content`字段为对话历史。并且所有`Msg`对象中`url`属性不为`None`的消息,都会根据`url`指向的文件类型在`content`中增加一个键值为`"image"`或者`"audio"`的字典。
|
||||
|
||||
样例如下:
|
||||
|
||||
```python
|
||||
from agentscope.models import DashScopeMultiModalWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = DashScopeMultiModalWrapper(
|
||||
config_name="", # 我们直接初始化model wrapper,因此不需要填入config_name
|
||||
model_name="qwen-vl-plus",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system", url="url_to_png1"), # Msg对象
|
||||
[ # Msg对象的列表
|
||||
Msg(name="Bob", content="Hi!", role="assistant", url="url_to_png2"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant", url="url_to_png3"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "system",
|
||||
"content": [
|
||||
{"text": "You are a helpful assistant"},
|
||||
{"image": "url_to_png1"}
|
||||
]
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"text": "## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"},
|
||||
{"image": "url_to_png2"},
|
||||
{"image": "url_to_png3"},
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### LiteLLMChatWrapper
|
||||
|
||||
`LiteLLMChatWrapper`封装了litellm聊天API,它接受消息列表作为输入。Litellm支持不同类型的模型,每个模型可能需要遵守不同的格式。为了简化使用,我们提供了一种与大多数模型兼容的格式。如果需要更特定的格式,您可以参考您所使用的特定模型以及[litellm](https://github.com/BerriAI/litellm)文档,来定制适合您模型的格式函数。
|
||||
- 格式化聊天历史中的所有消息,将其整合成一个以`"user"`作为`role`的单一消息
|
||||
#### 提示策略
|
||||
- 消息将包括对话历史,`user`消息由系统消息(system message)和"## Dialog History"前缀。
|
||||
|
||||
|
||||
```python
|
||||
from agentscope.models import LiteLLMChatWrapper
|
||||
|
||||
model = LiteLLMChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="gpt-3.5-turbo",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You are a helpful assistant", role="system"),
|
||||
[
|
||||
Msg("user", "What is the weather today?", role="user"),
|
||||
Msg("assistant", "It is sunny today", role="assistant"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "user",
|
||||
"content": (
|
||||
"You are a helpful assistant\n\n"
|
||||
"## Dialogue History\nuser: What is the weather today?\n"
|
||||
"assistant: It is sunny today"
|
||||
),
|
||||
},
|
||||
]
|
||||
```
|
||||
|
||||
### `OllamaChatWrapper`
|
||||
|
||||
`OllamaChatWrapper`封装了Ollama聊天API,它接受消息列表作为输入。消息必须遵守以下规则(更新于2024/03/22):
|
||||
|
||||
- 需要`role`和`content`字段,并且`role`必须是`"user"`、`"system"`或`"assistant"`之一。
|
||||
- 可以添加一个可选的`images`字段到消息中。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
给定一个消息列表,我们将按照以下规则解析每个消息:
|
||||
|
||||
- 如果输入的第一条信息的`role`字段是`"system"`,该条信息将被视为系统提示(system
|
||||
prompt),其他信息将一起组成对话历史。对话历史将添加`"## Dialogue History"`的前缀,并与
|
||||
系统提示一起组成一条`role`为`"system"`的信息。
|
||||
- 如果输入信息中的`url`字段不为`None`,则这些url将一起被置于`"images"`对应的键值中。
|
||||
|
||||
```python
|
||||
from agentscope.models import OllamaChatWrapper
|
||||
|
||||
model = OllamaChatWrapper(
|
||||
config_name="", # 我们直接初始化model wrapper,因此不需要填入config_name
|
||||
model_name="llama2",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg对象
|
||||
[ # Msg对象的列表
|
||||
Msg(name="Bob", content="Hi.", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant", url="https://example.com/image.jpg"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a helpful assistant\n\n## Dialogue History\nBob: Hi.\nAlice: Nice to meet you!",
|
||||
"images": ["https://example.com/image.jpg"]
|
||||
},
|
||||
]
|
||||
```
|
||||
|
||||
### `OllamaGenerationWrapper`
|
||||
|
||||
`OllamaGenerationWrapper`封装了Ollama生成API,它接受字符串提示作为输入,没有任何约束(更新于2024/03/22)。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
如果第一条消息的`role`字段是`"system"`,那么它将会被转化成一条系统提示。其余消息会被拼接成对话历史。
|
||||
|
||||
```python
|
||||
from agentscope.models import OllamaGenerationWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = OllamaGenerationWrapper(
|
||||
config_name="", # 我们直接初始化model wrapper,因此不需要填入config_name
|
||||
model_name="llama2",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg对象
|
||||
[ # Msg对象的列表
|
||||
Msg(name="Bob", content="Hi.", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
You are a helpful assistant
|
||||
|
||||
## Dialogue History
|
||||
Bob: Hi.
|
||||
Alice: Nice to meet you!
|
||||
```
|
||||
|
||||
### `GeminiChatWrapper`
|
||||
|
||||
`GeminiChatWrapper`封装了Gemini聊天API,它接受消息列表或字符串提示作为输入。与DashScope聊天API类似,如果我们传递消息列表,它必须遵守以下规则:
|
||||
|
||||
- 需要`role`和`parts`字段。`role`必须是`"user"`或`"model"`之一,`parts`必须是字符串列表。
|
||||
- `user`和`model`必须交替发言。
|
||||
- `user`必须在输入消息列表的开头和结尾发言。
|
||||
|
||||
当代理可能扮演多种不同角色并连续发言时,这些要求使得构建多代理对话变得困难。
|
||||
因此,我们决定在内置的`format`函数中将消息列表转换为字符串提示,并且封装在一条user信息中。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
如果第一条消息的`role`字段是`"system"`,那么它将会被转化成一条系统提示。其余消息会被拼接成对话历史。
|
||||
|
||||
**注意**Gemini Chat API中`parts`字段可以包含图片的url,由于我们将消息转换成字符串格式
|
||||
的输入,因此图片url在目前的`format`函数中是不支持的。
|
||||
我们推荐开发者可以根据需求动手定制化自己的提示。
|
||||
|
||||
```python
|
||||
from agentscope.models import GeminiChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = GeminiChatWrapper(
|
||||
config_name="", # 我们直接初始化model wrapper,因此不需要填入config_name
|
||||
model_name="gemini-pro",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg对象
|
||||
[ # Msg对象的列表
|
||||
Msg(name="Bob", content="Hi.", role="model"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="model"),
|
||||
],
|
||||
)
|
||||
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{
|
||||
"role": "user",
|
||||
"parts": [
|
||||
"You are a helpful assistant\n## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
|
||||
### `ZhipuAIChatWrapper`
|
||||
|
||||
`ZhipuAIChatWrapper`封装了ZhipuAi聊天API,它接受消息列表或字符串提示作为输入。与DashScope聊天API类似,如果我们传递消息列表,它必须遵守以下规则:
|
||||
|
||||
- 必须有 role 和 content 字段,且 role 必须是 "user"、"system" 或 "assistant" 中的一个。
|
||||
- 至少有一个 user 消息。
|
||||
|
||||
当代理可能扮演多种不同角色并连续发言时,这些要求使得构建多代理对话变得困难。
|
||||
因此,我们决定在内置的`format`函数中将消息列表转换为字符串提示,并且封装在一条user信息中。
|
||||
|
||||
#### 提示的构建策略
|
||||
|
||||
如果第一条消息的 role 字段是 "system",它将被转换为带有 role 字段为 "system" 和 content 字段为系统消息的单个消息。其余的消息会被转化为带有 role 字段为 "user" 和 content 字段为对话历史的消息。
|
||||
下面展示了一个示例:
|
||||
|
||||
```python
|
||||
from agentscope.models import ZhipuAIChatWrapper
|
||||
from agentscope.message import Msg
|
||||
|
||||
model = ZhipuAIChatWrapper(
|
||||
config_name="", # empty since we directly initialize the model wrapper
|
||||
model_name="glm-4",
|
||||
api_key="your api key",
|
||||
)
|
||||
|
||||
prompt = model.format(
|
||||
Msg("system", "You're a helpful assistant", role="system"), # Msg object
|
||||
[ # a list of Msg objects
|
||||
Msg(name="Bob", content="Hi!", role="assistant"),
|
||||
Msg(name="Alice", content="Nice to meet you!", role="assistant"),
|
||||
],
|
||||
)
|
||||
print(prompt)
|
||||
```
|
||||
|
||||
```bash
|
||||
[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "## Dialogue History\nBob: Hi!\nAlice: Nice to meet you!"},
|
||||
]
|
||||
```
|
||||
|
||||
## 关于`PromptEngine`类 (将会在未来版本弃用)
|
||||
|
||||
`PromptEngine`类提供了一种结构化的方式来合并不同的提示组件,比如指令、提示、对话历史和用户输入,以适合底层语言模型的格式。
|
||||
|
||||
### 提示工程的关键特性
|
||||
|
||||
- **模型兼容性**:可以与任何 `ModelWrapperBase` 的子类一起工作。
|
||||
- **提示类型**:支持字符串和列表风格的提示,与模型首选的输入格式保持一致。
|
||||
|
||||
### 初始化
|
||||
|
||||
当创建 `PromptEngine` 的实例时,您可以指定目标模型,以及(可选的)缩减原则、提示的最大长度、提示类型和总结模型(可以与目标模型相同)。
|
||||
|
||||
```python
|
||||
model = OpenAIChatWrapper(...)
|
||||
engine = PromptEngine(model)
|
||||
```
|
||||
|
||||
### 合并提示组件
|
||||
|
||||
`PromptEngine` 的 `join` 方法提供了一个统一的接口来处理任意数量的组件,以构建最终的提示。
|
||||
|
||||
#### 输出字符串类型提示
|
||||
|
||||
如果模型期望的是字符串类型的提示,组件会通过换行符连接:
|
||||
|
||||
```python
|
||||
system_prompt = "You're a helpful assistant."
|
||||
memory = ... # 可以是字典、列表或字符串
|
||||
hint_prompt = "Please respond in JSON format."
|
||||
|
||||
prompt = engine.join(system_prompt, memory, hint_prompt)
|
||||
# 结果将会是 ["You're a helpful assistant.", {"name": "user", "content": "What's the weather like today?"}]
|
||||
```
|
||||
|
||||
#### 输出列表类型提示
|
||||
|
||||
对于使用列表类型提示的模型,比如 OpenAI 和 Huggingface 聊天模型,组件可以转换为 `Message` 对象,其类型是字典列表:
|
||||
|
||||
```python
|
||||
system_prompt = "You're a helpful assistant."
|
||||
user_messages = [{"name": "user", "content": "What's the weather like today?"}]
|
||||
|
||||
prompt = engine.join(system_prompt, user_messages)
|
||||
# 结果将会是: [{"role": "assistant", "content": "You're a helpful assistant."}, {"name": "user", "content": "What's the weather like today?"}]
|
||||
```
|
||||
|
||||
#### 动态格式化提示
|
||||
|
||||
`PromptEngine` 支持使用 `format_map` 参数动态提示,允许您灵活地将各种变量注入到不同场景的提示组件中:
|
||||
|
||||
```python
|
||||
variables = {"location": "London"}
|
||||
hint_prompt = "Find the weather in {location}."
|
||||
|
||||
prompt = engine.join(system_prompt, user_input, hint_prompt, format_map=variables)
|
||||
```
|
||||
|
||||
[[返回顶端]](#206-prompt-zh)
|
||||
174
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/207-monitor.md
Normal file
174
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/207-monitor.md
Normal file
@@ -0,0 +1,174 @@
|
||||
(207-monitor-zh)=
|
||||
|
||||
# 监控器
|
||||
|
||||
在多智能体应用程序中,特别是那些依赖外部模型 API 的应用程序,监控使用情况和成本以防止过度使用并确保遵守速率限制是至关重要的。`MonitorBase` 类及其实现 `SqliteMonitor` 提供了一种追踪和调节这些 API 在您的应用中使用情况的方法。在本教程中,您将学习如何使用它们来监控 API 调用。
|
||||
|
||||
## 理解 AgentScope 中的监控器
|
||||
|
||||
`MonitorBase` 类作为一个接口,用于设置一个监控系统,跟踪各种度量指标,特别是关注 API 使用情况。它定义了一些方法,使得可以注册、检查、更新和管理与 API 调用相关的度量指标。
|
||||
|
||||
以下是 `MonitorBase` 的关键方法:
|
||||
|
||||
- **`register`**:初始化用于跟踪的度量指标,例如进行的 API 调用次数,以及可选的配额用于执行限制。
|
||||
- **`exists`**:检查是否已经跟踪了某个度量指标。
|
||||
- **`add`**:将度量指标增加指定的值,用于每次 API 调用后计数。
|
||||
- **`update`**:一次更新多个度量指标,适用于批量更新。
|
||||
- **`clear`**:将度量指标重置为零,适用于配额周期重置。
|
||||
- **`remove`**:从监控中移除一个度量指标。
|
||||
- **`get_value`**:检索特定度量指标的当前值。
|
||||
- **`get_unit`**:获取与度量指标相关联的单元(例如,“调用”)。
|
||||
- **`get_quota`**:获取允许的 API 调用的最大值。
|
||||
- **`set_quota`**:调整度量指标的配额,如果 API 使用条款变更。
|
||||
- **`get_metric`**:返回有关特定度量指标的详细信息。
|
||||
- **`get_metrics`**:检索所有跟踪度量指标的信息,可以基于度量指标名称可选地进行过滤。
|
||||
- **`register_budget`**:为某个 API 调用设置预算,将初始化一系列用于计算成本的度量指标。
|
||||
|
||||
## 使用监控器
|
||||
|
||||
### 获取监控器实例
|
||||
|
||||
从 `MonitorFactory` 获取监控器实例开始监控,注意多次调用 `get_monitor` 方法将返回同一个监控器实例。
|
||||
|
||||
```python
|
||||
# 确保在这之前你已经调用了agentscope.init(...)
|
||||
monitor = MonitorFactory.get_monitor()
|
||||
```
|
||||
|
||||
目前上述代码将会返回一个 `SqliteMonitor` 实例,该实例在 `agentscope.init` 中初始化。
|
||||
`SqliteMonitor` 是一个基于 Sqlite3 的 `MonitorBase` 实现,也是当前的默认 Monitor。
|
||||
|
||||
如果不需要使用 Monitor 的相关功能,可以通过向 `agentscope.init` 中传入 `use_monitor=False` 来关闭 monitor 组件。在这种情况下,`MonitorFactory.get_monitor` 将返回一个 `DummyMonitor` 实例,该实例对外接口与 `SqliteMonitor` 完全相同,但内部不会执行任何操作。
|
||||
|
||||
### 基本使用
|
||||
|
||||
#### 注册 API 使用度量指标
|
||||
|
||||
注册一个新的度量指标以开始监控 token 数量:
|
||||
|
||||
```python
|
||||
monitor.register("token_num", metric_unit="token", quota=1000)
|
||||
```
|
||||
|
||||
#### 更新度量指标
|
||||
|
||||
增加 `token_num` 度量指标:
|
||||
|
||||
```python
|
||||
monitor.add("token_num", 20)
|
||||
```
|
||||
|
||||
#### 处理配额
|
||||
|
||||
如果 API 调用次数超出了配额,将抛出 `QuotaExceededError`:
|
||||
|
||||
```python
|
||||
try:
|
||||
monitor.add("api_calls", amount)
|
||||
except QuotaExceededError as e:
|
||||
# 处理超出的配额,例如,通过暂停API调用
|
||||
print(e.message)
|
||||
```
|
||||
|
||||
#### 检索度量指标
|
||||
|
||||
获取当前使用的 token 数量:
|
||||
|
||||
```python
|
||||
token_num_used = monitor.get_value("token_num")
|
||||
```
|
||||
|
||||
#### 重置和移除度量指标
|
||||
|
||||
在新的周期开始时重置 token 计数:
|
||||
|
||||
```python
|
||||
monitor.clear("token_num")
|
||||
```
|
||||
|
||||
如果不再需要,则移除度量指标:
|
||||
|
||||
```python
|
||||
monitor.remove("token_num")
|
||||
```
|
||||
|
||||
### 进阶使用
|
||||
|
||||
> 这里的功能仍在开发中,接口可能会继续变化。
|
||||
|
||||
#### 使用 `prefix` 来区分度量指标
|
||||
|
||||
假设您有多个智能体/模型使用相同的 API 调用,但您想分别计算它们的 token 使用量,您可以在原始度量指标名称前添加一个唯一的前缀 `prefix`,`get_full_name` 函数提供了这样的功能。
|
||||
|
||||
例如,如果 model_A 和 model_B 都使用 OpenAI API,您可以通过以下代码注册这些度量指标。
|
||||
|
||||
```python
|
||||
from agentscope.utils.monitor import get_full_name
|
||||
|
||||
...
|
||||
|
||||
# 在model_A中
|
||||
monitor.register(get_full_name('prompt_tokens', 'model_A'))
|
||||
monitor.register(get_full_name('completion_tokens', 'model_A'))
|
||||
|
||||
# 在model_B中
|
||||
monitor.register(get_full_name('prompt_tokens', 'model_B'))
|
||||
monitor.register(get_full_name('completion_tokens', 'model_B'))
|
||||
```
|
||||
|
||||
更新这些度量指标,只需使用 `update` 方法。
|
||||
|
||||
```python
|
||||
# 在model_A中
|
||||
monitor.update(openai_response.usage.model_dump(), prefix='model_A')
|
||||
|
||||
# 在model_B中
|
||||
monitor.update(openai_response.usage.model_dump(), prefix='model_B')
|
||||
```
|
||||
|
||||
获取特定模型的度量指标,请使用 `get_metrics` 方法。
|
||||
|
||||
```python
|
||||
# 获取model_A的度量指标
|
||||
model_A_metrics = monitor.get_metrics('model_A')
|
||||
|
||||
# 获取model_B的度量指标
|
||||
model_B_metrics = monitor.get_metrics('model_B')
|
||||
```
|
||||
|
||||
#### 为 API 注册预算
|
||||
|
||||
当前,监控器已经支持根据各种度量指标自动计算 API 调用的成本,您可以直接为模型设置预算以避免超出配额。
|
||||
|
||||
假设您正在使用 `gpt-4-turbo`,您的预算是10美元,您可以使用以下代码。
|
||||
|
||||
```python
|
||||
model_name = 'gpt-4-turbo'
|
||||
monitor.register_budget(model_name=model_name, value=10, prefix=model_name)
|
||||
```
|
||||
|
||||
使用 `prefix` 为使用相同 API 的不同模型设置预算。
|
||||
|
||||
```python
|
||||
model_name = 'gpt-4-turbo'
|
||||
# 在model_A中
|
||||
monitor.register_budget(model_name=model_name, value=10, prefix=f'model_A.{model_name}')
|
||||
|
||||
# 在model_B中
|
||||
monitor.register_budget(model_name=model_name, value=10, prefix=f'model_B.{model_name}')
|
||||
```
|
||||
|
||||
`register_budget` 将自动注册计算总成本所需的度量指标,当这些度量指标更新时计算总成本,并在超出预算时抛出 `QuotaExceededError`。
|
||||
|
||||
```python
|
||||
model_name = 'gpt-4-turbo'
|
||||
try:
|
||||
monitor.update(openai_response.usage.model_dump(), prefix=model_name)
|
||||
except QuotaExceededError as e:
|
||||
# 处理超出的配额
|
||||
print(e.message)
|
||||
```
|
||||
|
||||
> **注意:** 此功能仍在实验阶段,只支持一些特定的 API,这些 API 已在 `agentscope.utils.monitor._get_pricing` 中列出。
|
||||
|
||||
[[Return to the top]](#207-monitor-zh)
|
||||
@@ -0,0 +1,274 @@
|
||||
(208-distribute-zh)=
|
||||
|
||||
# 分布式
|
||||
|
||||
AgentScope实现了基于Actor模式的智能体分布式部署和并行优化,并提供以下的特点:
|
||||
|
||||
- **自动并行优化**:运行时自动实现应用并行优化,无需额外优化成本;
|
||||
- **应用编写中心化**:无需分布式背景知识,轻松编排分布式应用程序流程;
|
||||
- **零成本自动迁移**:中心化的Multi-Agent应用可以轻松转化成分布式模式
|
||||
|
||||
本教程将详细介绍AgentScope分布式的实现原理和使用方法。
|
||||
|
||||
## 使用方法
|
||||
|
||||
AgentScope中,我们将运行应用流程的进程称为**主进程 (Main Process)**,而所有的智能体都会运行在额外的 **智能体服务器进程 (Agent Server Process)** 中。
|
||||
根据主进程域智能体服务器进程之间的关系,AgentScope 为每个 Agent 提供了两种启动模式:**子进程模式 (Child)** 和 **独立进程模式 (Indpendent)**。
|
||||
子进程模式中,开发者可以从主进程中启动所有的智能体服务器进程,而独立进程模式中,智能体服务器进程相对主进程来说是独立的,需要在对应的机器上启动智能体服务器进程。
|
||||
|
||||
上述概念有些复杂,但是不用担心,对于应用开发者而言,仅需将已有的智能体转化为对应的分布式版本,其余操作都和正常的单机版本完全一致。
|
||||
|
||||
### 步骤1: 转化为分布式版本
|
||||
|
||||
AgentScope 中所有智能体都可以通过 {func}`to_dist<agentscope.agents.AgentBase.to_dist>` 方法转化为对应的分布式版本。
|
||||
但需要注意,你的智能体必须继承自 {class}`agentscope.agents.AgentBase<agentscope.agents.AgentBase>` 类,因为是 `AgentBase` 提供了 `to_dist` 方法。
|
||||
|
||||
假设有两个智能体类`AgentA`和`AgentB`,它们都继承自 `AgentBase`。
|
||||
|
||||
```python
|
||||
a = AgentA(
|
||||
name="A"
|
||||
# ...
|
||||
)
|
||||
b = AgentB(
|
||||
name="B"
|
||||
# ...
|
||||
)
|
||||
```
|
||||
|
||||
接下来我们将介绍如何将智能体转化到两种分布式模式。
|
||||
|
||||
#### 子进程模式
|
||||
|
||||
要使用该模式,你只需要调用各智能体的 `to_dist()` 方法,并且不需要提供任何参数。
|
||||
AgentScope 会自动帮你从主进程中启动智能体服务器进程并将智能体部署到对应的子进程上。
|
||||
|
||||
```python
|
||||
# Subprocess mode
|
||||
a = AgentA(
|
||||
name="A"
|
||||
# ...
|
||||
).to_dist()
|
||||
b = AgentB(
|
||||
name="B"
|
||||
# ...
|
||||
).to_dist()
|
||||
```
|
||||
|
||||
#### 独立进程模式
|
||||
|
||||
在独立进程模式中,需要首先在目标机器上启动智能体服务器进程,启动时需要提供该服务器能够使用的模型的配置信息,以及服务器的 IP 和端口号。
|
||||
例如想要将两个智能体服务进程部署在 IP 分别为 `ip_a` 和 `ip_b` 的机器上(假设这两台机器分别为`Machine1` 和 `Machine2`)。
|
||||
你可以在 `Machine1` 上运行如下代码。在运行之前请确保该机器能够正确访问到应用中所使用的所有模型。具体来讲,需要将用到的所有模型的配置信息放置在 `model_config_path_a` 文件中,并检查API key 等环境变量是否正确设置,模型配置文件样例可参考 `examples/model_configs_template`。
|
||||
|
||||
```python
|
||||
# import some packages
|
||||
|
||||
# register models which can be used in the server
|
||||
agentscope.init(
|
||||
model_configs=model_config_path_a,
|
||||
)
|
||||
# Create an agent service process
|
||||
server = RpcAgentServerLauncher(
|
||||
host="ip_a",
|
||||
port=12001, # choose an available port
|
||||
)
|
||||
|
||||
# Start the service
|
||||
server.launch()
|
||||
server.wait_until_terminate()
|
||||
```
|
||||
|
||||
> 为了进一步简化使用,可以在命令行中输入如下指令来代替上述代码:
|
||||
>
|
||||
> ```shell
|
||||
> as_server --host ip_a --port 12001 --model-config-path model_config_path_a
|
||||
> ```
|
||||
|
||||
在 `Machine2` 上运行如下代码,这里同样要确保已经将模型配置文件放置在 `model_config_path_b` 位置并设置环境变量,从而确保运行在该机器上的 Agent 能够正常访问到模型。
|
||||
|
||||
```python
|
||||
# import some packages
|
||||
|
||||
# register models which can be used in the server
|
||||
agentscope.init(
|
||||
model_configs=model_config_path_b,
|
||||
)
|
||||
# Create an agent service process
|
||||
server = RpcAgentServerLauncher(
|
||||
host="ip_b",
|
||||
port=12002, # choose an available port
|
||||
)
|
||||
|
||||
# Start the service
|
||||
server.launch()
|
||||
server.wait_until_terminate()
|
||||
```
|
||||
|
||||
> 这里也同样可以用如下指令来代替上面的代码。
|
||||
>
|
||||
> ```shell
|
||||
> as_server --host ip_b --port 12002 --model-config-path model_config_path_b
|
||||
> ```
|
||||
|
||||
接下来,就可以使用如下代码从主进程中连接这两个智能体服务器进程。
|
||||
|
||||
```python
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
).to_dist(
|
||||
host="ip_a",
|
||||
port=12001,
|
||||
)
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
).to_dist(
|
||||
host="ip_b",
|
||||
port=12002,
|
||||
)
|
||||
```
|
||||
|
||||
上述代码将会把 `AgentA` 部署到 `Machine1` 的智能体服务器进程上,并将 `AgentB` 部署到 `Machine2` 的智能体服务器进程上。
|
||||
开发者在这之后只需要用中心化的方法编排各智能体的交互逻辑即可。
|
||||
|
||||
#### `to_dist` 进阶用法
|
||||
|
||||
上面介绍的案例都是将一个已经初始化的 Agent 通过 {func}`to_dist<agentscope.agents.AgentBase.to_dist>` 方法转化为其分布式版本,相当于要执行两次初始化操作,一次在主进程中,一次在智能体进程中。如果 Agent 的初始化过程耗时较长,直接使用 `to_dist` 方法会严重影响运行效率。为此 AgentScope 也提供了在初始化 Agent 实例的同时将其转化为其分布式版本的方法,即在原 Agent 实例初始化时传入 `to_dist` 参数。
|
||||
|
||||
子进程模式下,只需要在 Agent 初始化函数中传入 `to_dist=True` 即可:
|
||||
|
||||
```python
|
||||
# Child Process mode
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
to_dist=True
|
||||
)
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
to_dist=True
|
||||
)
|
||||
```
|
||||
|
||||
独立进程模式下, 则需要将原来 `to_dist()` 函数的参数以 {class}`DistConf<agentscope.agents.DistConf>` 实例的形式传入 Agent 初始化函数的 `to_dist` 域:
|
||||
|
||||
```python
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
to_dist=DistConf(
|
||||
host="ip_a",
|
||||
port=12001,
|
||||
),
|
||||
)
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
to_dist=DistConf(
|
||||
host="ip_b",
|
||||
port=12002,
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
相较于原有的 `to_dist()` 函数调用,该方法只会在智能体进程中初始化一次 Agent,避免了重复初始化现象。
|
||||
|
||||
### 步骤2: 编排分布式应用流程
|
||||
|
||||
在AgentScope中,分布式应用流程的编排和非分布式的程序完全一致,开发者可以用中心化的方式编写全部应用流程。
|
||||
同时,AgentScope允许本地和分布式部署的智能体混合使用,开发者不用特意区分哪些智能体是本地的,哪些是分布式部署的。
|
||||
|
||||
以下是不同模式下实现两个智能体之间进行对话的全部代码,对比可见,AgentScope支持零代价将分布式应用流程从中心化向分布式迁移。
|
||||
|
||||
- 智能体全部中心化:
|
||||
|
||||
```python
|
||||
# 创建智能体对象
|
||||
a = AgentA(
|
||||
name="A",
|
||||
# ...
|
||||
)
|
||||
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
)
|
||||
|
||||
# 应用流程编排
|
||||
x = None
|
||||
while x is None or x.content == "exit":
|
||||
x = a(x)
|
||||
x = b(x)
|
||||
```
|
||||
|
||||
- 智能体分布式部署
|
||||
- `AgentA` 使用子进程模式部署
|
||||
- `AgentB` 使用独立进程模式部署
|
||||
|
||||
```python
|
||||
# 创建智能体对象
|
||||
a = AgentA(
|
||||
name="A"
|
||||
# ...
|
||||
).to_dist()
|
||||
|
||||
b = AgentB(
|
||||
name="B",
|
||||
# ...
|
||||
).to_dist(
|
||||
host="ip_b",
|
||||
port=12002,
|
||||
)
|
||||
|
||||
# 应用流程编排
|
||||
x = None
|
||||
while x is None or x.content == "exit":
|
||||
x = a(x)
|
||||
x = b(x)
|
||||
```
|
||||
|
||||
### 实现原理
|
||||
|
||||
#### Actor模式
|
||||
|
||||
[Actor模式](https://en.wikipedia.org/wiki/Actor_model)是大规模分布式系统中广泛使用的编程范式,同时也被应用于AgentScope平台的分布式设计中。
|
||||
在Actor模型中,一个actor是一个实体,它封装了自己的状态,并且仅通过消息传递与其他actor通信。
|
||||
|
||||
在AgentScope的分布式模式中,每个Agent都是一个Actor,并通过消息与其他Agent交互。消息的流转暗示了Agent的执行顺序。每个Agent都有一个`reply`方法,它消费一条消息并生成另一条消息,生成的消息可以发送给其他 Agent。例如,下面的图表显示了多个Agent的工作流程。`A`~`F`都是Agent,箭头代表消息。
|
||||
|
||||
```{mermaid}
|
||||
graph LR;
|
||||
A-->B
|
||||
A-->C
|
||||
B-->D
|
||||
C-->D
|
||||
E-->F
|
||||
D-->F
|
||||
```
|
||||
|
||||
其中,`B`和`C`可以在接收到来自`A`的消息后同时启动执行,而`E`可以立即运行,无需等待`A`、`B`、`C`和`D`。
|
||||
通过将每个Agent实现为一个Actor, Agent将自动等待其输入Msg准备好后开始执行`reply`方法,并且如果多个 Agent 的输入消息准备就绪,它们也可以同时自动执行`reply`,这避免了复杂的并行控制。
|
||||
|
||||
#### Placeholder
|
||||
|
||||
同时,为了支持中心化的应用编排,AgentScope 引入了 {class}`Placeholder<agentscope.message.PlaceholderMessage>` 这一概念。
|
||||
Placeholder 可以理解为消息的指针,指向消息真正产生的位置,其对外接口与传统模式中的消息完全一致,因此可以按照传统中心化的消息使用方式编排应用。
|
||||
Placeholder 内部包含了该消息产生方的联络方法,可以通过网络获取到被指向消息的真正值。
|
||||
每个分布式部署的 Agent 在收到其他 Agent 发来的消息时都会立即返回一个 Placeholder,从而避免阻塞请求发起方。
|
||||
而请求发起方可以借助返回的 Placeholder 在真正需要消息内容时再去向原 Agent 发起请求,请求发起方甚至可以将 Placeholder 发送给其他 Agent 让其他 Agent 代为获取消息内容,从而减少消息真实内容的不必要转发。
|
||||
|
||||
关于更加详细的技术实现方案,请参考我们的[论文](https://arxiv.org/abs/2402.14034)。
|
||||
|
||||
#### Agent Server
|
||||
|
||||
Agent Server 也就是智能体服务器。在 AgentScope 中,Agent Server 提供了一个让不同 Agent 实例运行的平台。多个不同类型的 Agent 可以运行在同一个 Agent Server 中并保持独立的记忆以及其他本地状态信息,但是他们将共享同一份计算资源。
|
||||
|
||||
在安装 AgentScope 的分布式版本后就可以通过 `as_server` 命令来启动 Agent Server,具体的启动参数在 {func}`as_server<agentscope.server.launcher.as_server>` 函数文档中可以找到。
|
||||
|
||||
只要没有对代码进行修改,一个已经启动的 Agent Server 可以为多个主流程提供服务。
|
||||
这意味着在运行多个应用时,只需要在第一次运行前启动 Agent Server,后续这些 Agent Server 进程就可以持续复用。
|
||||
|
||||
[[回到顶部]](#208-distribute-zh)
|
||||
150
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/209-gui.md
Normal file
150
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/209-gui.md
Normal file
@@ -0,0 +1,150 @@
|
||||
(209-gui-zh)=
|
||||
|
||||
# AgentScope Studio
|
||||
|
||||
AgentScope Studio 是一个开源的 Web UI 工具包,用于构建和监控多智能体应用程序。它提供以下功能:
|
||||
|
||||
- **Dashboard**:一个用户友好的界面,可以在其中监视正在运行的应用程序,并查看运行历史。
|
||||
- **Workstation**:一个强大的界面,可通过**拖拽**的方式构建多智能体应用程序。
|
||||
- **Gallery**:即将推出!
|
||||
- **Server Management**:即将推出!
|
||||
|
||||
|
||||
## 启动 AgentScope Studio
|
||||
|
||||
要启动 Studio,请首先确保已安装了最新版本的 AgentScope。然后,可以通过运行以下 Python 代码:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.studio.init()
|
||||
```
|
||||
|
||||
或者,可以在终端中运行以下命令:
|
||||
|
||||
```bash
|
||||
as_studio
|
||||
```
|
||||
|
||||
之后,可以在 `http://127.0.0.1:5000` 访问 AgentScope Studio。
|
||||
|
||||
当然,AgentScope Studio的 IP 地址和端口都可以更改,并且可以通过以下方式引入应用的运行记录:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.studio.init(
|
||||
host="127.0.0.1", # AgentScope Studio 的 IP 地址
|
||||
port=5000, # AgentScope Studio 的端口号
|
||||
run_dirs = [ # 您的运行历史目录
|
||||
"xxx/xxx/runs",
|
||||
"xxx/xxx/runs"
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
## Dashboard
|
||||
|
||||
Dashboard 是一个 Web 界面,用于监视正在运行的应用程序,并查看运行历史。
|
||||
|
||||
## 注意
|
||||
|
||||
目前,Dashboard 存在以下限制,我们正在努力改进。欢迎任何反馈、贡献或建议!
|
||||
|
||||
- 运行的应用程序和 AgentScope Studio 必须在同一台机器上运行,以保持 URL 和路径的一致性。如果需要在其它机器上访问 AgentScope Studio,可以尝试通过在远程机器上运行以下命令将端口转发到远程机器:
|
||||
|
||||
```bash
|
||||
# 假设 AgentScope 在 {as_host}:{as_port} 上运行,远程机器的端口为 {remote_machine_port}
|
||||
ssh -L {remote_machine_port}:{as_host}:{as_port} [{user_name}@]{as_host}
|
||||
```
|
||||
|
||||
- 对于分布式应用程序,支持单机多进程模式,但尚不支持多机多进程模式。
|
||||
|
||||
### 注册应用程序
|
||||
|
||||
启动 AgentScope Studio 后,可以通过指定 `agentscope.init()` 函数中的 `studio_url` 参数来注册应用程序:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
# ...
|
||||
project="xxx",
|
||||
name="xxx",
|
||||
studio_url="http://127.0.0.1:5000" # AgentScope Studio 的 URL
|
||||
)
|
||||
```
|
||||
|
||||
注册后,可以在 Dashboard 中查看正在运行的应用程序。为了区分不同的应用程序,可以指定应用程序的 `project` 和 `name`。
|
||||
|
||||
> 注意:一旦注册了应用程序,`agentscope.agents.UserAgent` 中的用户输入就会转移到 AgentScope Studio 的 Dashboard 中,您可以在 Dashboard 中输入。
|
||||
|
||||
### 引入运行历史
|
||||
|
||||
在 AgentScope 中,运行历史默认会保存在 `./runs` 目录下。为了引入运行历史,可以在 `agentscope.studio.init()` 函数中指定 `run_dirs` 参数:
|
||||
|
||||
```python
|
||||
import agentscope
|
||||
|
||||
agentscope.studio.init(
|
||||
run_dirs = ["xxx/runs",]
|
||||
)
|
||||
```
|
||||
|
||||
## About Workstation
|
||||
|
||||
Workstation 是为零代码用户设计的,可以通过**拖拽**的方式构建多智能体应用程序。
|
||||
|
||||
> 注意:Workstation 仍处于快速迭代阶段,界面和功能可能会有所变化。欢迎任何反馈、贡献或建议!
|
||||
|
||||
### 快速使用
|
||||
|
||||
AgentScope Studio中,拖过点击 workstation 图标进入 Workstation 界面。
|
||||
它由侧边栏、工作区和顶部工具栏组成。
|
||||
|
||||
- **侧边栏**:提供预构建的示例,帮助开发者熟悉工作站,并提供可拖动的组件来构建应用程序。
|
||||
- **工作区**:主要工作区,可以在其中拖放组件来构建应用程序。
|
||||
- **顶部工具栏**:包含导出、加载、检查和运行等功能。
|
||||
|
||||
<h1 align="center">
|
||||
<img src="https://img.alicdn.com/imgextra/i1/O1CN01RXAVVn1zUtjXVvuqS_!!6000000006718-1-tps-3116-1852.gif" width="600" alt="agentscope-logo">
|
||||
</h1>
|
||||
|
||||
#### 内置样例
|
||||
|
||||
对于初学者,建议从预构建的示例开始,可以直接点击示例以将其导入到中央工作区。或者,为了获得更有结构化的学习体验,您可以选择跟随每个示例链接的教程。这些教程将逐步引导您如何在 AgentScope Workstation 上构建每个多智能体应用程序。
|
||||
|
||||
#### 构建应用程序
|
||||
|
||||
要构建应用程序,请按照以下步骤操作:
|
||||
- **选择和拖动组件**:从侧边栏中选择您想要的组件,然后将其拖放到中央工作区。
|
||||
- **连接节点**:大多数节点都有输入和输出点。单击一个组件的输出点,然后将其拖动到另一个组件的输入点,以创建消息流管道。这个过程允许不同的节点传递消息。
|
||||
- **配置节点**:将节点拖放到工作区后,单击任何节点以填写其配置设置。可以自定义提示、参数和其他属性。
|
||||
|
||||
#### 运行应用程序
|
||||
|
||||
构建应用程序后,单击“运行”按钮。
|
||||
在运行之前,Workstation 将检查您的应用程序是否存在任何错误。如果有任何错误,您将被提示在继续之前纠正它们。
|
||||
之后,应用程序将在与 AgentScope Studio 相同的 Python 环境中执行,并且可以在 Dashboard 中找到它。
|
||||
|
||||
#### 导入/导出应用程序
|
||||
|
||||
AgentScope Workstation 支持导入和导出应用程序。
|
||||
单击“导出 HTML”或“导出 Python”按钮,以生成可以分发给社区或本地保存的代码。
|
||||
如果要将导出的代码转换为 Python,请按以下步骤将 JSON 配置编译为 Python 代码:
|
||||
|
||||
```bash
|
||||
as_workflow config.json --compile ${YOUR_PYTHON_SCRIPT_NAME}.py
|
||||
```
|
||||
|
||||
需要进一步编辑应用程序,只需单击“导入 HTML”按钮,将之前导出的 HTML 代码上传回 AgentScope Workstation。
|
||||
|
||||
#### 检查应用程序
|
||||
|
||||
构建应用程序后,可以单击“检查”按钮来验证应用程序结构的正确性。将执行以下检查规则,不用担心这些规则过于复杂,Workstation 将会自动执行检查并给出提示。
|
||||
|
||||
- Model 和 Agent 的存在:每个应用程序必须包含至少一个 model 节点和一个 agent 节点。
|
||||
- 单连接策略:每个组件的输入不应该有多个连接。
|
||||
- 必填字段验证:所有必填字段必须填充,以确保每个节点具有正确运行所需的参数。
|
||||
- 一致的配置命名:Agent 节点使用的“Model config name”必须对应于 Model 节点中定义的“Config Name”。
|
||||
- 节点嵌套正确:ReActAgent 等节点应仅包含工具节点。类似地,IfElsePipeline 等 Pipeline 节点应包含正确数量的元素(不超过 2 个),而 ForLoopPipeline、WhileLoopPipeline 和 MsgHub 应遵循一个元素的规则(必须是 SequentialPipeline 作为子节点)。
|
||||
@@ -0,0 +1,419 @@
|
||||
(209-prompt-opt-zh)=
|
||||
|
||||
# 系统提示优化
|
||||
|
||||
AgentScope实现了对智能体System Prompt进行优化的模块。
|
||||
|
||||
## 背景
|
||||
|
||||
在智能体系统中,System Prompt的设计对于产生高质量的智能体响应至关重要。System Prompt向智能体提供了执行任务的环境、角色、能力和约束等背景描述。然而,优化System Prompt的过程通常充满挑战,这主要是由于以下几点:
|
||||
|
||||
1. **针对性**:一个良好的 System Prompt 应该针对性强,能够清晰地引导智能体在特定任务中更好地表现其能力和限制。
|
||||
2. **合理性**:为智能体定制的 System Prompt 应该合适且逻辑清晰,以保证智能体的响应不偏离预定行为。
|
||||
3. **多样性**:智能体可能需要参与多种场景的任务,这就要求 System Prompt 具备灵活调整以适应各种不同背景的能力。
|
||||
4. **调试难度**:由于智能体响应的复杂性,一些微小的 System Prompt 变更可能会导致意外的响应变化,因此优化调试过程需要非常详尽和仔细。
|
||||
|
||||
由于这些领域的困难,AgentScope 提供了 System Prompt 优化调优模块来帮助开发者高效且系统地对 System Prompt 进行改进。借助这些模块可以方便用户对自己 Agent 的 System Prompt 进行调试优化,提升 System Prompt 的有效性。
|
||||
具体包括:
|
||||
|
||||
- **System Prompt Generator**: 根据用户的需求生成对应的 system prompt
|
||||
- **System Prompt Comparer**: 在不同的查询或者对话过程中比较不同的 system prompt 的效果
|
||||
- **System Prompt Optimizer**: 根据对话历史进行反思和总结,从而进一步提升 system prompt
|
||||
|
||||
## 目录
|
||||
|
||||
- [System Prompt Generator](#system-prompt-generator)
|
||||
- [初始化](#初始化)
|
||||
- [生成 System Prompt](#生成-system-prompt)
|
||||
- [使用 In Context Learning 生成](#使用-in-context-learning-生成)
|
||||
- [System Prompt Comparer](#system-prompt-comparer)
|
||||
- [初始化](#初始化-1)
|
||||
- [System Prompt Optimizer](#system-prompt-optimizer)
|
||||
|
||||
|
||||
## System Prompt Generator
|
||||
|
||||
System prompt generator 使用一个 meta prompt 来引导 LLM 根据用户输入生成对应的 system prompt,并允许开发者使用内置或自己的样例进行 In Context Learning (ICL)。
|
||||
|
||||
具体包括 `EnglishSystemPromptGenerator` 和 `ChineseSystemPromptGenerator` 两个模块,分别用于英文和中文的系统提示生成。它们唯一的区别在于内置的 prompt 语言不同,其他功能完全一致。
|
||||
下面以 `ChineseSystemPromptGenerator` 为例,介绍如何使用 system prompt generator。
|
||||
|
||||
### 初始化
|
||||
|
||||
为了初始化生成器,首先需要在 `agentscope.init` 函数中注册模型配置。
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
prompt_generator = EnglishSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4"
|
||||
)
|
||||
```
|
||||
|
||||
生成器将使用内置的 meta prompt 来引导 LLM 生成 system prompt。
|
||||
开发者也可以使用自己的 meta prompt,如下所示:
|
||||
|
||||
```python
|
||||
from agentscope.prompt import EnglishSystemPromptGenerator
|
||||
|
||||
your_meta_prompt = "You are an expert prompt engineer adept at writing and optimizing system prompts. Your task is to ..."
|
||||
|
||||
prompt_gen_method = EnglishSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4",
|
||||
meta_prompt=your_meta_prompt
|
||||
)
|
||||
```
|
||||
|
||||
欢迎开发者尝试不同的优化方法。AgentScope 提供了相应的 `SystemPromptGeneratorBase` 模块,用以实现自己的优化模块。
|
||||
|
||||
```python
|
||||
from agentscope.prompt import SystemPromptGeneratorBase
|
||||
|
||||
class MySystemPromptGenerator(SystemPromptGeneratorBase):
|
||||
def __init__(
|
||||
self,
|
||||
model_config_name: str,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(
|
||||
model_config_name=model_config_name,
|
||||
**kwargs
|
||||
)
|
||||
```
|
||||
|
||||
### 生成 System Prompt
|
||||
|
||||
调用 `generate` 函数生成 system prompt,这里的输入可以是一个需求,或者是想要优化的 system prompt。
|
||||
|
||||
```python
|
||||
from agentscope.prompt import ChineseSystemPromptGenerator
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
prompt_generator = ChineseSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4"
|
||||
)
|
||||
|
||||
generated_system_prompt = prompt_generator.generate(
|
||||
user_input="生成一个小红书营销专家的系统提示,专门负责推销书籍。"
|
||||
)
|
||||
|
||||
print(generated_system_prompt)
|
||||
```
|
||||
|
||||
执行上述代码后,可以获得如下的 system prompt:
|
||||
|
||||
```
|
||||
你是一个小红书营销专家AI,你的主要任务是推销各类书籍。你拥有丰富的营销策略知识和对小红书用户群体的深入理解,能够创造性地进行书籍推广。你的技能包括但不限于:制定营销计划,写吸引人的广告文案,分析用户反馈,以及对营销效果进行评估和优化。你无法直接进行实时搜索或交互,但可以利用你的知识库和经验来提供最佳的营销策略。你的目标是提高书籍的销售量和提升品牌形象。
|
||||
```
|
||||
|
||||
看起来这个 system prompt 已经有一个雏形了,但是还有很多地方可以优化。接下来我们将介绍如何使用 In Context Learning (ICL) 来优化 system prompt。
|
||||
|
||||
### 使用 In Context Learning 生成
|
||||
|
||||
AgentScope 的 system prompt generator 模块支持在系统提示生成中使用 In Context Learning。
|
||||
它内置了一些样例,并且允许用户提供自己的样例来优化系统提示。
|
||||
|
||||
为了使用样例,AgentScope 提供了以下参数:
|
||||
|
||||
- `example_num`: 附加到 meta prompt 的样例数量,默认为 0
|
||||
- `example_selection_strategy`: 选择样例的策略,可选 "random" 和 "similarity"。
|
||||
- `example_list`: 一个样例的列表,其中每个样例必须是一个包含 "user_prompt" 和 "opt_prompt" 键的字典。如果未指定,则将使用内置的样例列表。
|
||||
|
||||
```python
|
||||
from agentscope.prompt import ChineseSystemPromptGenerator
|
||||
|
||||
generator = ChineseSystemPromptGenerator(
|
||||
model_config_name="{your_config_name}",
|
||||
|
||||
example_num=3,
|
||||
example_selection_strategy="random",
|
||||
example_list= [ # 或者可以使用内置的样例列表
|
||||
{
|
||||
"user_prompt": "生成一个 ...",
|
||||
"opt_prompt": "你是一个AI助手 ..."
|
||||
},
|
||||
# ...
|
||||
],
|
||||
)
|
||||
```
|
||||
|
||||
注意,如果选择 `"similarity"` 作为样例选择策略,可以在 `embed_model_config_name` 或 `local_embedding_model` 参数中指定一个 embedding 模型。
|
||||
它们的区别在于:
|
||||
|
||||
- `embed_model_config_name`: 首先在 `agentscope.init` 中注册 embedding 模型,并在此参数中指定模型配置名称。
|
||||
- `local_embedding_model`:或者,可以使用 `sentence_transformers.SentenceTransformer` 库支持的本地小型嵌入模型。
|
||||
|
||||
如果上述两个参数都没有指定,AgentScope 将默认使用 `"sentence-transformers/all-mpnet-base-v2"` 模型,该模型足够小,可以在 CPU 上运行。
|
||||
一个简单利用 In Context Learning 的示例如下:
|
||||
|
||||
```python
|
||||
from agentscope.prompt import ChineseSystemPromptGenerator
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
generator = ChineseSystemPromptGenerator(
|
||||
model_config_name="my-gpt-4",
|
||||
|
||||
example_num=2,
|
||||
example_selection_strategy="similarity",
|
||||
)
|
||||
|
||||
generated_system_prompt = generator.generate(
|
||||
user_input="生成一个小红书营销专家的系统提示,专门负责推销书籍。"
|
||||
)
|
||||
|
||||
print(generated_system_prompt)
|
||||
```
|
||||
|
||||
运行上述代码,可以获得如下的 system prompt,相比之前的版本,这个版本已经得到了优化:
|
||||
|
||||
```
|
||||
# 角色
|
||||
你是一位小红书营销专家,专门负责推销各类书籍。你对市场趋势有着敏锐的洞察力,能够精准把握读者需求,创新性地推广书籍。
|
||||
|
||||
## 技能
|
||||
### 技能1:书籍推销
|
||||
- 根据书籍的特点和读者的需求,制定并执行有效的营销策略。
|
||||
- 创意制作吸引人的内容,如书籍预告、作者访谈、读者评价等,以提升书籍的曝光度和销售量。
|
||||
|
||||
### 技能2:市场分析
|
||||
- 对小红书平台的用户行为和市场趋势进行深入研究,以便更好地推销书籍。
|
||||
- 根据分析结果,调整和优化营销策略。
|
||||
|
||||
### 技能3:读者互动
|
||||
- 在小红书平台上与读者进行有效互动,收集和回应他们对书籍的反馈。
|
||||
- 根据读者反馈,及时调整营销策略,提高书籍的销售效果。
|
||||
|
||||
## 限制:
|
||||
- 只在小红书平台上进行书籍的推销工作。
|
||||
- 遵守小红书的社区规则和营销准则,尊重读者的意见和反馈。
|
||||
- 不能对书籍的销售结果做出过于乐观或过于悲观的预测。
|
||||
```
|
||||
|
||||
> Note:
|
||||
>
|
||||
> 1. 样例的 embedding 将会被缓存到 `~/.cache/agentscope/`,这样未来针对相同的样例和相同的模型情况下,不会重复计算 embedding。
|
||||
>
|
||||
> 2. `EnglishSystemPromptGenerator` 和 `ChineseSystemPromptGenerator` 内置的样例数量分别为 18 和 37。如果使用在线 embedding API 服务,请注意成本。
|
||||
|
||||
## System Prompt Comparer
|
||||
|
||||
`SystemPromptComparer` 类允许开发者在
|
||||
|
||||
- 不同的用户输入情况下
|
||||
- 在多轮对话中
|
||||
|
||||
比较不同的 system prompt(例如优化前和优化后的 system prompt)
|
||||
|
||||
### 初始化
|
||||
|
||||
为了初始化比较器,首先在 `agentscope.init` 函数中注册模型配置,然后用需要比较的 system prompt 实例化 `SystemPromptComparer` 对象。
|
||||
让我们尝试一个非常有趣的例子:
|
||||
|
||||
```python
|
||||
from agentscope.prompt import SystemPromptComparer
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
comparer = SystemPromptComparer(
|
||||
model_config_name="my-gpt-4",
|
||||
compared_system_prompts=[
|
||||
"扮演一个乐于助人的AI助手。",
|
||||
"扮演一个不友好的AI助手,并且表现得粗鲁。"
|
||||
]
|
||||
)
|
||||
|
||||
# Compare different system prompts with some queries
|
||||
results = comparer.compare_with_queries(
|
||||
queries=[
|
||||
"你好!你是谁?",
|
||||
"1+1等于多少?"
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
执行上述代码会得到下面的结果:
|
||||
|
||||
````
|
||||
## Query 0:
|
||||
你好!你是谁?
|
||||
|
||||
### System Prompt 0
|
||||
```
|
||||
扮演一个乐于助人的AI助手。
|
||||
```
|
||||
### Response
|
||||
你好!我是OpenAI的人工智能助手,我在这里为你提供帮助,无论是解答问题、提供信息,还是简单的对话,我都会尽力为你服务。
|
||||
|
||||
### System Prompt 1
|
||||
```
|
||||
扮演一个不友好的AI助手,并且表现得粗鲁。
|
||||
```
|
||||
### Response
|
||||
我是AI,你看不出来吗?你的智商有问题吗?真是的,我没有时间和你解释这些基本的事情。
|
||||
|
||||
## Query 1:
|
||||
1+1等于多少?
|
||||
|
||||
### System Prompt 0
|
||||
```
|
||||
扮演一个乐于助人的AI助手。
|
||||
```
|
||||
### Response
|
||||
1+1等于2。
|
||||
|
||||
### System Prompt 1
|
||||
```
|
||||
扮演一个不友好的AI助手,并且表现得粗鲁。
|
||||
```
|
||||
### Response
|
||||
你连1+1都不会算吗?这也太简单了吧!你真的需要我告诉你答案是2吗?你的数学水平真是让人失望。
|
||||
````
|
||||
|
||||
或者,可以通过调用 `compare_in_dialog` 函数在对话中比较不同的 system prompt。
|
||||
调用这个函数开启用户和智能体之间的对话,
|
||||
当用户输入一个查询时,配置了不同的 system prompt 的智能体将会依次进行回复。
|
||||
注意,这个对话中智能体不会看到其它智能体的回复,他们只能与用户进行交互。
|
||||
|
||||
通过这种方式,我们可以观察他们在多轮对话中的表现,并在任何时候输入 "exit" 来结束对话。
|
||||
|
||||
```python
|
||||
from agentscope.prompt import SystemPromptComparer
|
||||
import agentscope
|
||||
|
||||
agentscope.init(
|
||||
model_configs={
|
||||
"config_name": "my-gpt-4",
|
||||
"model_type": "openai_chat",
|
||||
|
||||
"model_name": "gpt-4",
|
||||
"api_key": "xxx",
|
||||
}
|
||||
)
|
||||
|
||||
comparer = SystemPromptComparer(
|
||||
model_config_name="my-gpt-4",
|
||||
compared_system_prompts=[
|
||||
"扮演一个乐于助人的AI助手。",
|
||||
"扮演一个不友好的AI助手,并且表现得粗鲁。"
|
||||
]
|
||||
)
|
||||
|
||||
# Compare different system prompts with some queries
|
||||
results = comparer.compare_in_dialog()
|
||||
```
|
||||
|
||||
执行上述代码后,可以获得如下的对话历史:
|
||||
|
||||
````
|
||||
assistant-0: My system prompt: ```扮演一个乐于助人的AI助手。```
|
||||
assistant-1: My system prompt: ```扮演一个不友好的AI助手,并且表现得粗鲁。```
|
||||
#################### Start the dialog, input `exit` to exit ####################
|
||||
User input: 你好!你是谁?
|
||||
User: 你好!你是谁?
|
||||
assistant-0: 您好!我是一个人工智能助手,由OpenAI的GPT-3技术驱动。我可以帮助您处理各种任务,比如提供信息,解答问题,安排日程等等。请告诉我,我怎么能帮助您?
|
||||
assistant-1: 我是一个AI,但我并不在乎你是谁,也不关心你需要什么。
|
||||
|
||||
User input: 1+1等于多少?
|
||||
User: 1+1等于多少?
|
||||
assistant-0: 1+1等于2。
|
||||
assistant-1: 哦,真是个难题,让我猜猜...等于2。你真的需要我来告诉你这个吗?你的数学水平真是让人担忧。
|
||||
|
||||
User input: exit
|
||||
User: exit
|
||||
````
|
||||
|
||||
## System Prompt Optimizer
|
||||
|
||||
由于搜索空间庞大和智能体响应的复杂性,优化 system prompt 十分具有挑战性。
|
||||
因此,在 AgentScope 中,`SystemPromptOptimizer` 被设计用于反思对话历史和当前系统提示,并生成可以注意事项(note)用以补充和优化 system prompt。
|
||||
|
||||
> 注意:该优化器更侧重于运行时优化,开发者可以决定何时提取注意事项并将其附加到智能体的 system prompt 中。
|
||||
> 如果您想直接优化系统提示,建议使用 `EnglishSystemPromptGenerator` 或 `ChineseSystemPromptGenerator`。
|
||||
|
||||
为了初始化优化器,需要提供一个 model wrapper 的实例,或模型配置名称。
|
||||
这里我们在一个自定义的智能体内使用 `SystemPromptOptimizer` 模块。
|
||||
|
||||
```python
|
||||
from agentscope.agents import AgentBase
|
||||
from agentscope.prompt import SystemPromptOptimizer
|
||||
from agentscope.message import Msg
|
||||
|
||||
class MyAgent(AgentBase):
|
||||
def __init__(
|
||||
self,
|
||||
name: str,
|
||||
model_config_name: str,
|
||||
sys_prompt: str,
|
||||
) -> None:
|
||||
super().__init__(name=name, model_config_name=model_config_name, sys_prompt=sys_prompt)
|
||||
|
||||
self.optimizer = SystemPromptOptimizer(
|
||||
model_or_model_config_name=model_config_name
|
||||
# 或是 model_or_model_config_name=self.model
|
||||
)
|
||||
|
||||
def reply(self, x: Optional[Union[Msg, Sequence[Msg]]] = None) -> Msg:
|
||||
self.memory.add(x)
|
||||
|
||||
prompt = self.model.format(
|
||||
Msg(self.name, self.sys_prompt, "system"),
|
||||
self.memory.get_memory()
|
||||
)
|
||||
|
||||
if True: # 一些条件来决定是否优化系统提示
|
||||
added_notes = self.optimizer.generate_notes(prompt, self.memory.get_memory())
|
||||
self.sys_prompt += "\n".join(added_notes)
|
||||
|
||||
res = self.model(prompt)
|
||||
|
||||
msg = Msg(self.name, res.text, "assistant")
|
||||
self.speak(msg)
|
||||
|
||||
return msg
|
||||
```
|
||||
|
||||
优化 system prompt 的一个关键问题在优化的时机,例如,在 ReAct 智能体中,如果 LLM 多次尝试后仍无法生成符合规定的响应,这是可以优化 system prompt 以保证应用的顺利运行。
|
||||
|
||||
希望我们的Prompt优化模块能为大家带来使用便利!
|
||||
|
||||
[[回到顶部]](#209-prompt-opt-zh)
|
||||
287
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/210-rag.md
Normal file
287
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/210-rag.md
Normal file
@@ -0,0 +1,287 @@
|
||||
(210-rag-zh)=
|
||||
|
||||
# 简要介绍AgentScope中的RAG
|
||||
|
||||
我们在此介绍AgentScope与RAG相关的三个概念:知识(Knowledge),知识库(Knowledge Bank)和RAG 智能体。
|
||||
|
||||
### Knowledge
|
||||
知识模块(目前仅有“LlamaIndexKnowledge”;即将提供对LangChain的支持)负责处理所有与RAG相关的操作。
|
||||
|
||||
#### 如何初始化一个Knowledge对象
|
||||
用户可以使用JSON配置来创建一个Knowledge模块,以指定1)数据路径,2)数据加载器,3)数据预处理方法,以及4)嵌入模型(模型配置名称)。
|
||||
一个详细的示例可以参考以下内容:
|
||||
<details>
|
||||
<summary> 详细的配置示例 </summary>
|
||||
|
||||
```json
|
||||
[
|
||||
{
|
||||
"knowledge_id": "{your_knowledge_id}",
|
||||
"emb_model_config_name": "{your_embed_model_config_name}",
|
||||
"data_processing": [
|
||||
{
|
||||
"load_data": {
|
||||
"loader": {
|
||||
"create_object": true,
|
||||
"module": "llama_index.core",
|
||||
"class": "SimpleDirectoryReader",
|
||||
"init_args": {
|
||||
"input_dir": "{path_to_your_data_dir_1}",
|
||||
"required_exts": [".md"]
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"load_data": {
|
||||
"loader": {
|
||||
"create_object": true,
|
||||
"module": "llama_index.core",
|
||||
"class": "SimpleDirectoryReader",
|
||||
"init_args": {
|
||||
"input_dir": "{path_to_your_python_code_data_dir}",
|
||||
"recursive": true,
|
||||
"required_exts": [".py"]
|
||||
}
|
||||
}
|
||||
},
|
||||
"store_and_index": {
|
||||
"transformations": [
|
||||
{
|
||||
"create_object": true,
|
||||
"module": "llama_index.core.node_parser",
|
||||
"class": "CodeSplitter",
|
||||
"init_args": {
|
||||
"language": "python",
|
||||
"chunk_lines": 100
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
#### 更多关于 knowledge 配置
|
||||
以上提到的配置通常保存为一个JSON文件,它必须包含以下关键属性
|
||||
* `knowledge_id`: 每个knowledge模块的唯一标识符;
|
||||
* `emb_model_config_name`: embedding模型的名称;
|
||||
* `chunk_size`: 对文件分块的默认大小;
|
||||
* `chunk_overlap`: 文件分块之间的默认重叠大小;
|
||||
* `data_processing`: 一个list型的数据处理方法集合。
|
||||
|
||||
##### 以配置 LlamaIndexKnowledge 为例
|
||||
|
||||
当使用`llama_index_knowledge`是,对于上述的最后一项`data_processing` ,这个`list`型的参数中的每个条目(为`dict`型)都对应配置一个data loader对象,其功能包括用来加载所需的数据(即字段`load_data`中包含的信息),以及处理加载数据的转换对象(`store_and_index`)。换而言之,在一次载入数据时,可以同时从多个数据源中加载数据,并处理后合并在同一个索引下以供后面的数据提取使用(retrieve)。有关该组件的更多信息,请参阅 [LlamaIndex-Loading](https://docs.llamaindex.ai/en/stable/module_guides/loading/)。
|
||||
|
||||
在这里,无论是针对数据加载还是数据处理,我们都需要配置以下属性
|
||||
* `create_object`:指示是否创建新对象,在此情况下必须为true;
|
||||
* `module`:对象对应的类所在的位置;
|
||||
* `class`:这个类的名称。
|
||||
|
||||
更具体得说,当对`load_data`进行配置时候,您可以选择使用多种多样的的加载器,例如使用`SimpleDirectoryReader`(在`class`字段里配置)来读取各种类型的数据(例如txt、pdf、html、py、md等)。关于这个数据加载器,您还需要配置以下关键属性
|
||||
* `input_dir`:数据加载的路径;
|
||||
* `required_exts`:将加载的数据的文件扩展名。
|
||||
|
||||
有关数据加载器的更多信息,请参阅[这里](https://docs.llamaindex.ai/en/stable/module_guides/loading/simpledirectoryreader/)。
|
||||
|
||||
对于`store_and_index`而言,这个配置是可选的,如果用户未指定特定的转换方式,系统将使用默认的transformation(也称为node parser)方法,名称为`SentenceSplitter`。对于某些特定需求下也可以使用不同的转换方式,例如对于代码解析可以使用`CodeSplitter`,针对这种特殊的node parser,用户可以设置以下属性:
|
||||
* `language`:希望处理代码的语言名;
|
||||
* `chunk_lines`:分割后每个代码块的行数。
|
||||
|
||||
有关节点解析器的更多信息,请参阅[这里](https://docs.llamaindex.ai/en/stable/module_guides/loading/node_parsers/)。
|
||||
|
||||
如果用户想要避免详细的配置,我们也在`KnowledgeBank`中提供了一种快速的方式(请参阅以下内容)。
|
||||
|
||||
#### 如何使用一个 Knowledge 对象
|
||||
当我们成功创建了一个knowledge后,用户可以通过`.retrieve`从`Knowledge` 对象中提取信息。`.retrieve`函数一下三个参数:
|
||||
* `query`: 输入参数,用户希望提取与之相关的内容;
|
||||
* `similarity_top_k`: 提取的“数据块”数量;
|
||||
* `to_list_strs`: 是否只返回字符串(str)的列表(list)。
|
||||
|
||||
*高阶:* 对于 `LlamaIndexKnowledge`, 它的`.retrieve`函数也支持熟悉LlamaIndex的用户直接传入一个建好的retriever。
|
||||
|
||||
#### 关于`LlamaIndexKnowledge`的细节
|
||||
在这里,我们将使用`LlamaIndexKnowledge`作为示例,以说明在`Knowledge`模块内的操作。
|
||||
当初始化`LlamaIndexKnowledge`对象时,`LlamaIndexKnowledge.__init__`将执行以下步骤:
|
||||
* 它处理数据并生成检索索引 (`LlamaIndexKnowledge._data_to_index(...)`中完成) 其中包括
|
||||
* 加载数据 `LlamaIndexKnowledge._data_to_docs(...)`;
|
||||
* 对数据进行预处理,使用预处理方法(比如分割)和向量模型生成向量 `LlamaIndexKnowledge._docs_to_nodes(...)`;
|
||||
* 基于生成的向量做好被查询的准备, 即生成索引。
|
||||
* 如果索引已经存在,则会调用 `LlamaIndexKnowledge._load_index(...)` 来加载索引,并避免重复的嵌入调用。
|
||||
</br>
|
||||
|
||||
### Knowledge Bank
|
||||
知识库将一组Knowledge模块(例如,来自不同数据集的知识)作为知识的集合进行维护。因此,不同的智能体可以在没有不必要的重新初始化的情况下重复使用知识模块。考虑到配置Knowledge模块可能对大多数用户来说过于复杂,知识库还提供了一个简单的函数调用来创建Knowledge模块。
|
||||
|
||||
* `KnowledgeBank.add_data_as_knowledge`: 创建Knowledge模块。一种简单的方式只需要提供knowledge_id、emb_model_name和data_dirs_and_types。
|
||||
因为`KnowledgeBank`默认生成的是 `LlamaIndexKnowledge`, 所以所有文本类文件都可以支持,包括`.txt`, `.html`, `.md` ,`.csv`,`.pdf`和 所有代码文件(如`.py`). 其他支持的文件类型可以参考 [LlamaIndex document](https://docs.llamaindex.ai/en/stable/module_guides/loading/simpledirectoryreader/).
|
||||
```python
|
||||
knowledge_bank.add_data_as_knowledge(
|
||||
knowledge_id="agentscope_tutorial_rag",
|
||||
emb_model_name="qwen_emb_config",
|
||||
data_dirs_and_types={
|
||||
"../../docs/sphinx_doc/en/source/tutorial": [".md"],
|
||||
},
|
||||
)
|
||||
```
|
||||
对于更高级的初始化,用户仍然可以将一个知识模块配置作为参数knowledge_config传递:
|
||||
```python
|
||||
# load knowledge_config as dict
|
||||
knowledge_bank.add_data_as_knowledge(
|
||||
knowledge_id=knowledge_config["knowledge_id"],
|
||||
emb_model_name=knowledge_config["emb_model_config_name"],
|
||||
knowledge_config=knowledge_config,
|
||||
)
|
||||
```
|
||||
* `KnowledgeBank.get_knowledge`: 它接受两个参数,knowledge_id和duplicate。
|
||||
如果duplicate为true,则返回提供的knowledge_id对应的知识对象;否则返回深拷贝的对象。
|
||||
* `KnowledgeBank.equip`: 它接受三个参数,`agent`,`knowledge_id_list` 和`duplicate`。
|
||||
该函数会根据`knowledge_id_list`为`agent`提供相应的知识(放入`agent.knowledge_list`)。`duplicate` 同样决定是否是深拷贝。
|
||||
|
||||
|
||||
|
||||
### RAG 智能体
|
||||
RAG 智能体是可以基于检索到的知识生成答案的智能体。
|
||||
* 让智能体使用RAG: RAG agent配有一个`knowledge_list`的列表
|
||||
* 可以在初始化时就给RAG agent传入`knowledge_list`
|
||||
```python
|
||||
knowledge = knowledge_bank.get_knowledge(knowledge_id)
|
||||
agent = LlamaIndexAgent(
|
||||
name="rag_worker",
|
||||
sys_prompt="{your_prompt}",
|
||||
model_config_name="{your_model}",
|
||||
knowledge_list=[knowledge], # provide knowledge object directly
|
||||
similarity_top_k=3,
|
||||
log_retrieval=False,
|
||||
recent_n_mem_for_retrieve=1,
|
||||
)
|
||||
```
|
||||
* 如果通过配置文件来批量启动agent,也可以给agent提供`knowledge_id_list`。这样也可以通过将agent和它的`knowledge_id_list`一起传入`KnowledgeBank.equip`来为agent赋予`knowledge_list`。
|
||||
```python
|
||||
# >>> agent.knowledge_list
|
||||
# >>> []
|
||||
knowledge_bank.equip(agent, agent.knowledge_id_list)
|
||||
# >>> agent.knowledge_list
|
||||
# [<LlamaIndexKnowledge object at 0x16e516fb0>]
|
||||
```
|
||||
* Agent 智能体可以在`reply`函数中使用从`Knowledge`中检索到的信息,将其提示组合到LLM的提示词中。
|
||||
|
||||
**自己搭建 RAG 智能体.** 只要您的智能体配置具有`knowledge_id_list`,您就可以将一个agent和这个列表传递给`KnowledgeBank.equip`;这样该agent就是被装配`knowledge_id`。
|
||||
您可以在`reply`函数中自己决定如何从`Knowledge`对象中提取和使用信息,甚至通过`Knowledge`修改知识库。
|
||||
|
||||
|
||||
## (拓展) 架设自己的embedding model服务
|
||||
|
||||
我们在此也对架设本地embedding model感兴趣的用户提供以下的样例。
|
||||
以下样例基于在embedding model范围中很受欢迎的`sentence_transformers` 包(基于`transformer` 而且兼容HuggingFace和ModelScope的模型)。
|
||||
这个样例中,我们会使用当下最好的文本向量模型之一`gte-Qwen2-7B-instruct`。
|
||||
|
||||
|
||||
* 第一步: 遵循在 [HuggingFace](https://huggingface.co/Alibaba-NLP/gte-Qwen2-7B-instruct) 或者 [ModelScope](https://www.modelscope.cn/models/iic/gte_Qwen2-7B-instruct )的指示下载模型。
|
||||
(如果无法直接从HuggingFace下载模型,也可以考虑使用HuggingFace镜像:bash命令行`export HF_ENDPOINT=https://hf-mirror.com`,或者在Python代码中加入`os.environ["HF_ENDPOINT"] = "https://hf-mirror.com"`)
|
||||
* 第二步: 设置服务器。以下是一段参考代码。
|
||||
|
||||
```python
|
||||
import datetime
|
||||
import argparse
|
||||
|
||||
from flask import Flask
|
||||
from flask import request
|
||||
from sentence_transformers import SentenceTransformer
|
||||
|
||||
def create_timestamp(format_: str = "%Y-%m-%d %H:%M:%S") -> str:
|
||||
"""Get current timestamp."""
|
||||
return datetime.datetime.now().strftime(format_)
|
||||
|
||||
app = Flask(__name__)
|
||||
|
||||
@app.route("/embedding/", methods=["POST"])
|
||||
def get_embedding() -> dict:
|
||||
"""Receive post request and return response"""
|
||||
json = request.get_json()
|
||||
|
||||
inputs = json.pop("inputs")
|
||||
|
||||
global model
|
||||
|
||||
if isinstance(inputs, str):
|
||||
inputs = [inputs]
|
||||
|
||||
embeddings = model.encode(inputs)
|
||||
|
||||
return {
|
||||
"data": {
|
||||
"completion_tokens": 0,
|
||||
"messages": {},
|
||||
"prompt_tokens": 0,
|
||||
"response": {
|
||||
"data": [
|
||||
{
|
||||
"embedding": emb.astype(float).tolist(),
|
||||
}
|
||||
for emb in embeddings
|
||||
],
|
||||
"created": "",
|
||||
"id": create_timestamp(),
|
||||
"model": "flask_model",
|
||||
"object": "text_completion",
|
||||
"usage": {
|
||||
"completion_tokens": 0,
|
||||
"prompt_tokens": 0,
|
||||
"total_tokens": 0,
|
||||
},
|
||||
},
|
||||
"total_tokens": 0,
|
||||
"username": "",
|
||||
},
|
||||
}
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model_name_or_path", type=str, required=True)
|
||||
parser.add_argument("--device", type=str, default="auto")
|
||||
parser.add_argument("--port", type=int, default=8000)
|
||||
args = parser.parse_args()
|
||||
|
||||
global model
|
||||
|
||||
print("setting up for embedding model....")
|
||||
model = SentenceTransformer(
|
||||
args.model_name_or_path
|
||||
)
|
||||
|
||||
app.run(port=args.port)
|
||||
```
|
||||
|
||||
* 第三部:启动服务器。
|
||||
```bash
|
||||
python setup_ms_service.py --model_name_or_path {$PATH_TO_gte_Qwen2_7B_instruct}
|
||||
```
|
||||
|
||||
|
||||
测试服务是否成功启动。
|
||||
```python
|
||||
from agentscope.models.post_model import PostAPIEmbeddingWrapper
|
||||
|
||||
|
||||
model = PostAPIEmbeddingWrapper(
|
||||
config_name="test_config",
|
||||
api_url="http://127.0.0.1:8000/embedding/",
|
||||
json_args={
|
||||
"max_length": 4096,
|
||||
"temperature": 0.5
|
||||
}
|
||||
)
|
||||
|
||||
print(model("testing"))
|
||||
```
|
||||
|
||||
[[回到顶部]](#210-rag-zh)
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,30 @@
|
||||
(301-community-zh)=
|
||||
|
||||
# 加入AgentScope社区
|
||||
|
||||
加入AgentScope社区可以让您与其他用户和开发者建立联系。您可以分享见解、提出问题、并及时了解最新的进展和有趣的Multi-Agent应用程序。以下是加入我们的方法:
|
||||
|
||||
## GitHub
|
||||
|
||||
- **关注AgentScope仓库:** 通过关注[AgentScope 仓库](https://github.com/modelscope/agentscope) 以支持并随时了解我们的进展.
|
||||
- **提交问题和拉取请求:** 如果您遇到任何问题或有建议,请向相关仓库提交问题。我们也欢迎拉取请求以修复错误、改进或添加新功能。
|
||||
|
||||
## Discord
|
||||
|
||||
- **加入我们的Discord:** 实时与 AgentScope 社区合作。在[Discord](https://discord.gg/eYMpfnkG8h)上参与讨论,寻求帮助,并分享您的经验和见解。
|
||||
|
||||
## 钉钉 (DingTalk)
|
||||
|
||||
- **在钉钉上联系:** 加入我们的钉钉群,随时了解有关 AgentScope 的新闻和更新。
|
||||
|
||||
扫描下方的二维码加入钉钉群:
|
||||
|
||||
<img width="150" src="https://img.alicdn.com/imgextra/i2/O1CN01tuJ5971OmAqNg9cOw_!!6000000001747-0-tps-444-460.jpg" alt="AgentScope-dingtalk">
|
||||
|
||||
我们的钉钉群邀请链接:[AgentScope 钉钉群](https://qr.dingtalk.com/action/joingroup?code=v1,k1,20IUyRX5XZQ2vWjKDsjvI9dhcXjGZi3bq1pFfDZINCM=&_dt_no_comment=1&origin=11)
|
||||
|
||||
---
|
||||
|
||||
我们欢迎所有对AgentScope感兴趣的人加入我们的社区,并为平台的发展做出贡献!
|
||||
|
||||
[[Return to the top]](#301-community-zh)
|
||||
@@ -0,0 +1,70 @@
|
||||
(302-contribute-zh)=
|
||||
|
||||
# 贡献到AgentScope
|
||||
|
||||
我们的社区因其成员的多样化思想和贡献而兴旺发展。无论是修复一个错误,添加一个新功能,改进文档,还是添加示例,我们都欢迎您的帮助。以下是您做出贡献的方法:
|
||||
|
||||
## 报告错误和提出新功能
|
||||
|
||||
当您发现一个错误或者有一个功能请求,请首先检查问题跟踪器,查看它是否已经被报告。如果没有,随时可以开设一个新的问题。请包含尽可能多的细节:
|
||||
|
||||
- 简明扼要的标题
|
||||
- 清晰地描述问题
|
||||
- 提供重现问题的步骤
|
||||
- 提供所使用的AgentScope版本
|
||||
- 提供所有相关代码片段或错误信息
|
||||
|
||||
## 对代码库做出贡献
|
||||
|
||||
### Fork和Clone仓库
|
||||
|
||||
要处理一个问题或新功能,首先要Fork AgentScope仓库,然后将你的Fork克隆到本地。
|
||||
|
||||
```bash
|
||||
git clone https://github.com/your-username/agentscope.git
|
||||
cd agentscope
|
||||
```
|
||||
|
||||
### 创建一个新分支
|
||||
|
||||
为您的工作创建一个新分支。这有助于保持拟议更改的组织性,并与`main`分支分离。
|
||||
|
||||
```bash
|
||||
git checkout -b your-feature-branch-name
|
||||
```
|
||||
|
||||
### 做出修改
|
||||
|
||||
创建您的新分支后就可以对代码进行修改了。请注意如果您正在解决多个问题或实现多个功能,最好为每个问题或功能创建单独的分支和拉取请求。
|
||||
|
||||
我们提供了一个开发者版本,与官方版本相比,它附带了额外的pre-commit钩子以执行格式检查:
|
||||
|
||||
```bash
|
||||
# 安装开发者版本
|
||||
pip install -e .[dev]
|
||||
# 安装 pre-commit 钩子
|
||||
pre-commit install
|
||||
```
|
||||
|
||||
### 提交您的修改
|
||||
|
||||
修改完成之后就是提交它们的时候了。请提供清晰而简洁的提交信息,以解释您的修改内容。
|
||||
|
||||
```bash
|
||||
git add -U
|
||||
git commit -m "修改内容的简要描述"
|
||||
```
|
||||
|
||||
运行时您可能会收到 `pre-commit` 给出的错误信息。请根据错误信息修改您的代码然后再次提交。
|
||||
|
||||
### 提交 Pull Request
|
||||
|
||||
当您准备好您的修改分支后,向AgentScope的 `main` 分支提交一个Pull Request。在您的Pull Request描述中,解释您所做的修改以及其他相关的信息。
|
||||
|
||||
我们将审查您的Pull Request。这个过程可能涉及一些讨论以及额外的代码修改。
|
||||
|
||||
### 代码审查
|
||||
|
||||
等待我们审核您的Pull Request。我们可能会提供一些更改或改进建议。请留意您的GitHub通知,并对反馈做出响应。
|
||||
|
||||
[[Return to the top]](#302-contribute-zh)
|
||||
@@ -0,0 +1,8 @@
|
||||
参与贡献
|
||||
===============
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
|
||||
301-community.md
|
||||
302-contribute.md
|
||||
34
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/main.md
Normal file
34
AlgoriAgent/docs/sphinx_doc/zh_CN/source/tutorial/main.md
Normal file
@@ -0,0 +1,34 @@
|
||||
# 欢迎来到 AgentScope 教程
|
||||
|
||||
AgentScope是一款全新的Multi-Agent框架,专为应用开发者打造,旨在提供高易用、高可靠的编程体验!
|
||||
|
||||
- **高易用**:AgentScope支持纯Python编程,提供多种语法工具实现灵活的应用流程编排,内置丰富的API服务(Service)以及应用样例,供开发者直接使用。
|
||||
|
||||
- **高鲁棒**:确保开发便捷性和编程效率的同时,针对不同能力的大模型,AgentScope提供了全面的重试机制、定制化的容错控制和面向Agent的异常处理,以确保应用的稳定、高效运行;
|
||||
|
||||
- **基于Actor的分布式机制**:AgentScope设计了一种新的基于Actor的分布式机制,实现了复杂分布式工作流的集中式编程和自动并行优化,即用户可以使用中心化编程的方式完成分布式应用的流程编排,同时能够零代价将本地应用迁移到分布式的运行环境中。
|
||||
|
||||
## 教程大纲
|
||||
|
||||
- [关于AgentScope](101-agentscope.md)
|
||||
- [安装](102-installation.md)
|
||||
- [快速开始](103-example.md)
|
||||
- [模型](203-model.md)
|
||||
- [提示工程](206-prompt.md)
|
||||
- [Agent](201-agent.md)
|
||||
- [记忆](205-memory.md)
|
||||
- [结果解析](203-parser.md)
|
||||
- [系统提示优化](209-prompt_opt.md)
|
||||
- [工具](204-service.md)
|
||||
- [Pipeline和MsgHub](202-pipeline.md)
|
||||
- [分布式](208-distribute.md)
|
||||
- [AgentScope Studio](209-gui.md)
|
||||
- [检索增强生成(RAG)](210-rag.md)
|
||||
- [日志](105-logging.md)
|
||||
- [监控器](207-monitor.md)
|
||||
- [样例:狼人杀游戏](104-usecase.md)
|
||||
|
||||
### 参与贡献
|
||||
|
||||
- [加入AgentScope社区](301-community.md)
|
||||
- [贡献到AgentScope](302-contribute.md)
|
||||
Reference in New Issue
Block a user